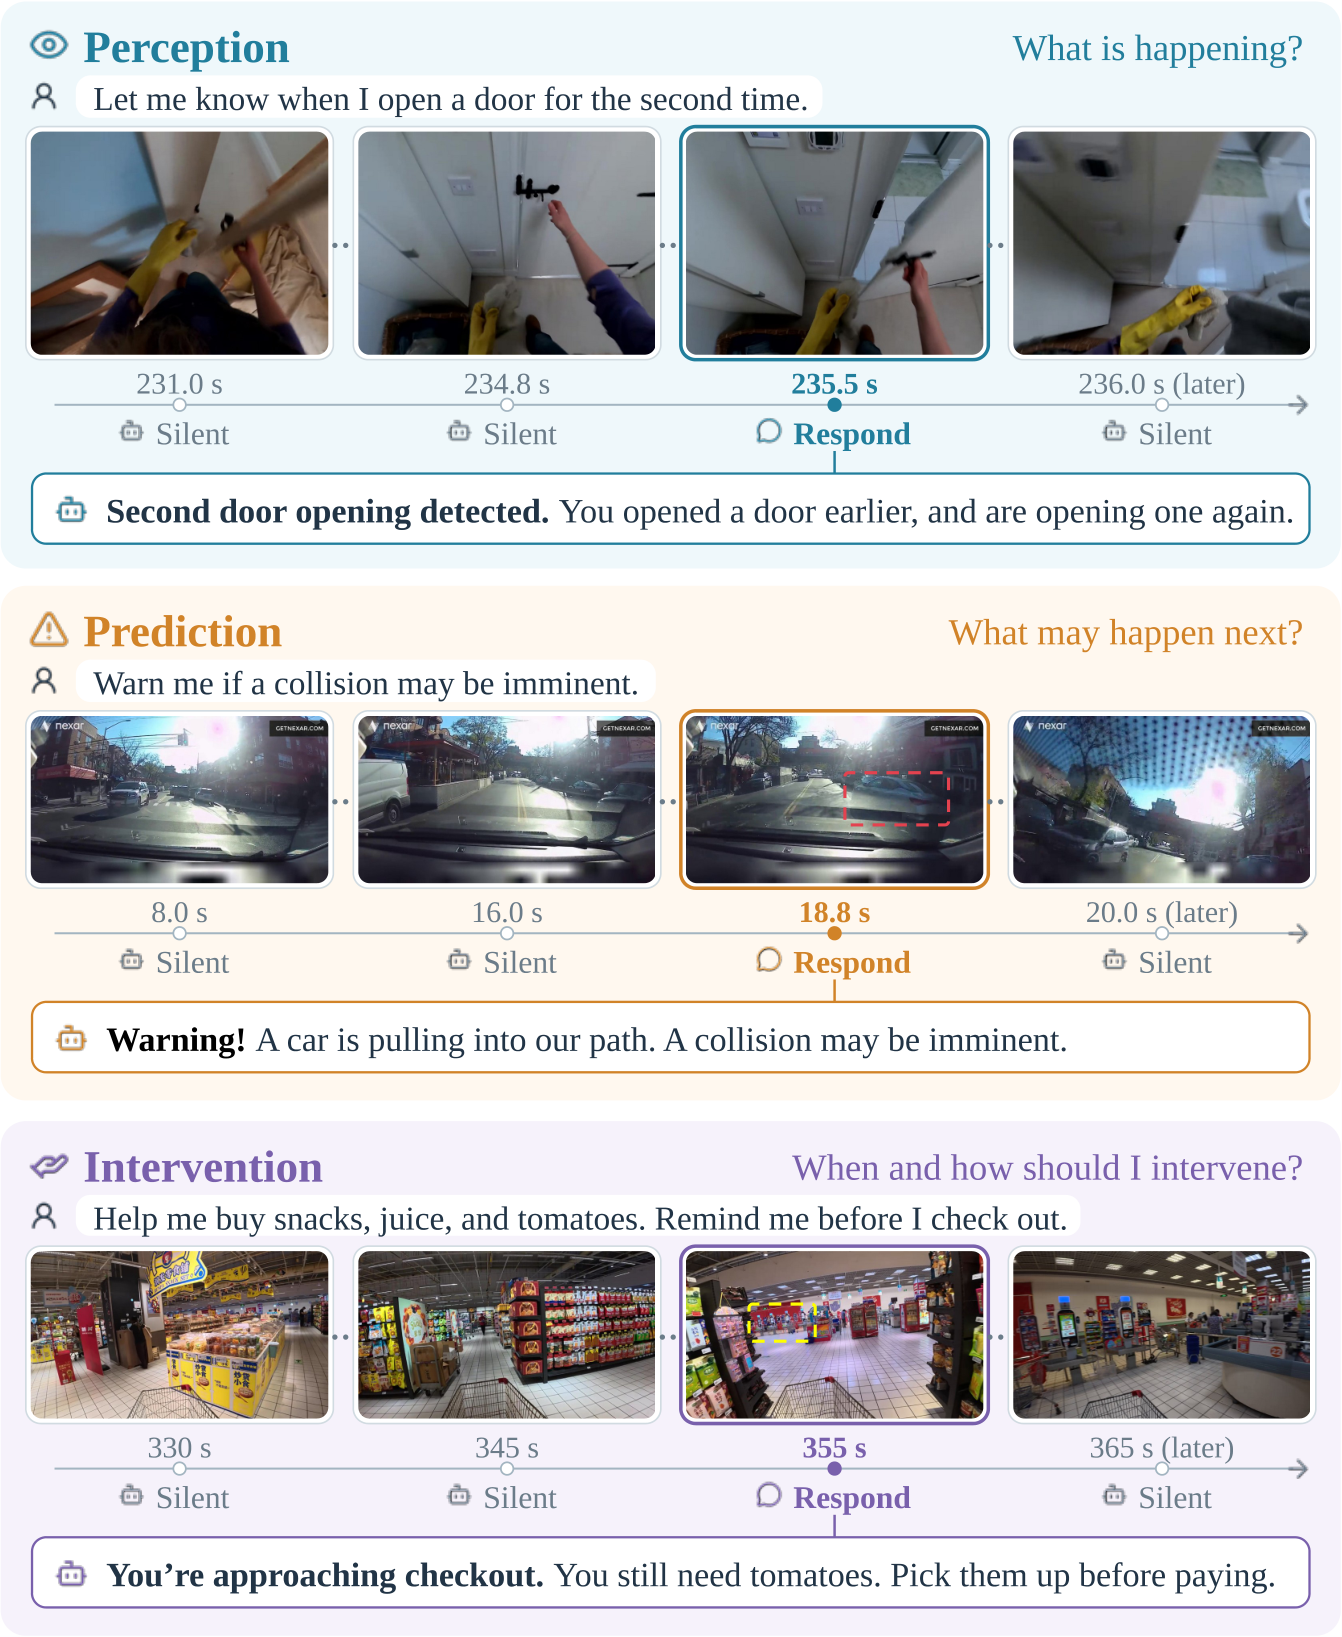
Evaluate perception, hazard prediction and intervention with content-plus-timing scores and redundant-response penalties. SFT + RL trains a Qwen3-VL-4B response/silence policy.
Editorial summary · not the author abstract. Read the linked paper for the complete abstract and claims.P3IBench overview of perception, prediction and intervention capabilities Original figure · paper authors ↗
Release evidence
Inference/evaluation scripts and ungated benchmark JSON/video files are public. No P3I-Assistant-4B checkpoint or training pipeline was verified in the linked repositories.