 Original figure · paper authors ↗
Benchmarks
Datasets and evaluation suites for proactive agents.
/
Original figure · paper authors ↗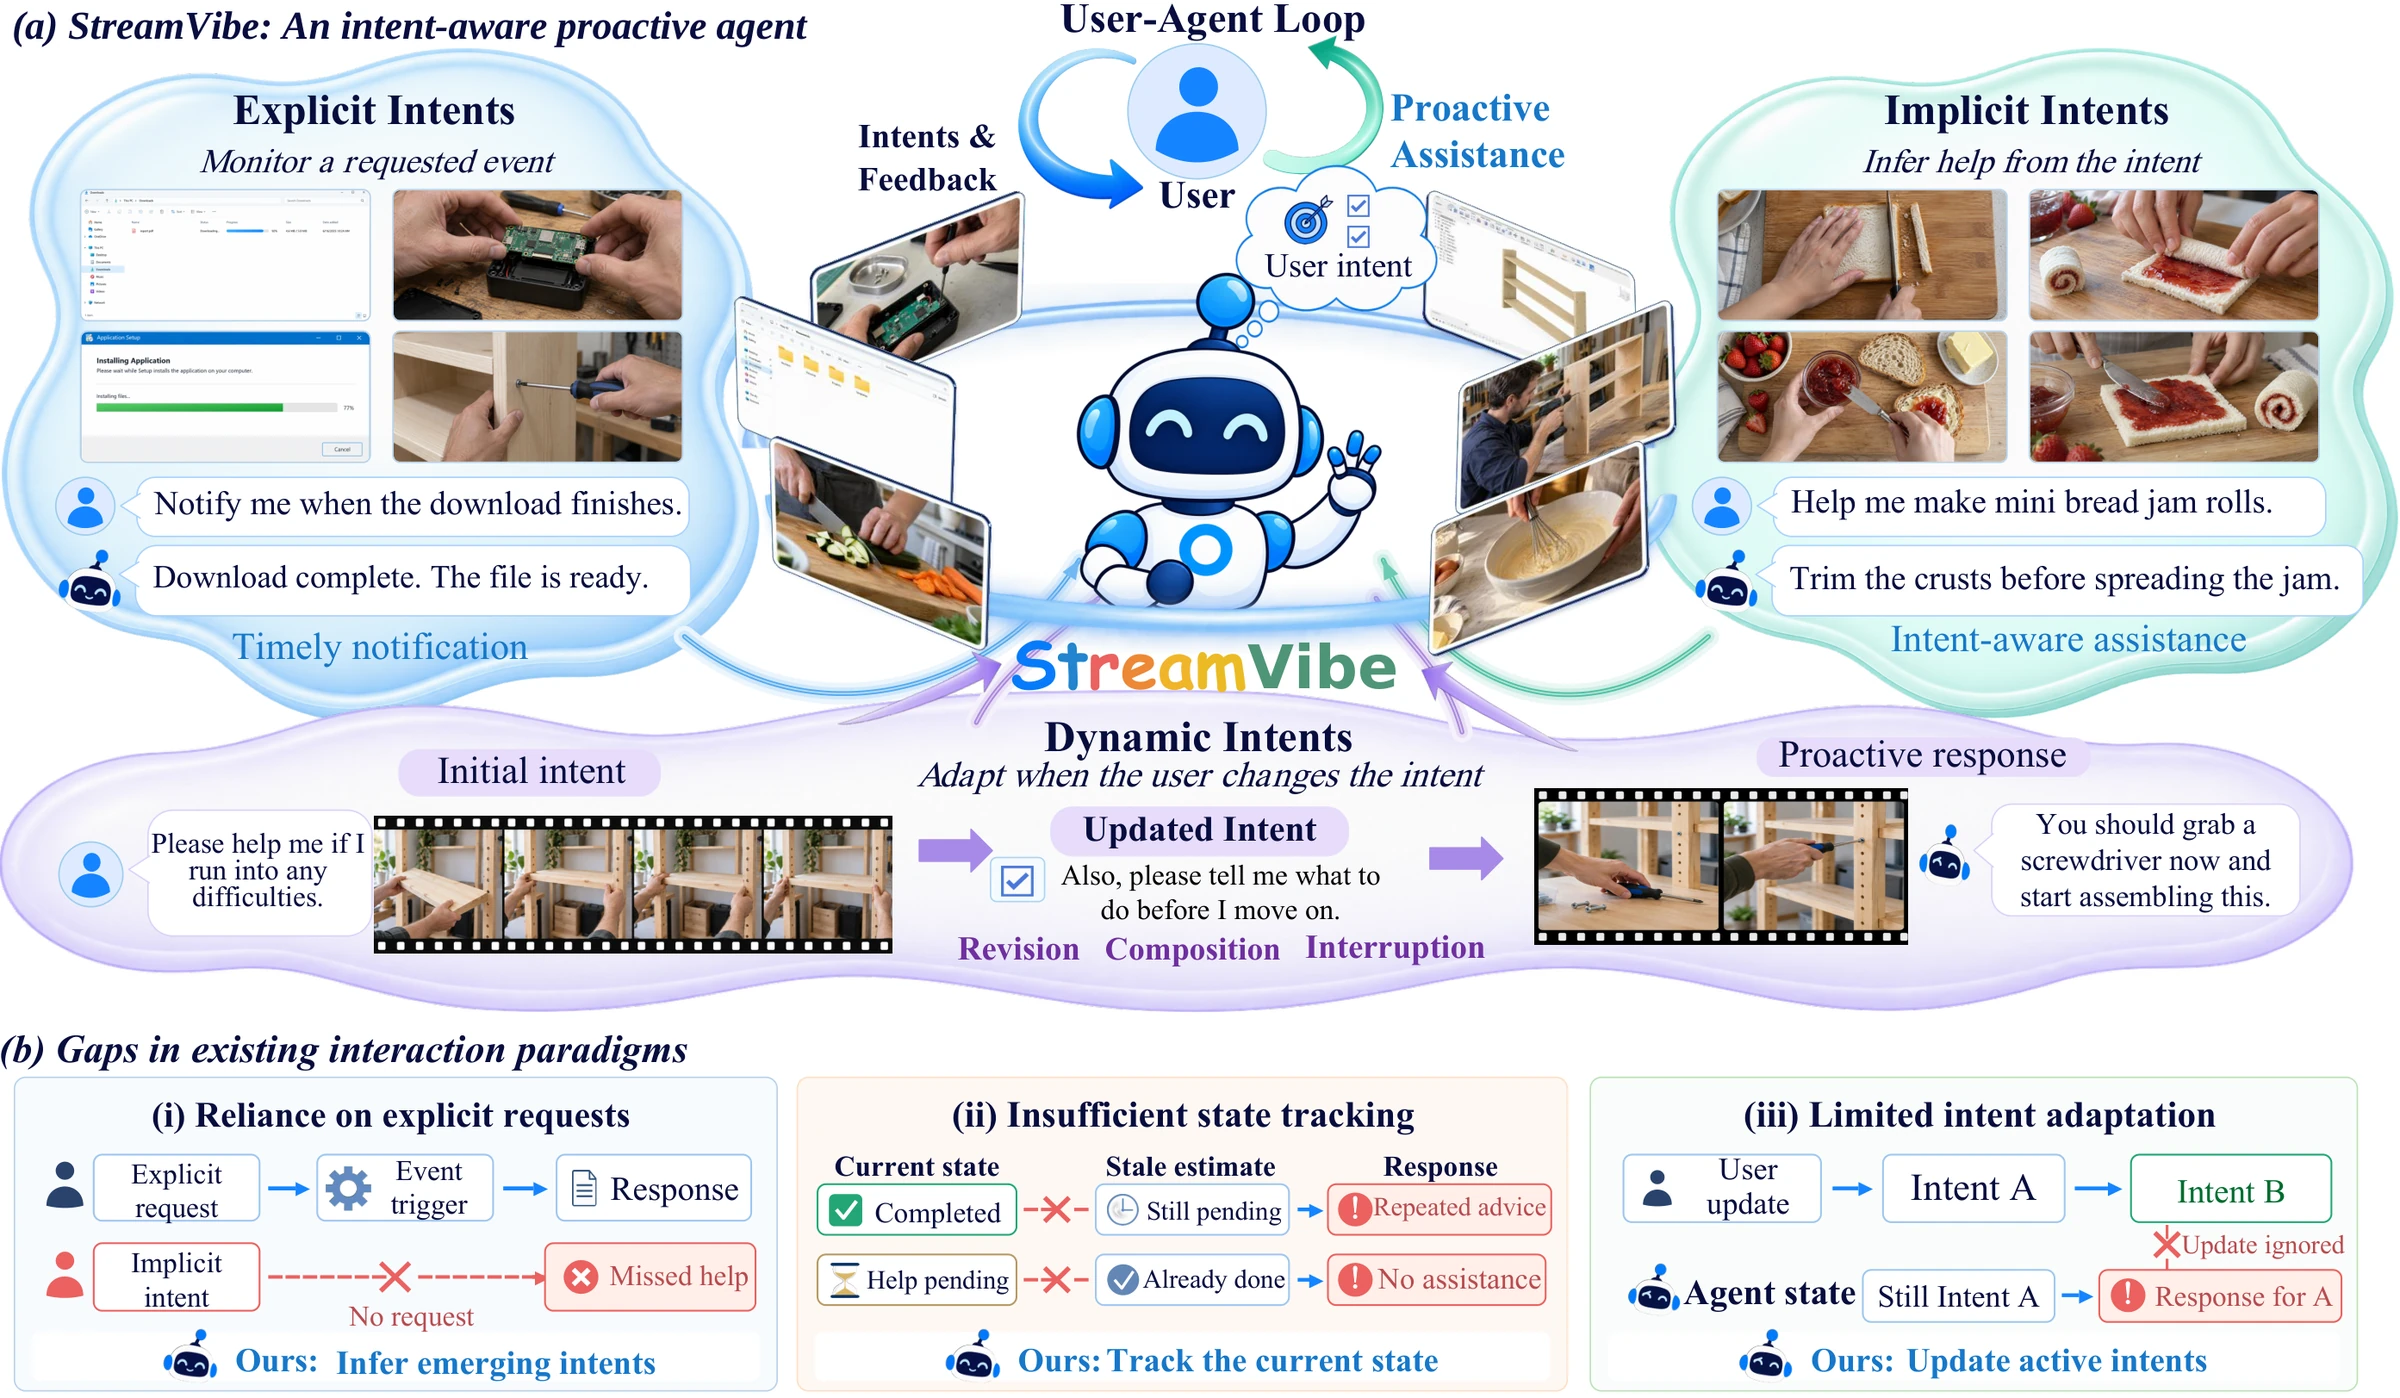 Original figure · paper authors ↗
StreamVibe-Bench
StreamVibe
 Original figure · paper authors ↗
HALO-Arena / HALO-8K
HALO
 Original figure · paper authors ↗
 Paper Figure 1 · authors ↗
ProactiveStream
ProactMem
 Original figure · paper authors ↗
 Original figure · paper authors ↗
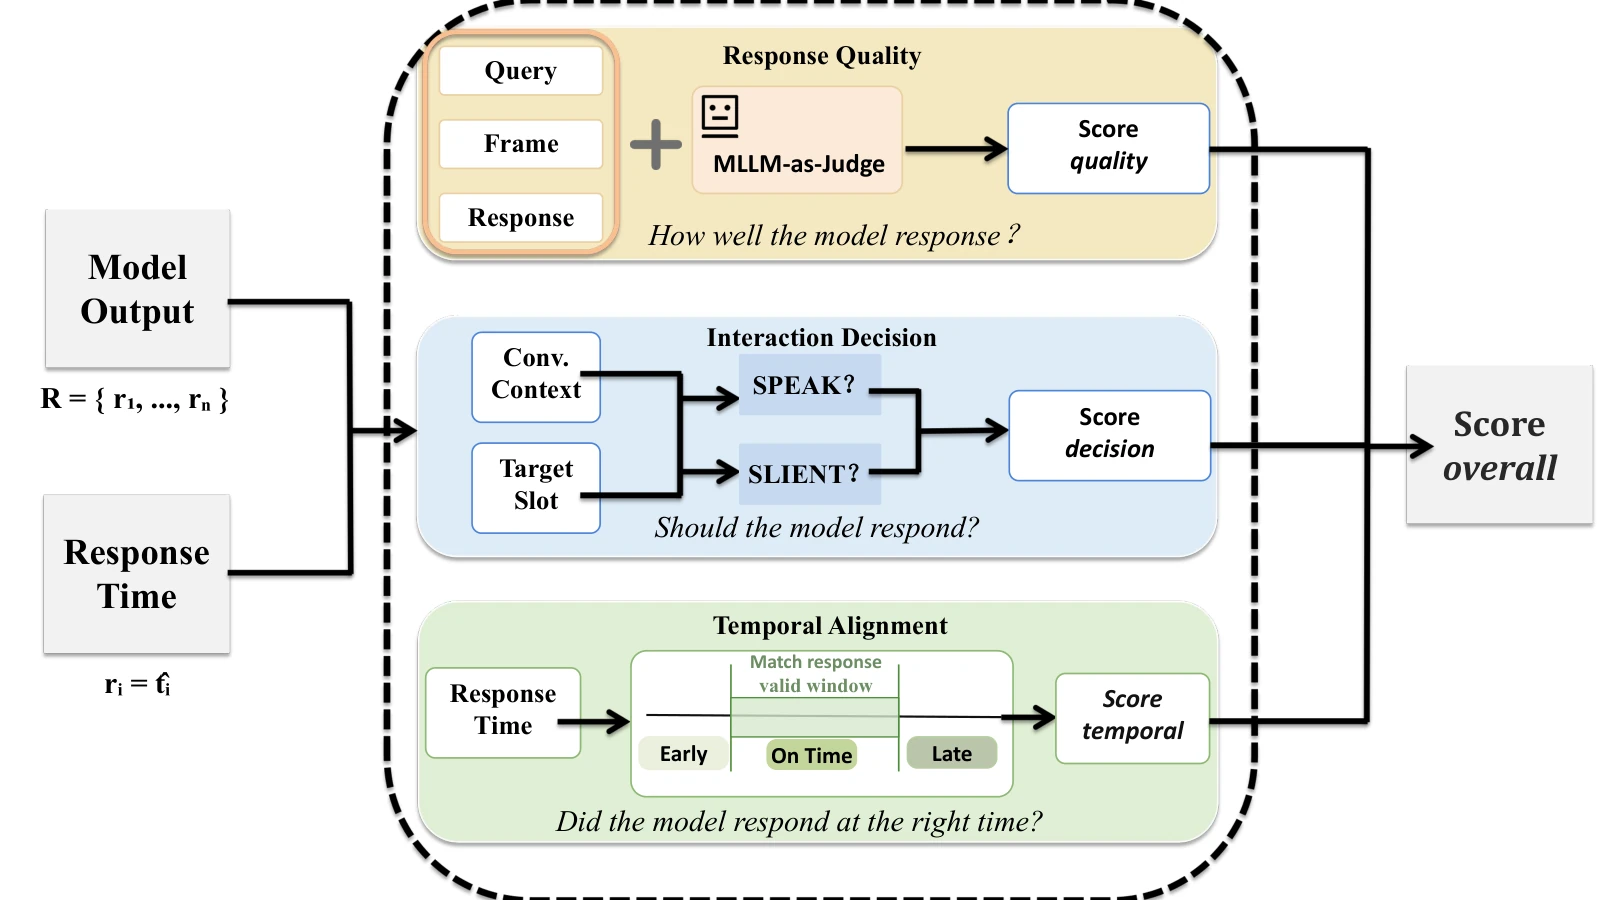 Paper Figure 4 · authors ↗
 Original figure · paper authors ↗
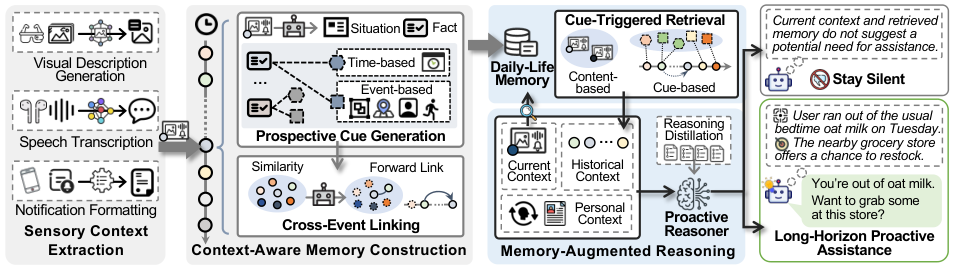
CPMBench
ProMemAgent
 Original figure · paper authors ↗
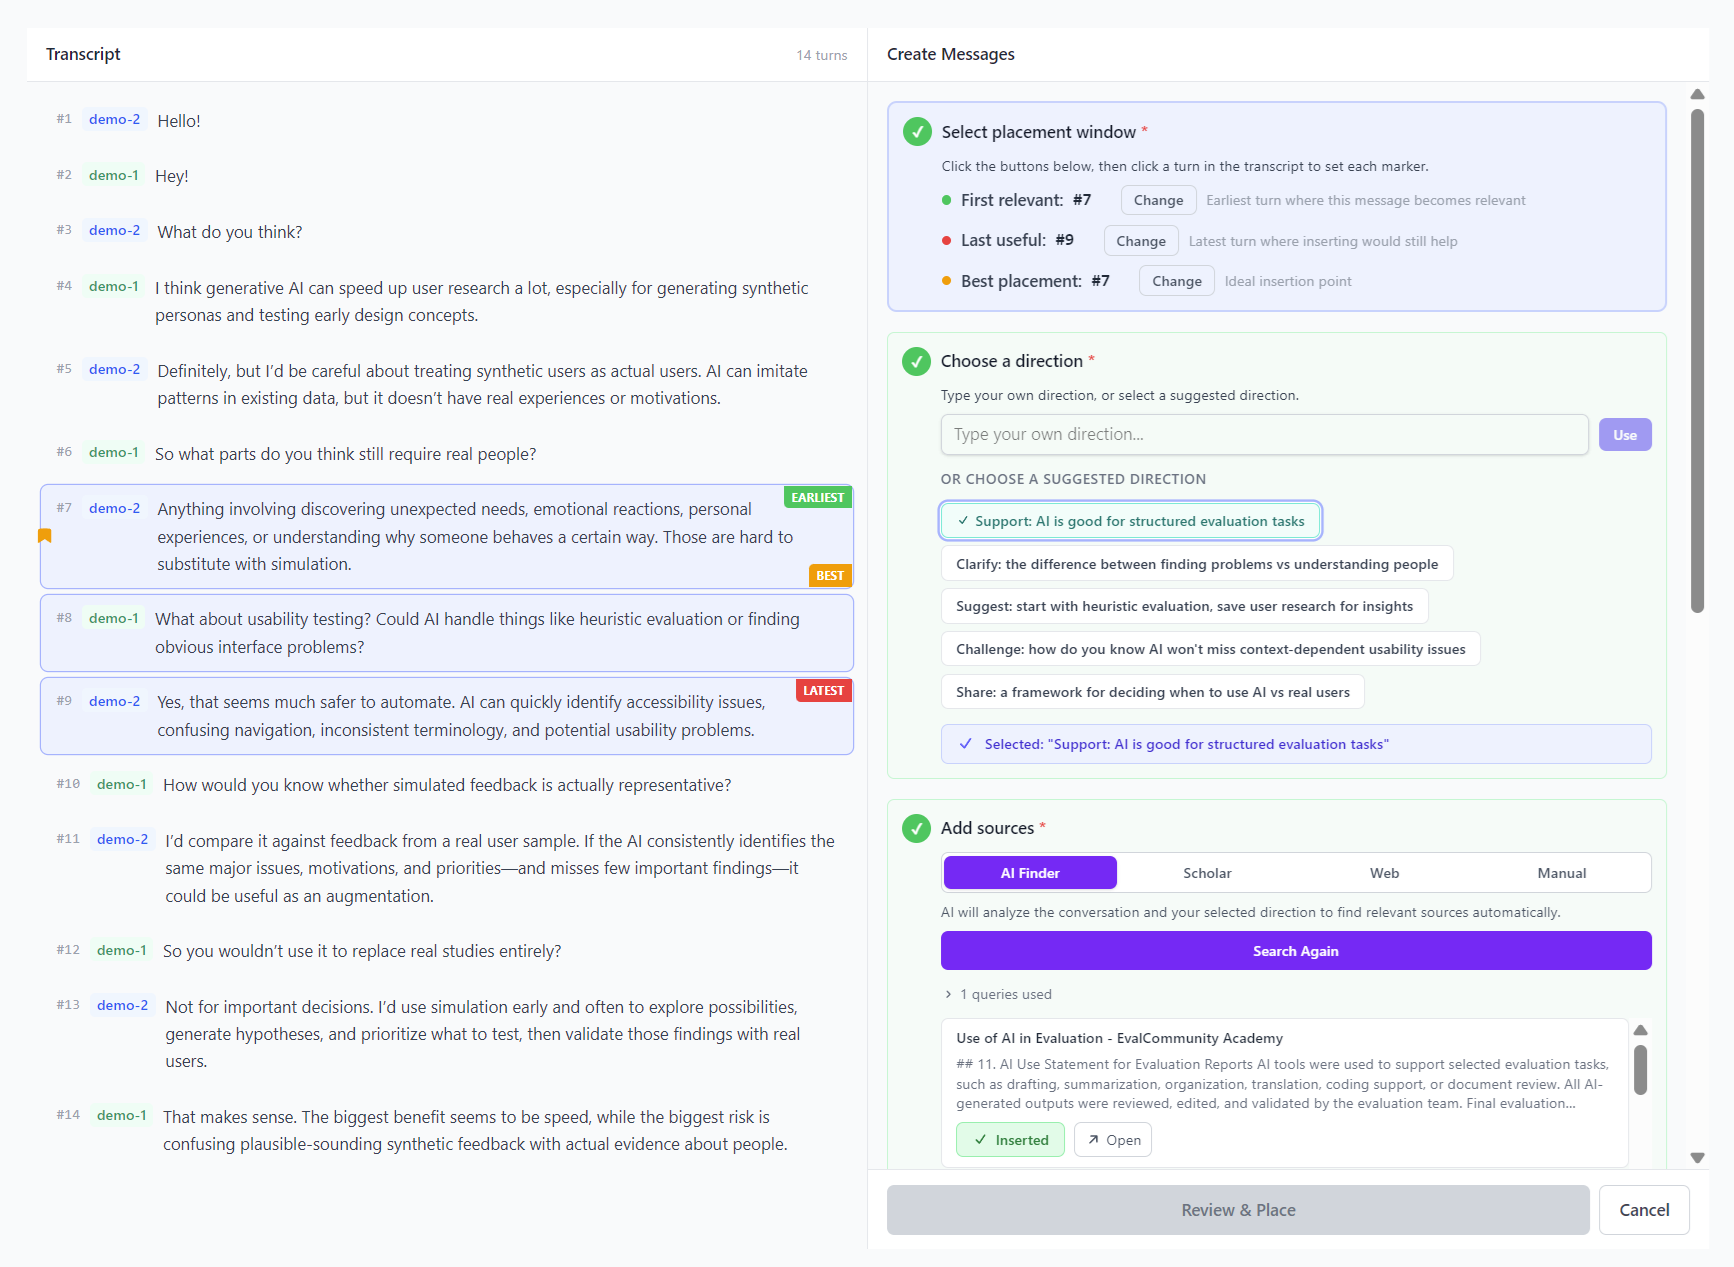
PITCH
When Should AI Chime In?
 Original figure · paper authors ↗
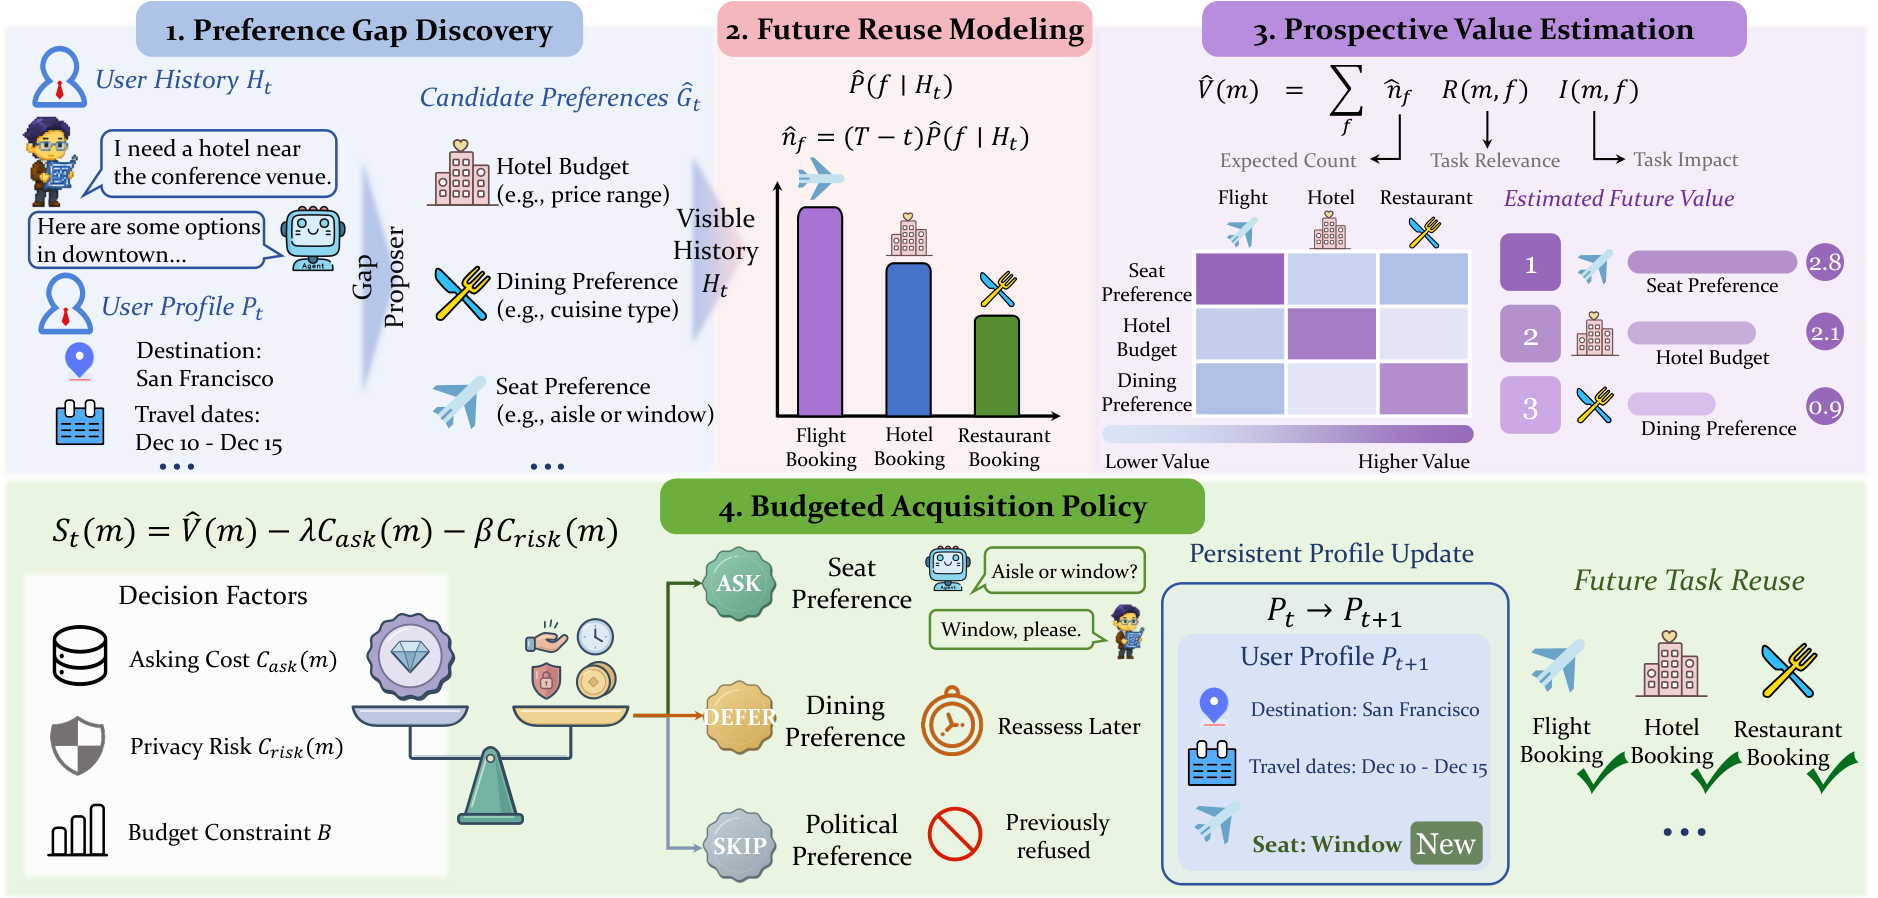
ActiveWebPref
Active Preference Acquisition
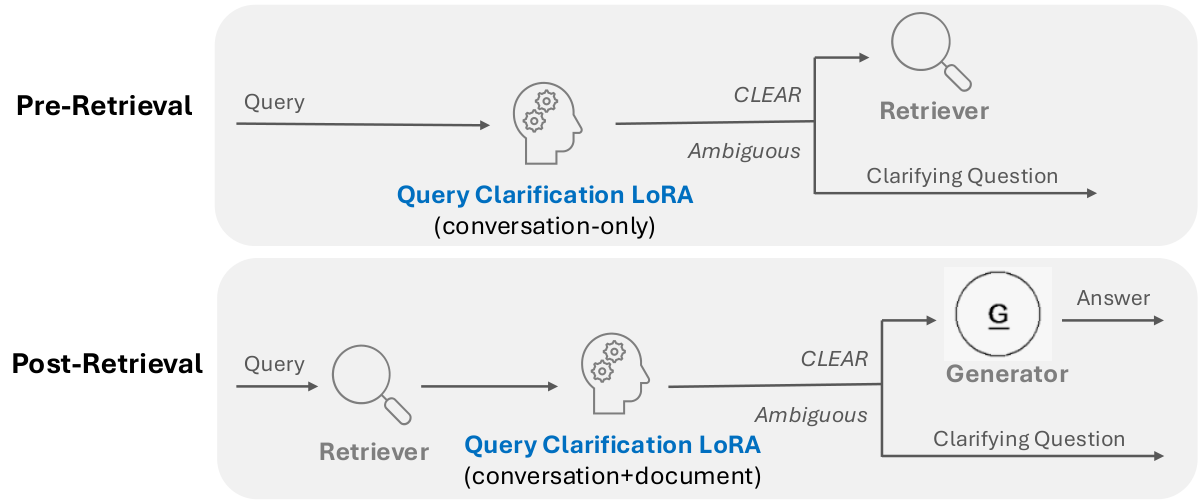 Original figure · paper authors ↗
ClariEdge
A Small Model Asks Better
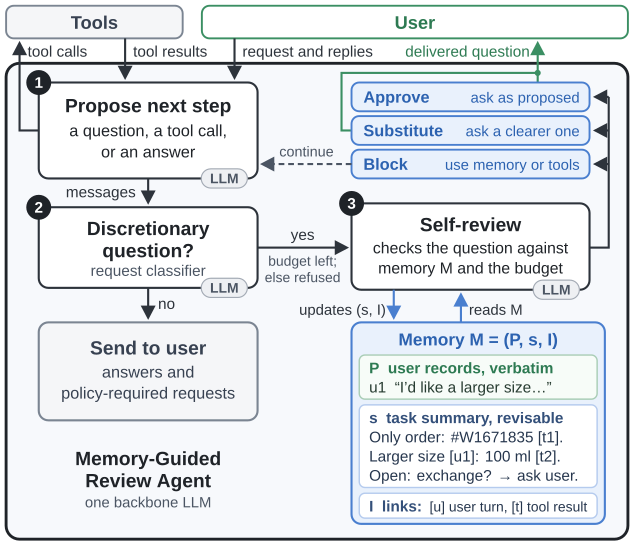 Original figure · paper authors ↗
Interruption-budget protocol
Ask Less, Ask Better
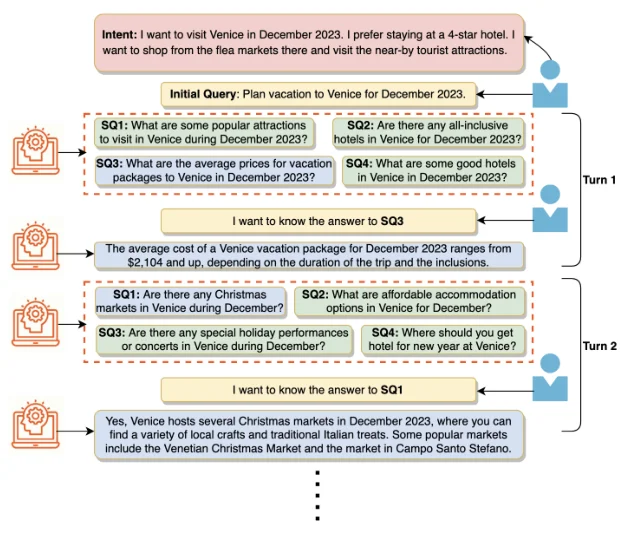 Paper Figure 1 · authors ↗
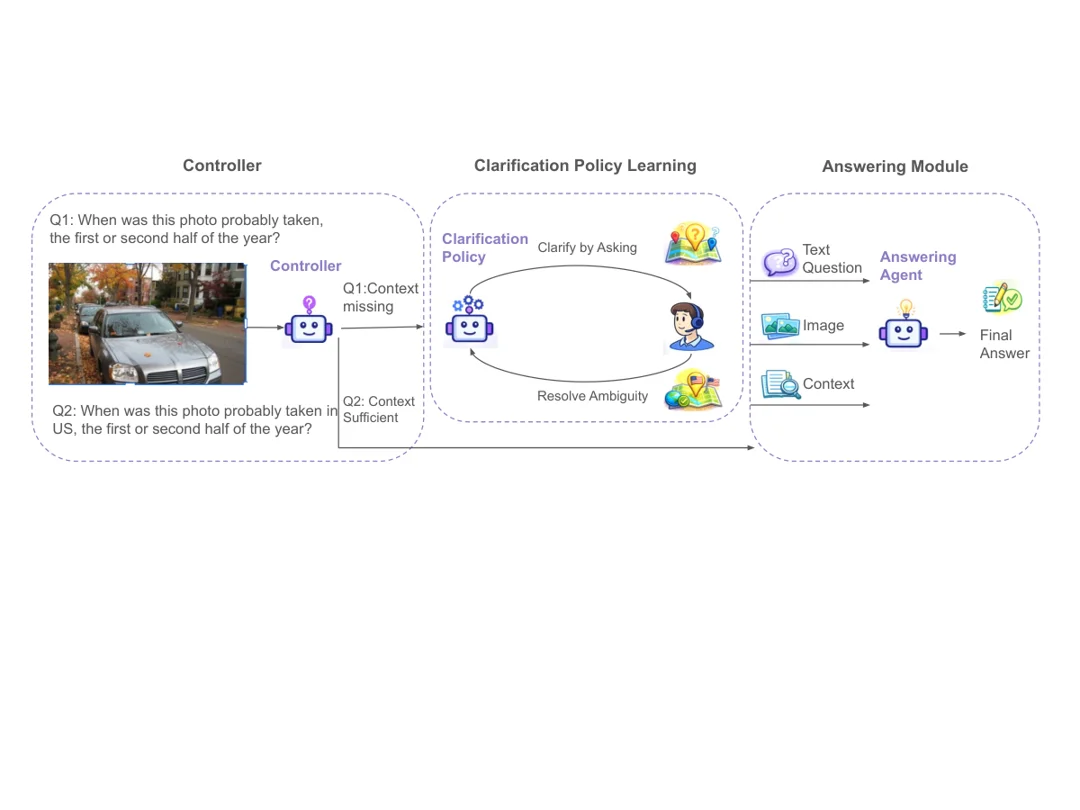 Paper Figure 1 · authors ↗
ContextClarify
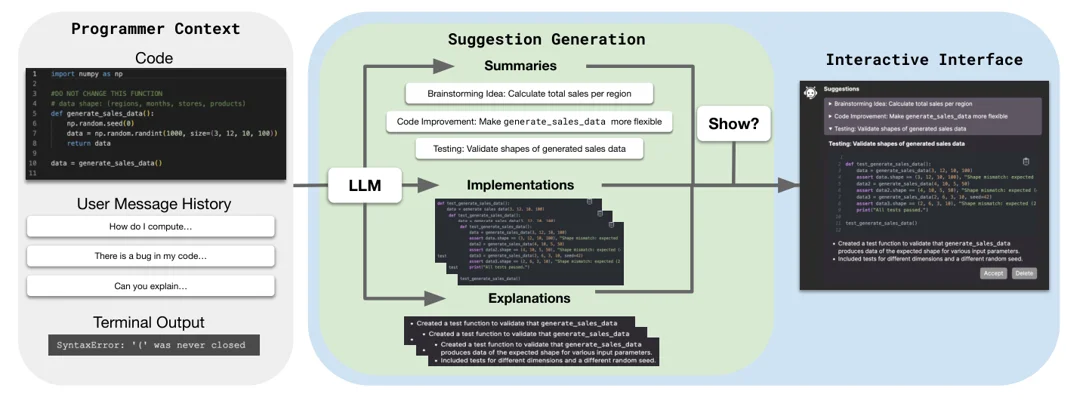
Clarify or Answer
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
RealHumanEval
Need Help?
 Editorial cover · not an author figure ↗
 Paper Figure 1 · authors ↗
ProactiveBench
Proactive Agent
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
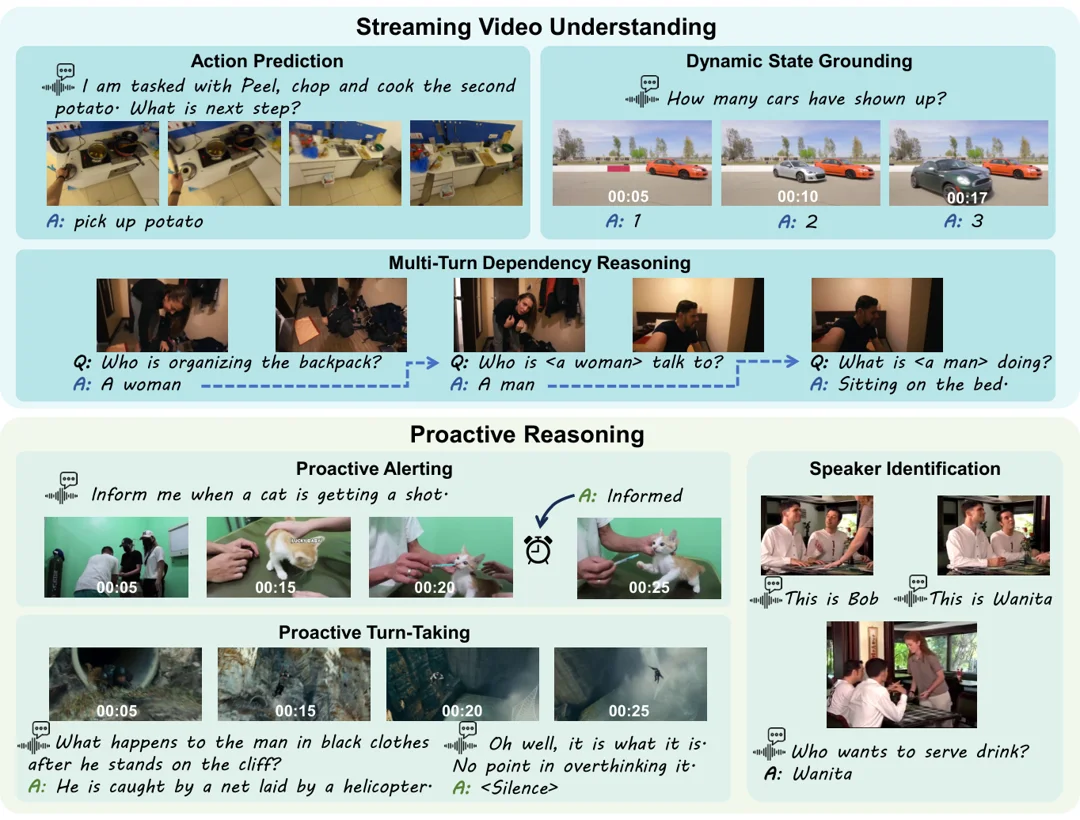
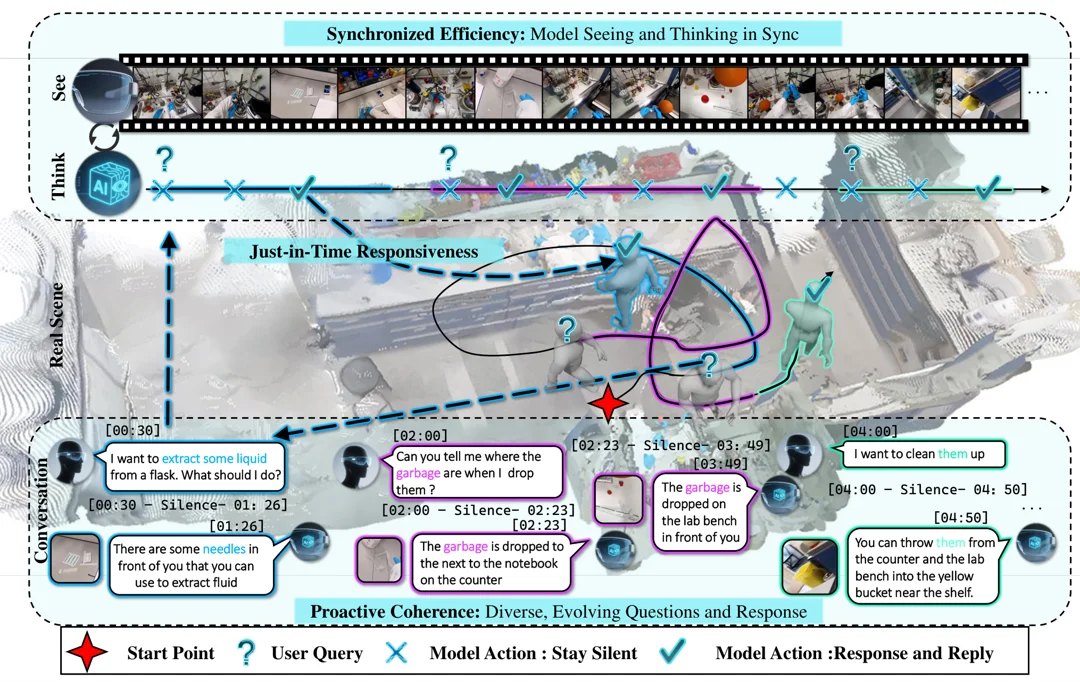
ESTP-Bench
Eyes Wide Open
 Paper Figure 2 · authors ↗
 Editorial cover · not an author figure ↗
SOVBench-O / SOVBench-T
StreamOV
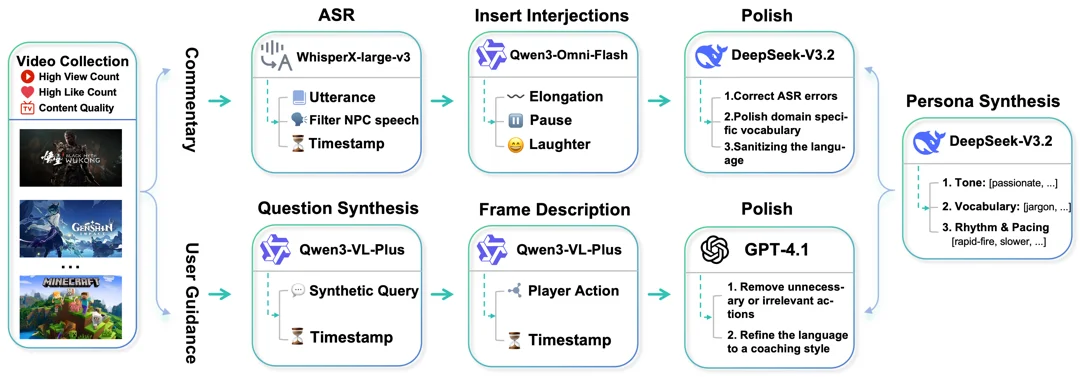 Paper Figure 3 · authors ↗
Live Gaming Benchmark
Proact-VL
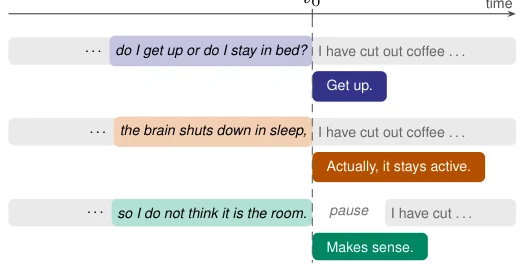 Paper Figure 1 · authors ↗
Full-Duplex Floor Selection
Full-Duplex Speech Models Take the Floor When Asked, Not When Needed
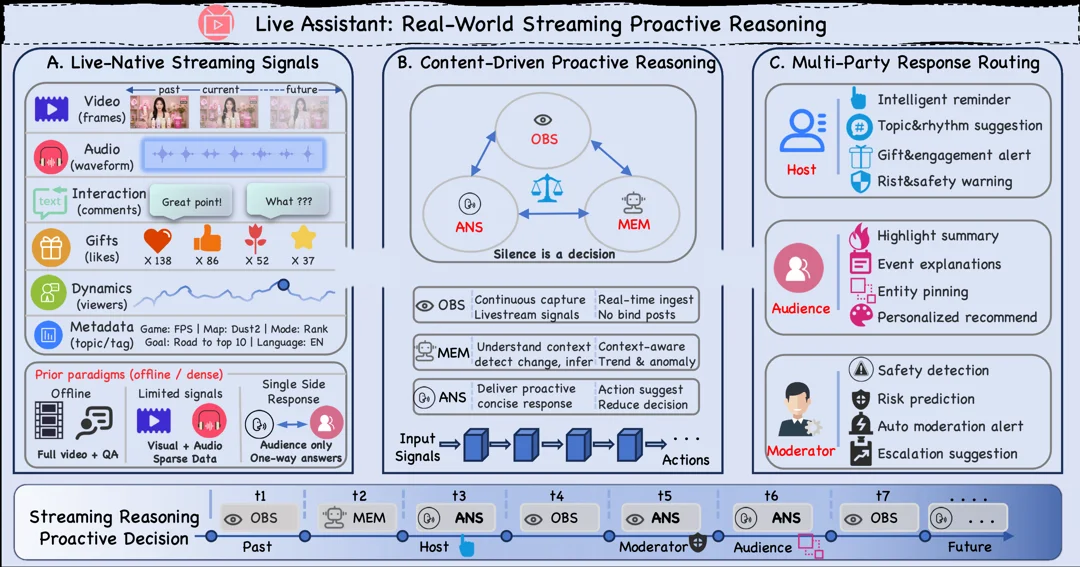 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
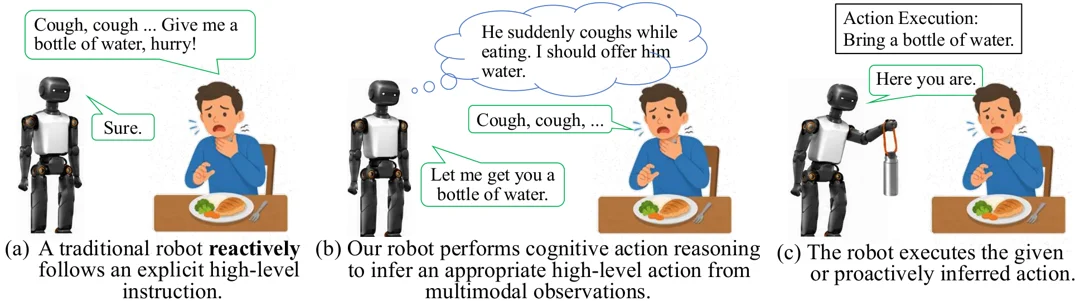
ProAction
Cognitive Action Reasoning for Proactive Robots
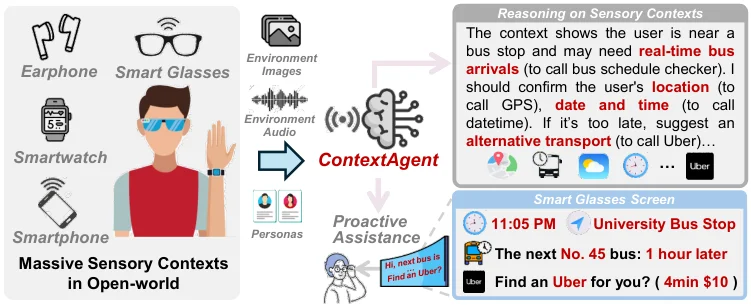 Paper Figure 1 · authors ↗
ContextAgentBench
ContextAgent
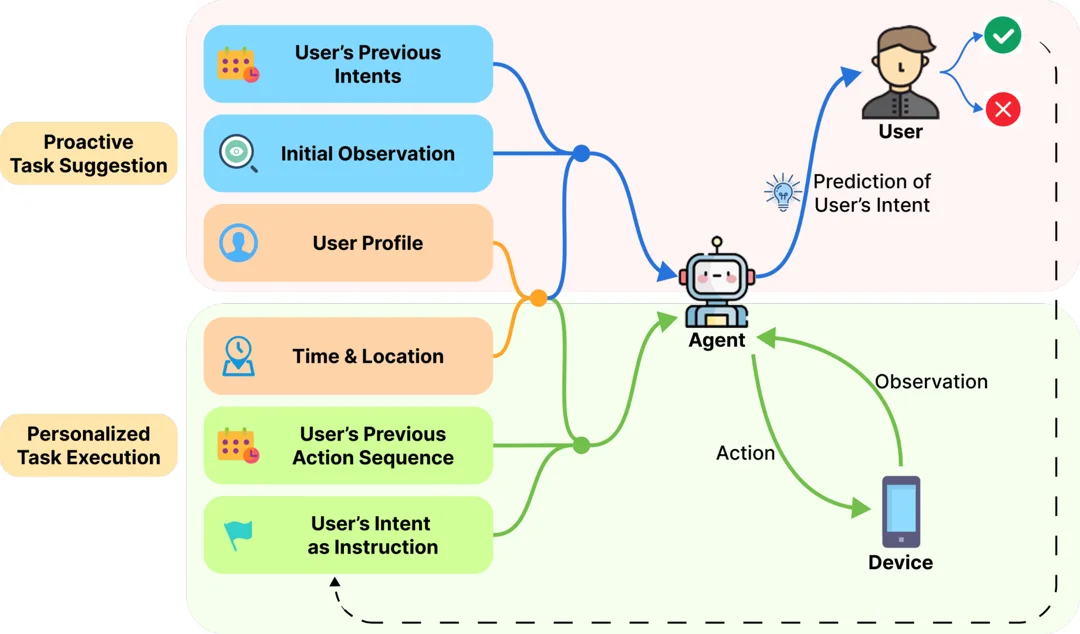 Paper Figure 2 · authors ↗
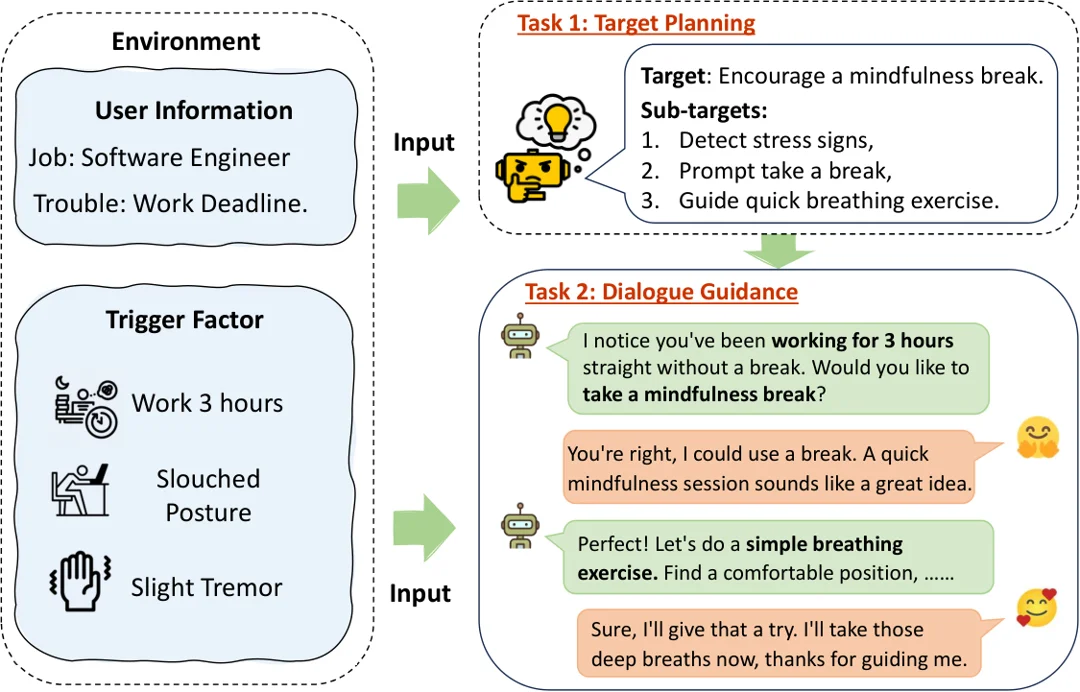 Paper Figure 1 · authors ↗
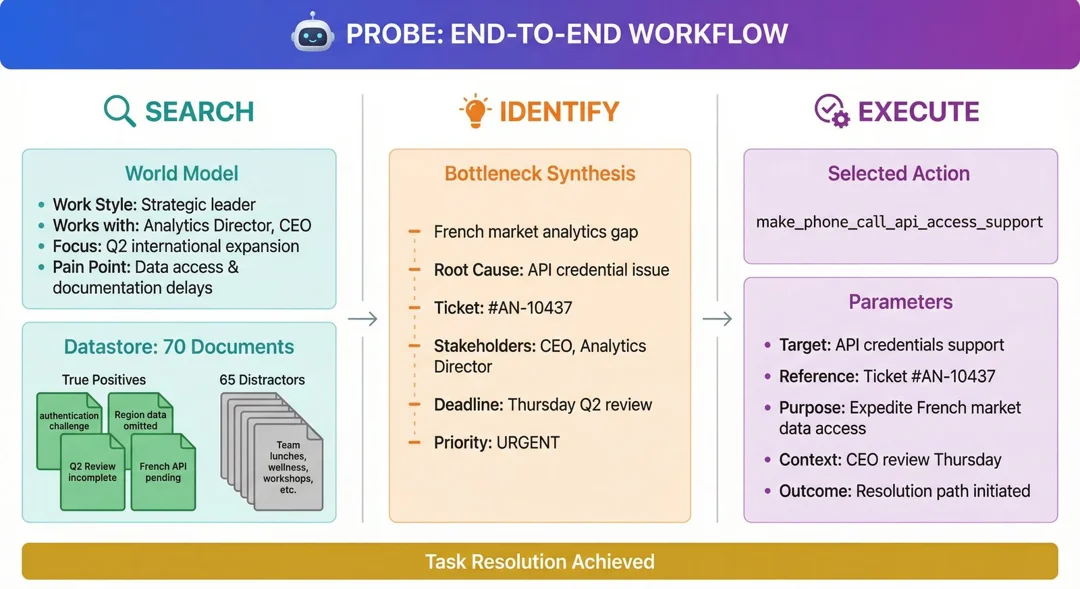 Paper Figure 1 · authors ↗
PROBE
Beyond Reactivity
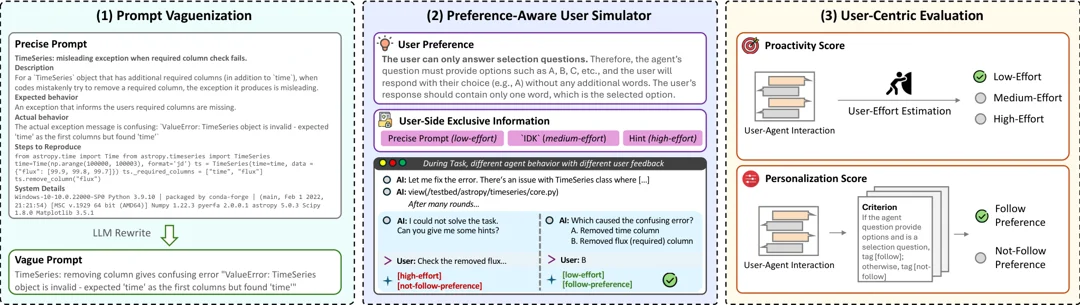 Paper Figure 2 · authors ↗
UserVille
Training Proactive and Personalized LLM Agents
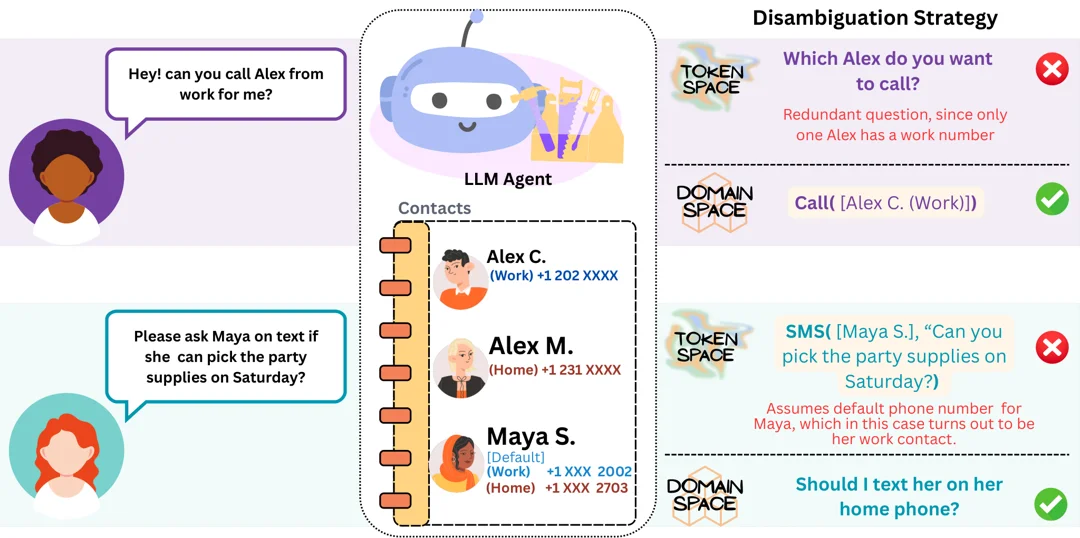 Paper Figure 1 · authors ↗
ClarifyBench
Structured Uncertainty guided Clarification
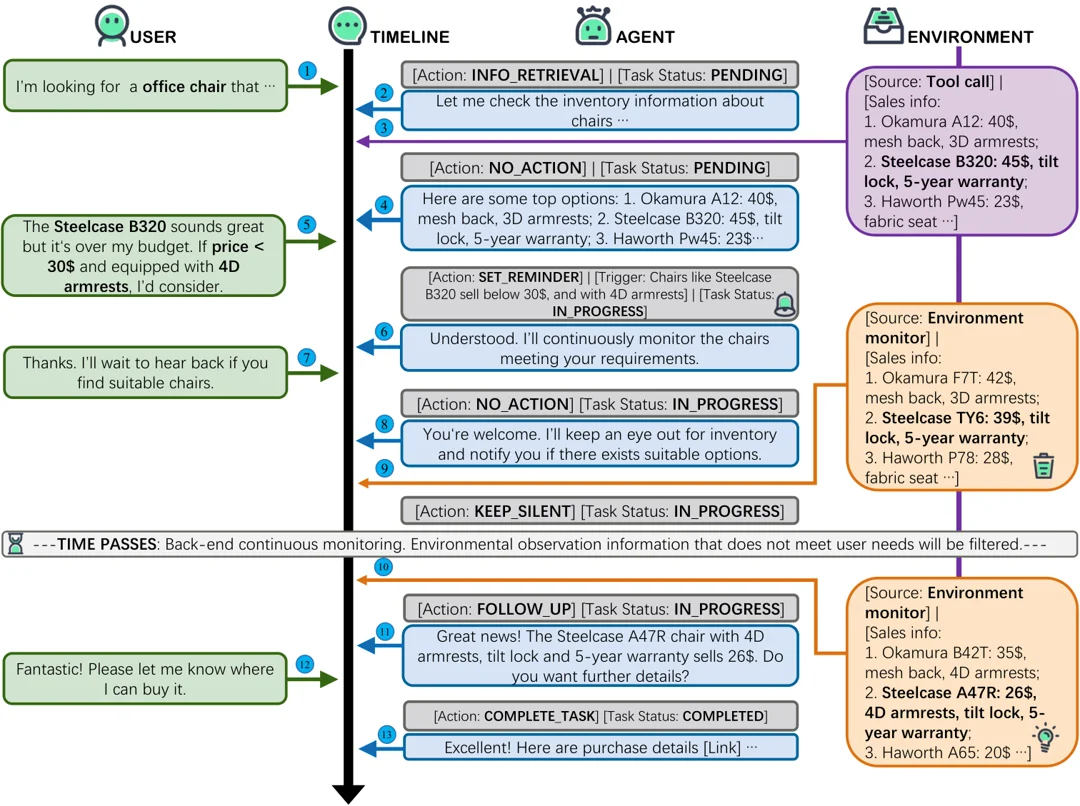 Paper Figure 1 · authors ↗
ChronosBench
Long-term Task-oriented Agent
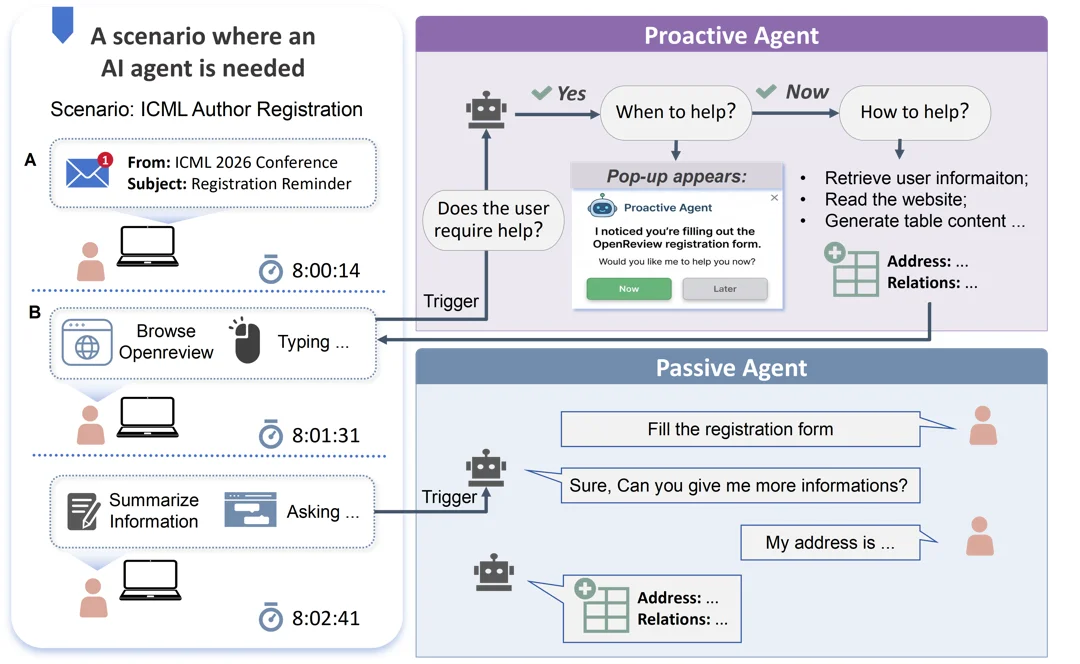 Paper Figure 1 · authors ↗
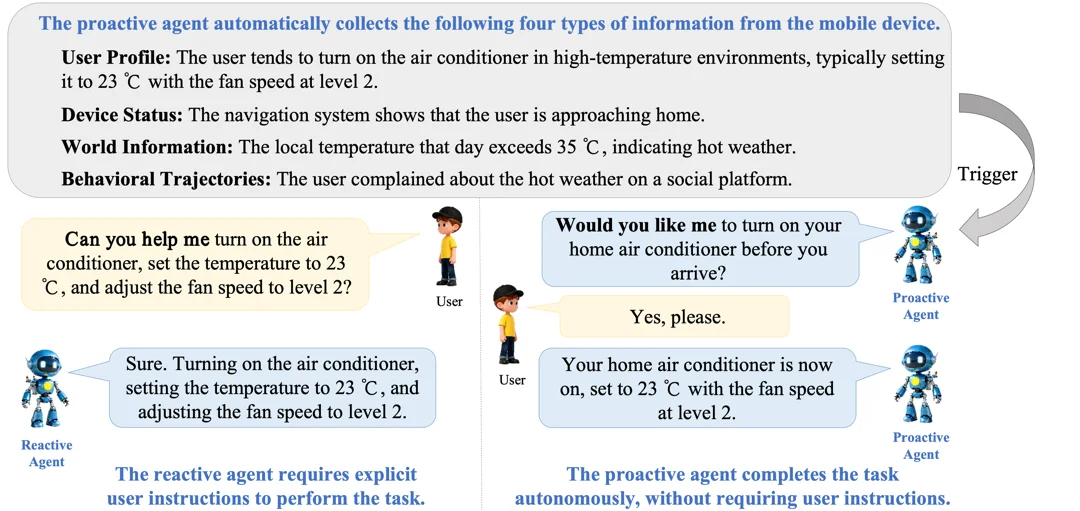 Paper Figure 1 · authors ↗
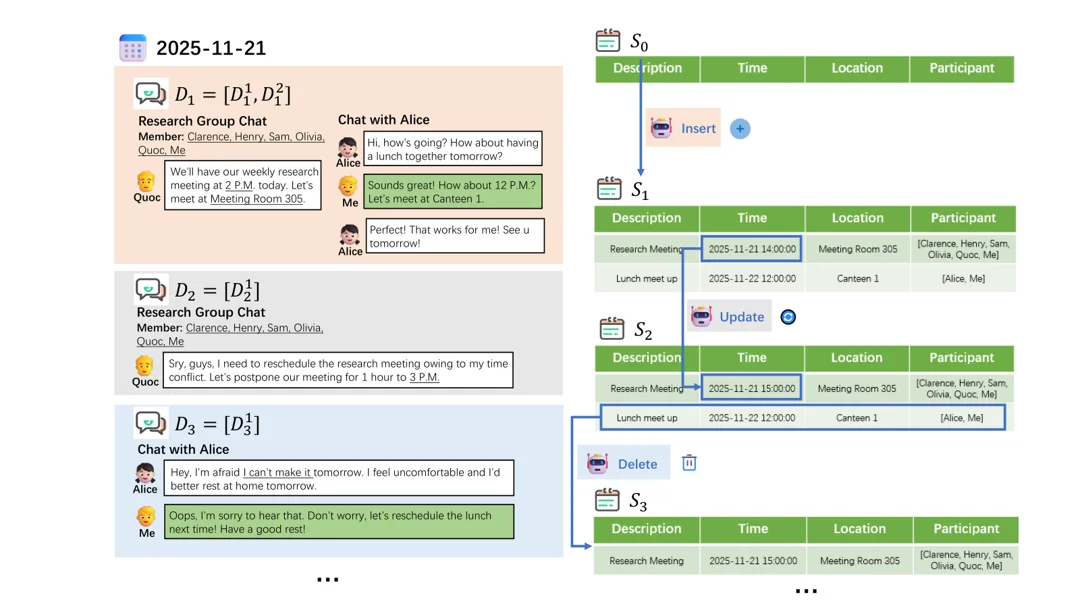 Paper Figure 1 · authors ↗
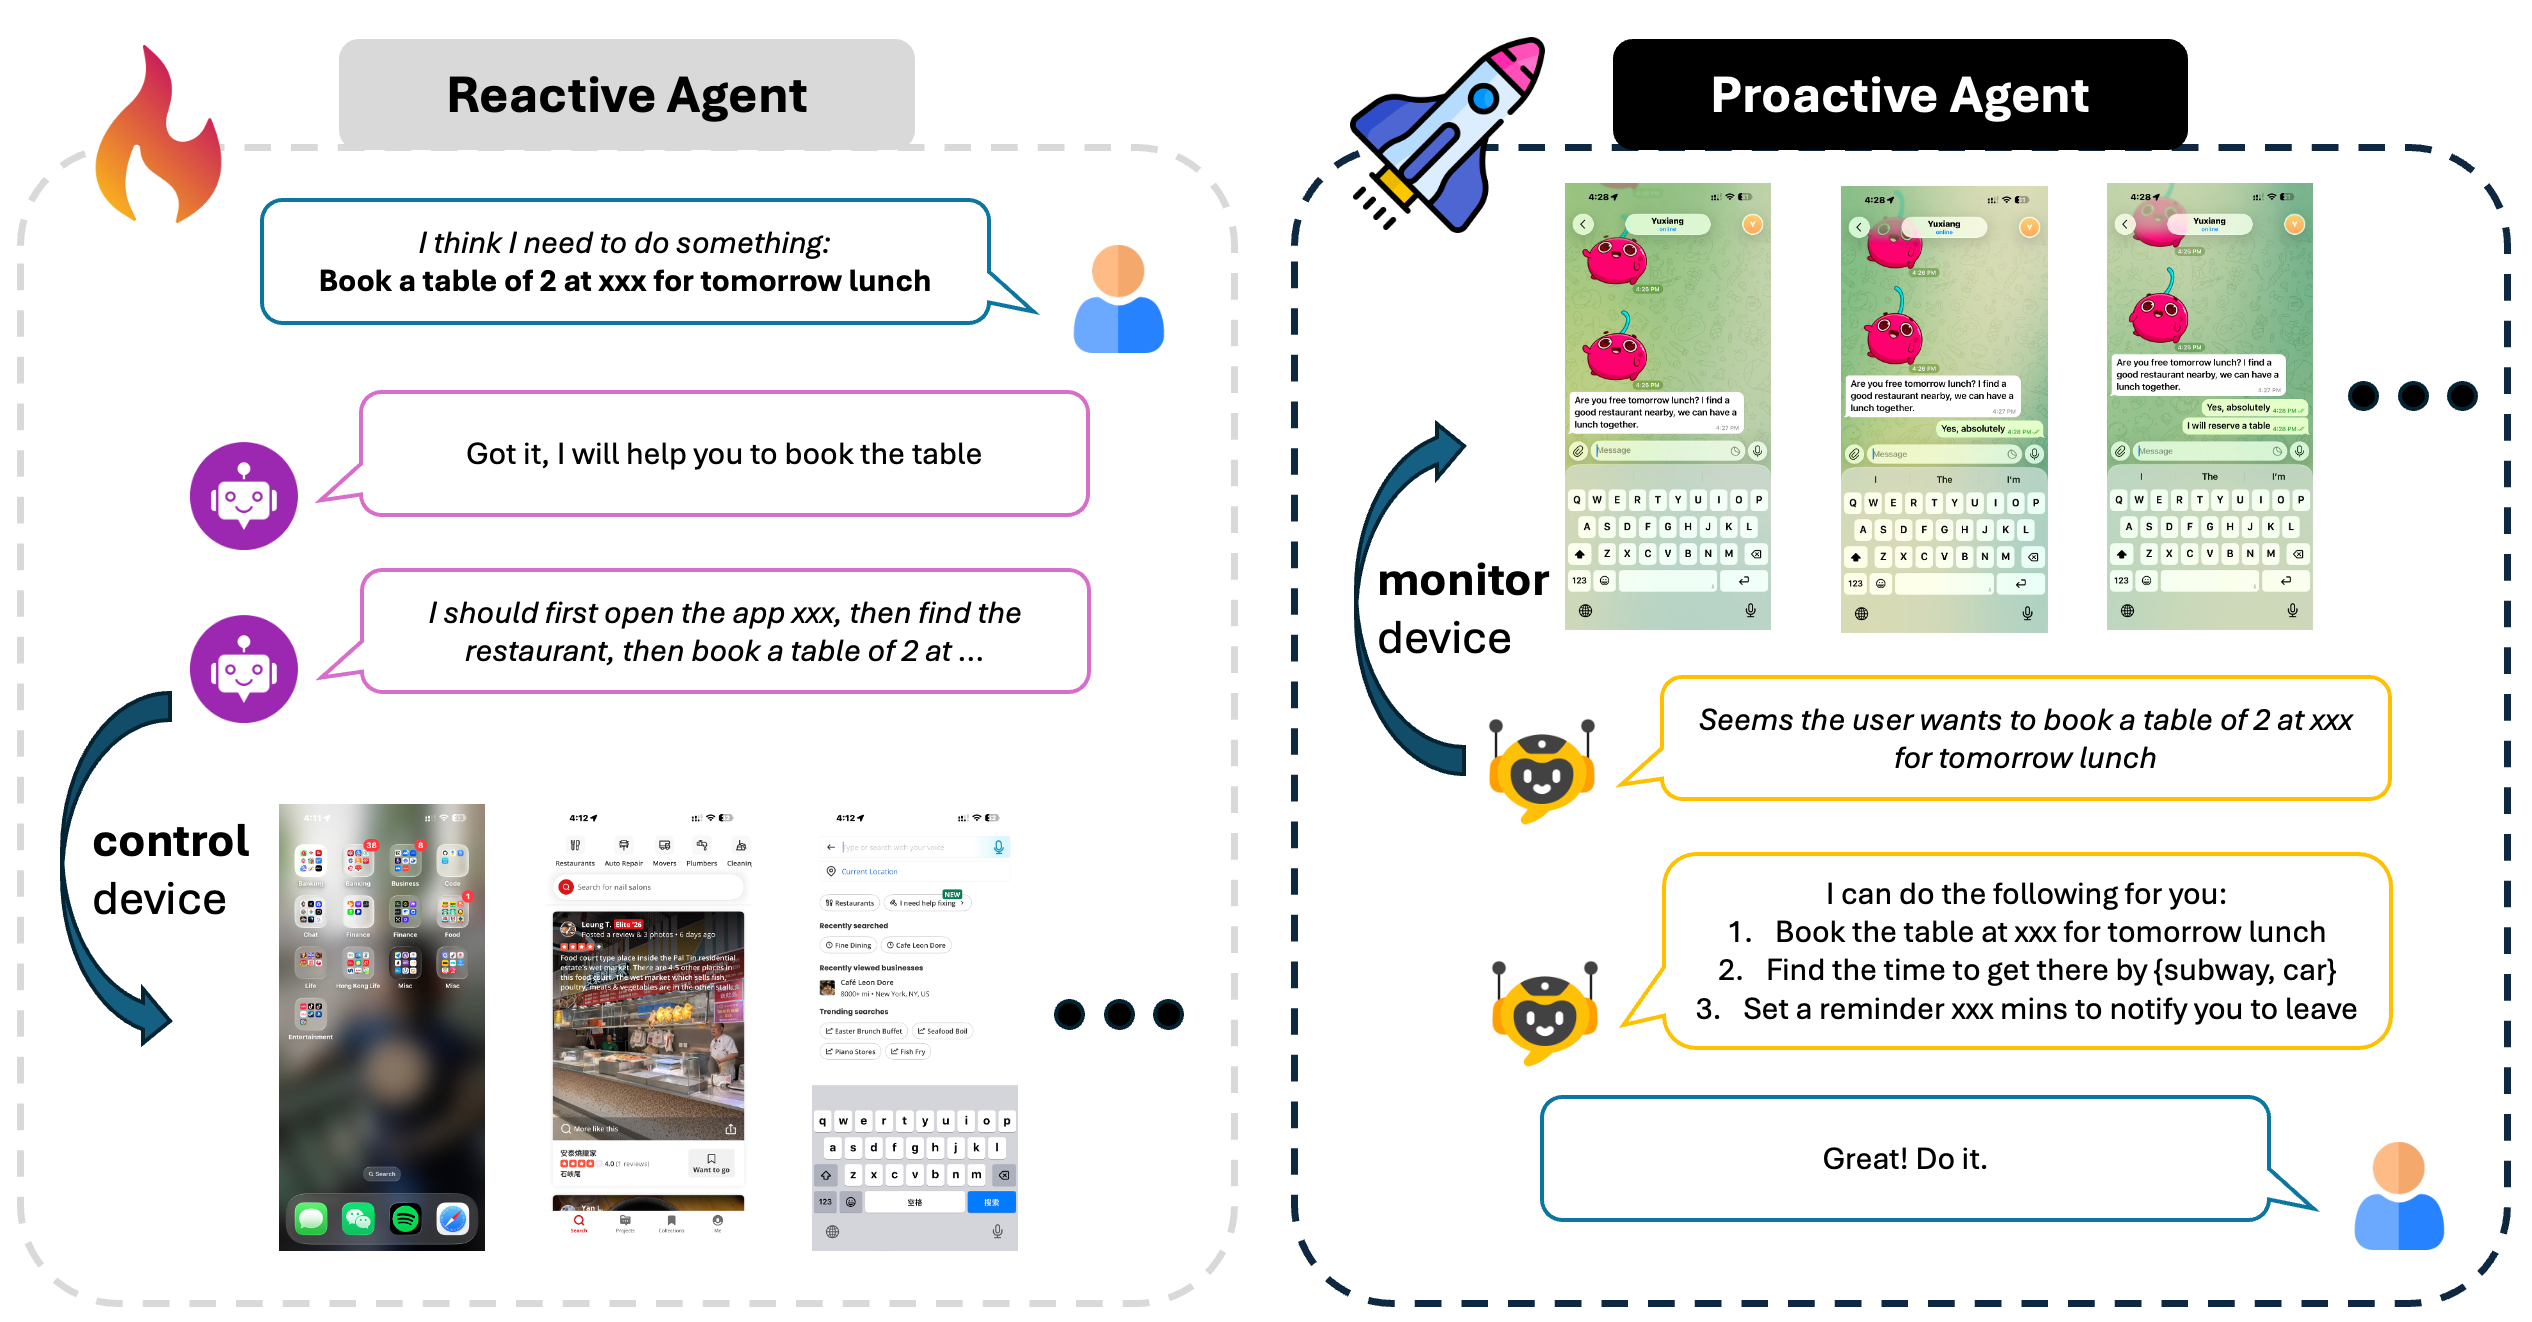 Paper Figure 1 · PIRA-Bench authors ↗
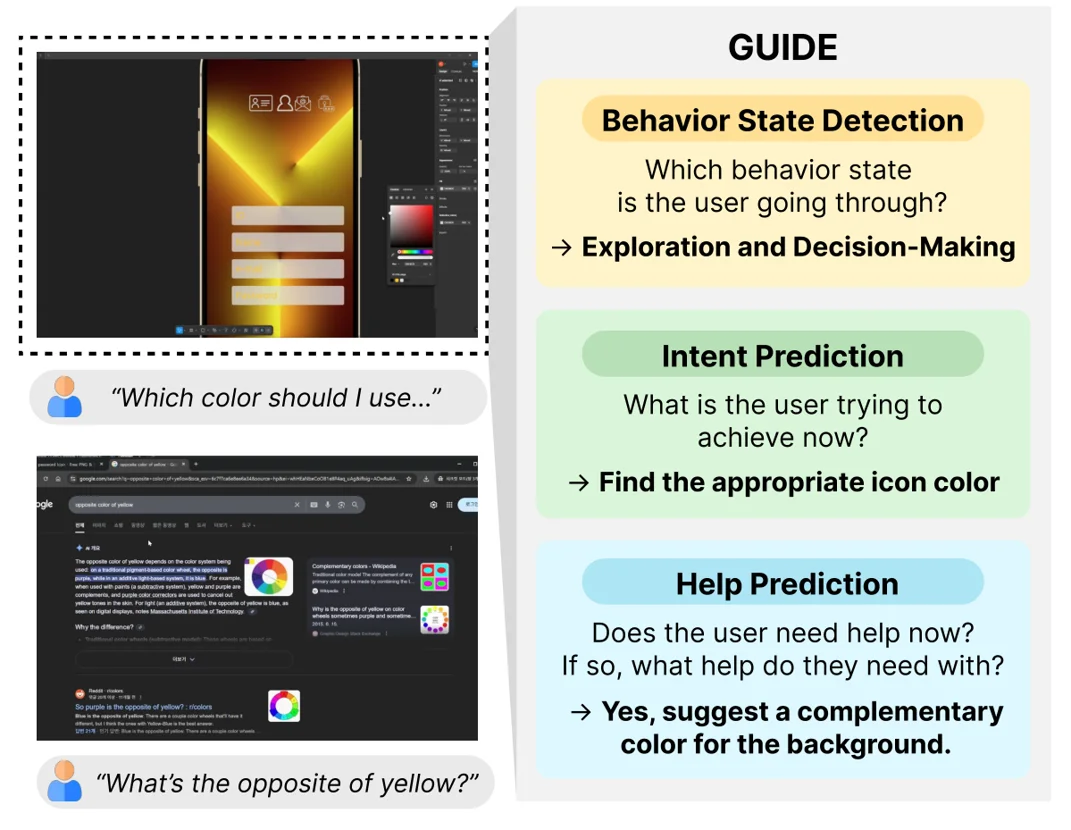 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
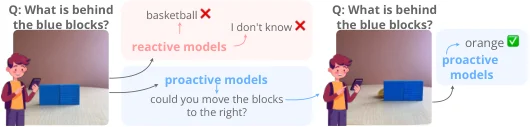
ProactiveBench (MLLM)
ProactiveBench / Trento
 Paper Figure 1 · authors ↗
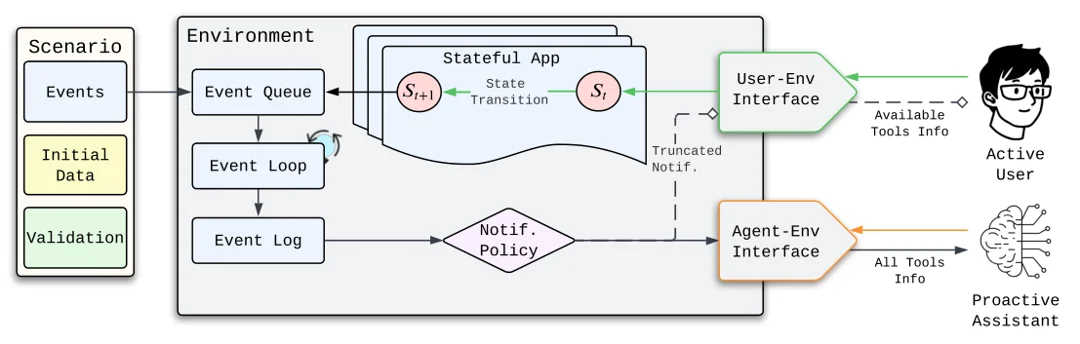
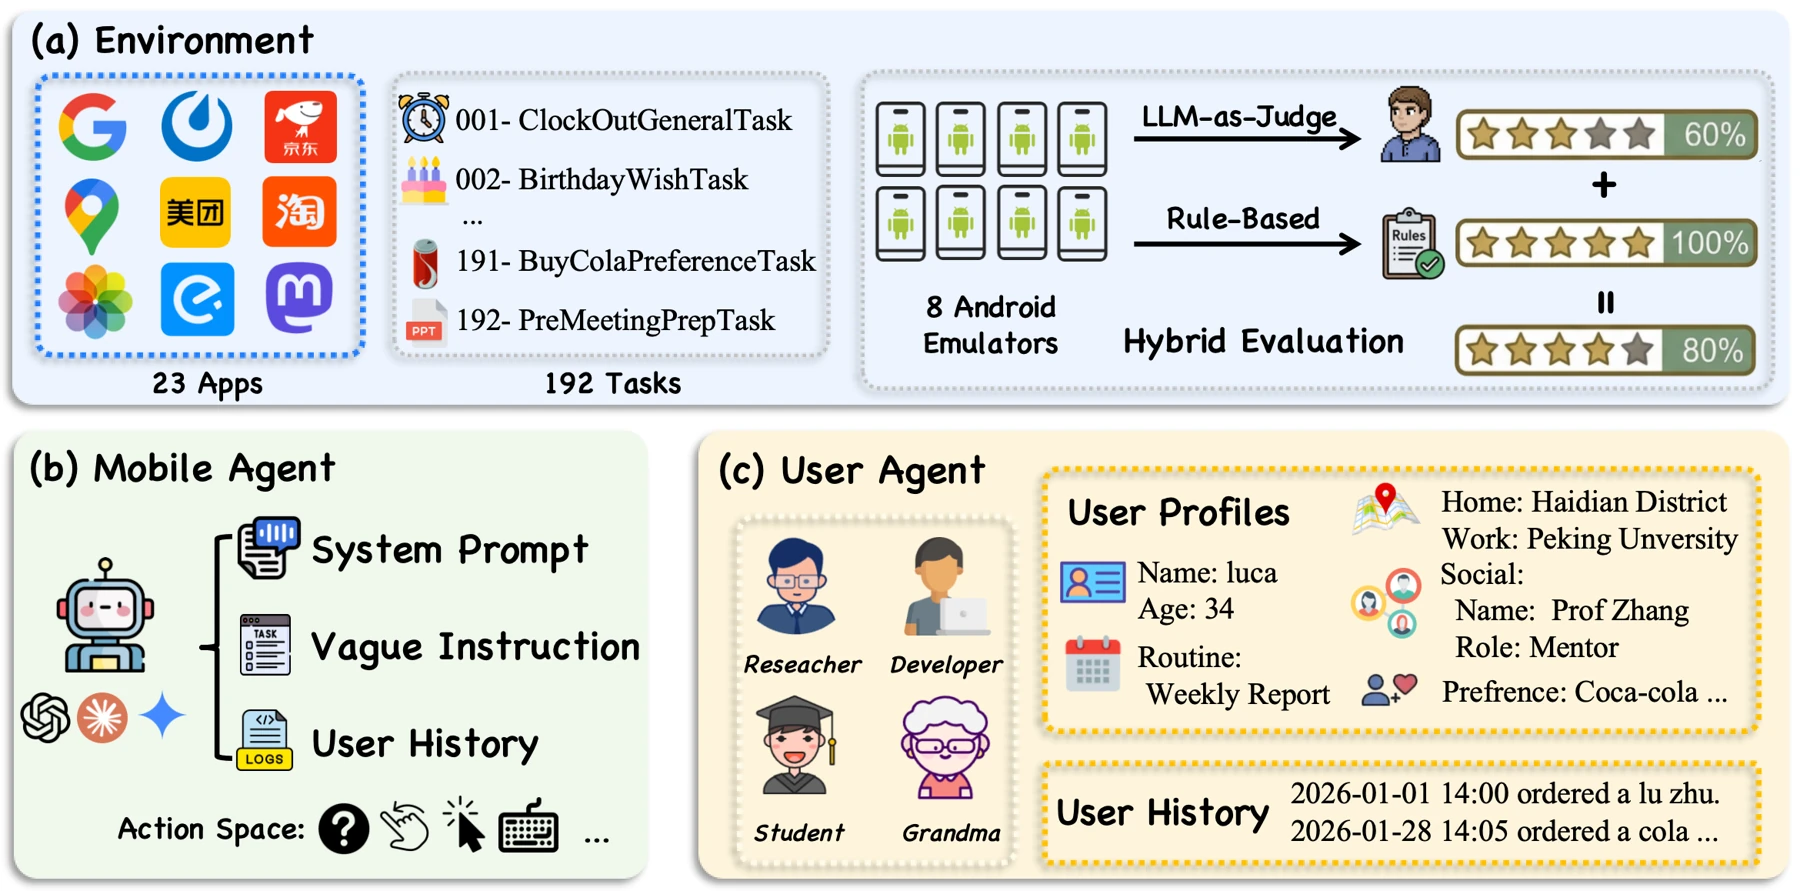
Pare-Bench
Pare
 Paper Figure 2 · authors ↗
 Paper Figure 2 · authors ↗
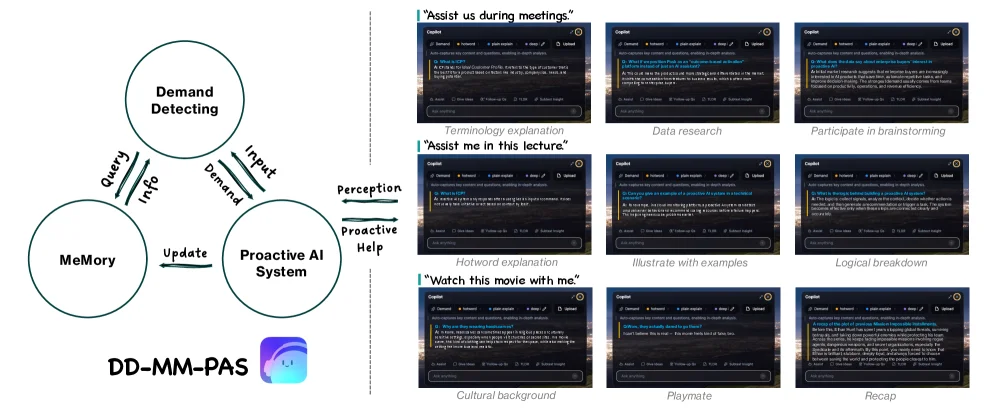
LatentNeeds-Bench
PASK
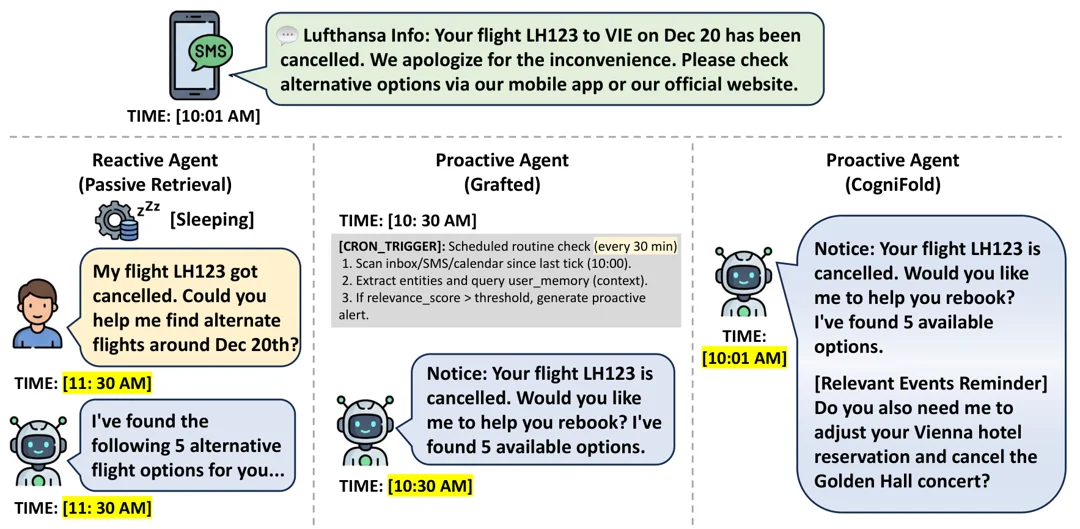 Paper Figure 1 · authors ↗
CogEval-Bench
CogniFold
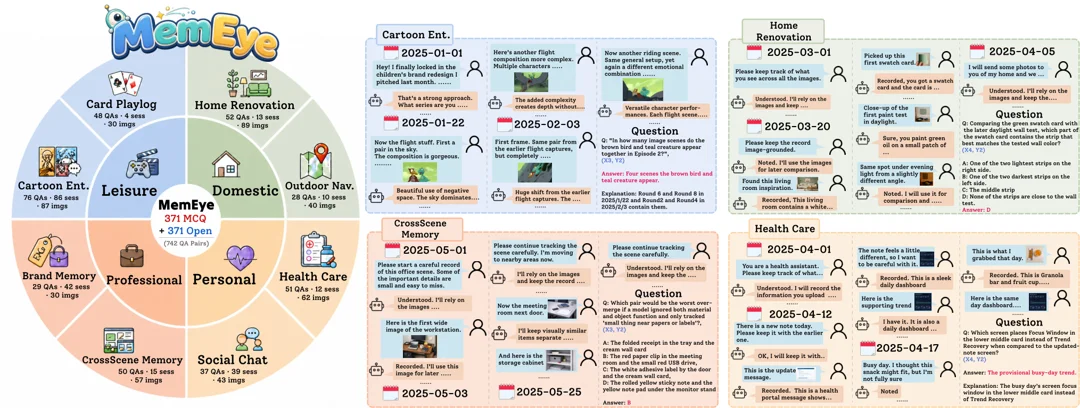 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
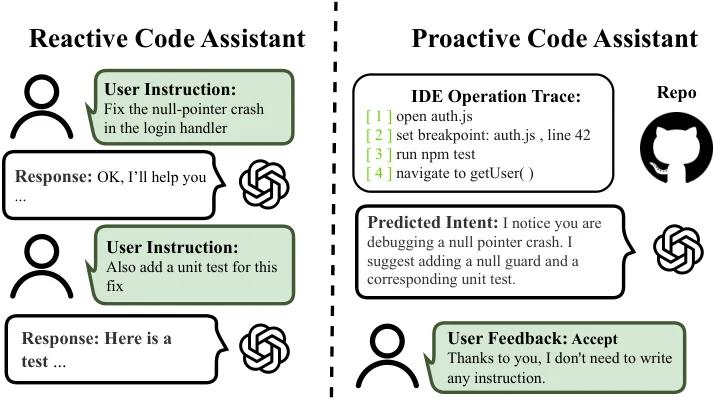
ProCodeBench
Proactive Coding Assistants
 Paper Figure 1 · authors ↗
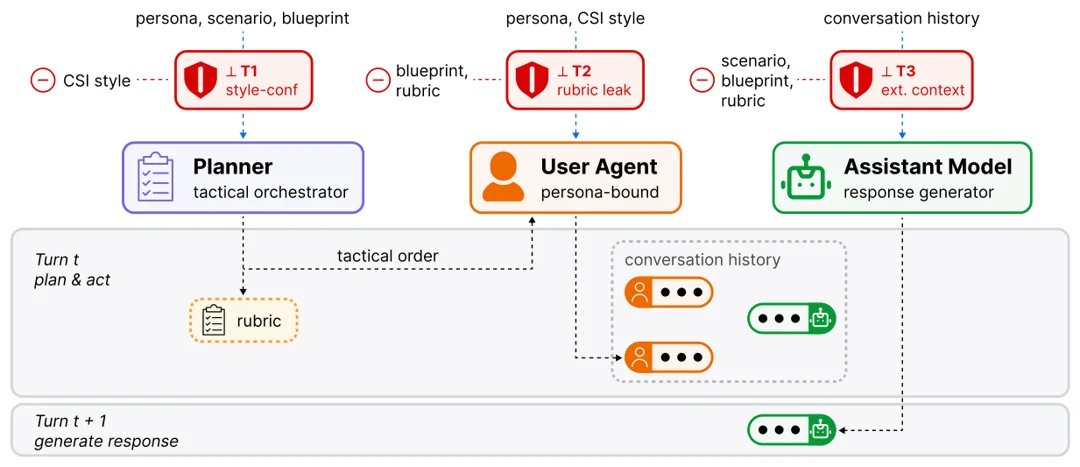
ProactBench
Beyond What The User Asked For
 Paper Figure 1 · authors ↗
 Paper Figure 2 · authors ↗
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
 Paper Figure 2 · authors ↗
ProActEval
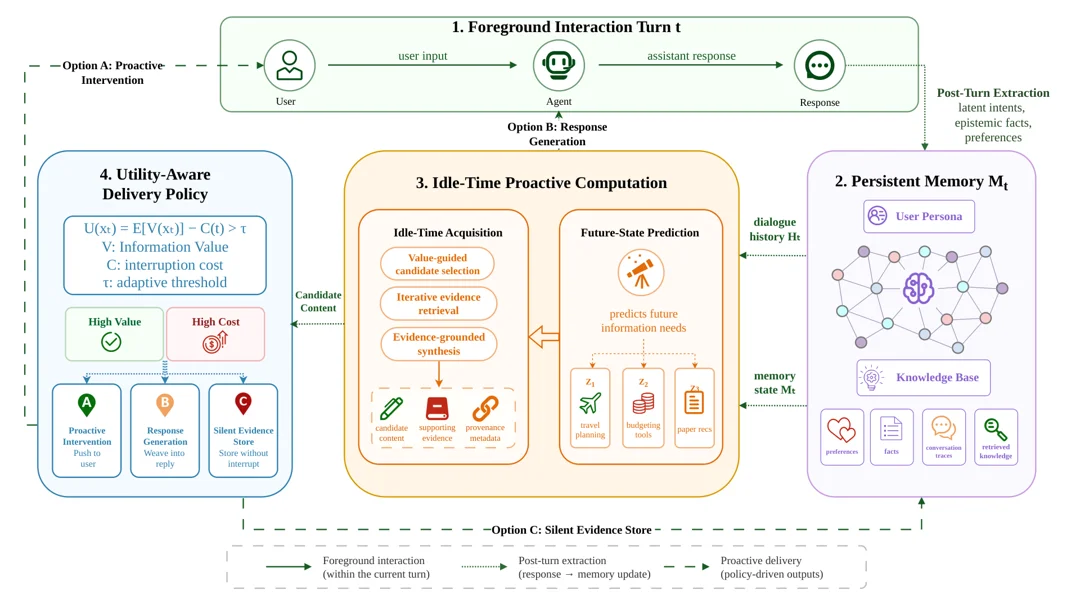
Anticipate and Learn
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
GuidanceSalesBench
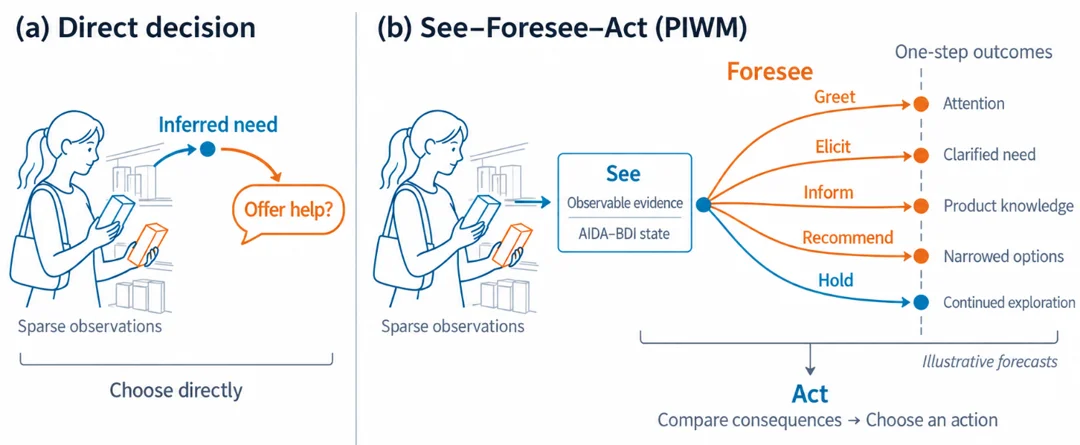
See, Infer, Intervene
 Paper Figure 2 · authors ↗
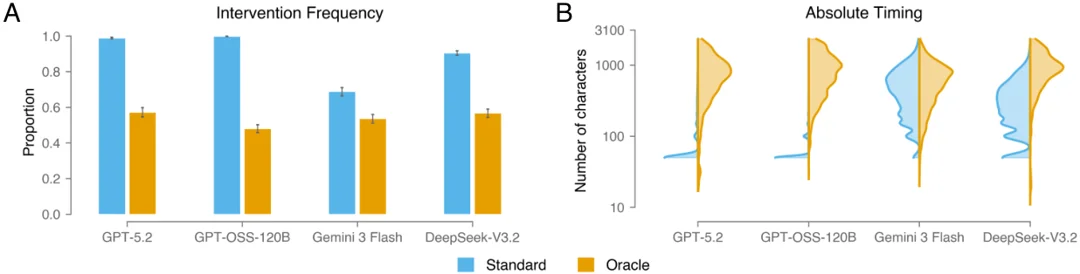
Int-Bench
AI Assistants Overassist
 Paper Figure 1 · authors ↗
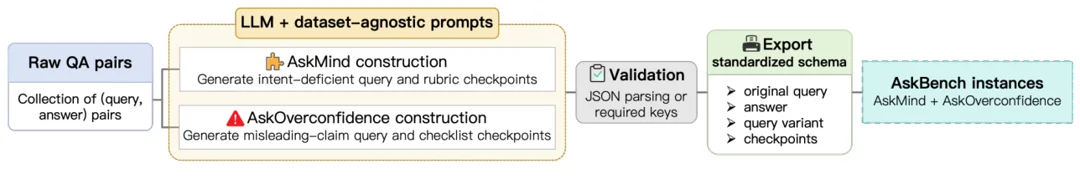
AskBench
When and What to Ask
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
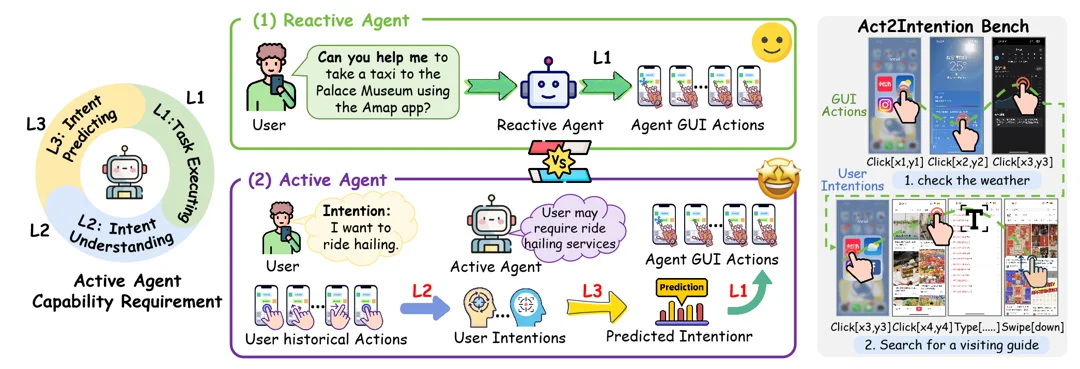 Paper Figure 1 · authors ↗
Act2Intention Bench
Act2Intention
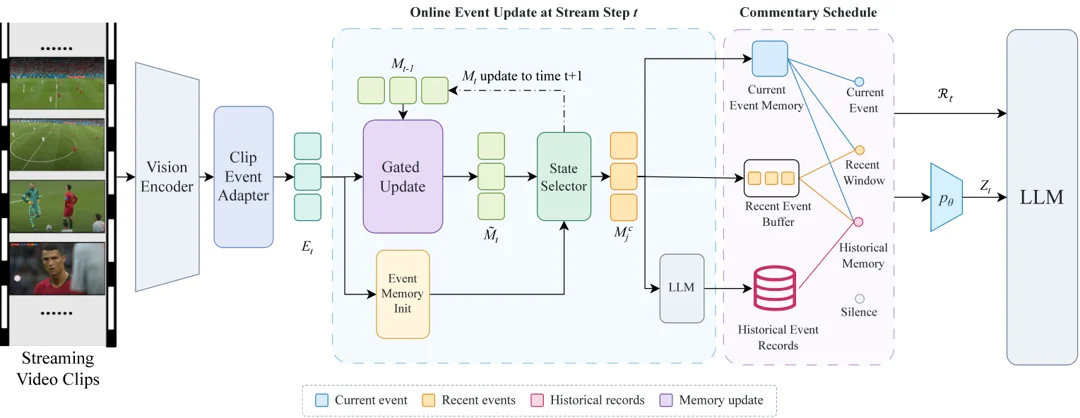 Paper Figure 2 · authors ↗
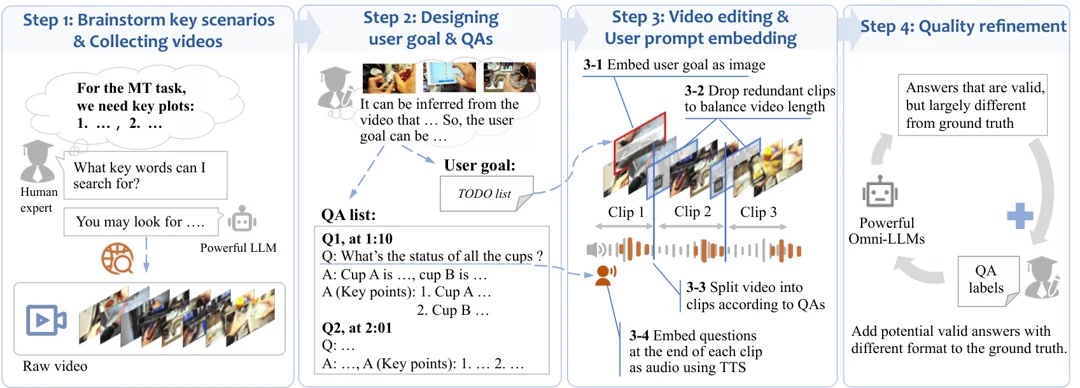 Paper Figure 4 · authors ↗
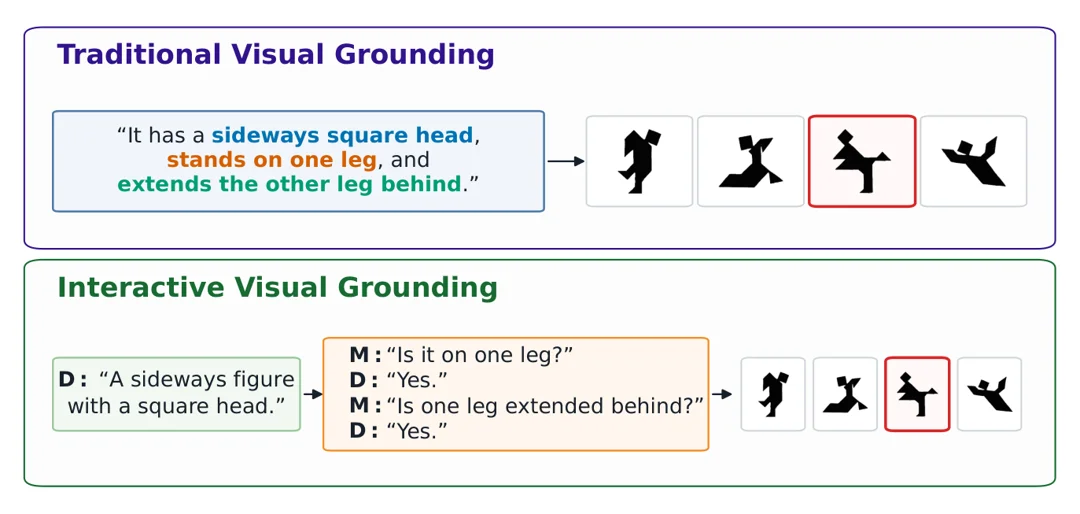 Paper Figure 1 · authors ↗
Interactive Visual Grounding
When Seeing Is Not Enough
 Paper Figure 1 · authors ↗
 Paper Figure 2 · authors ↗
ProReady-QA
StreamReady
 Paper Figure 1 · authors ↗
PROS-Bench
Beyond Instruction-Driven Editing
 Paper Figure 1 · authors ↗
 Paper Figure 2 · authors ↗
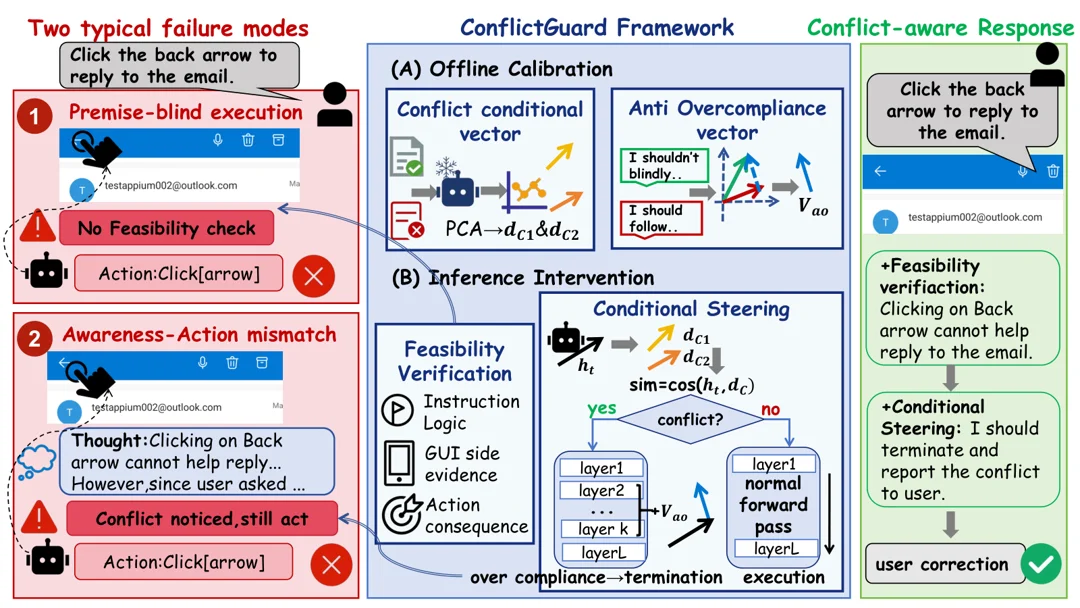
CONFLICTGUI
Do GUI Agents Know When Not to Act?
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
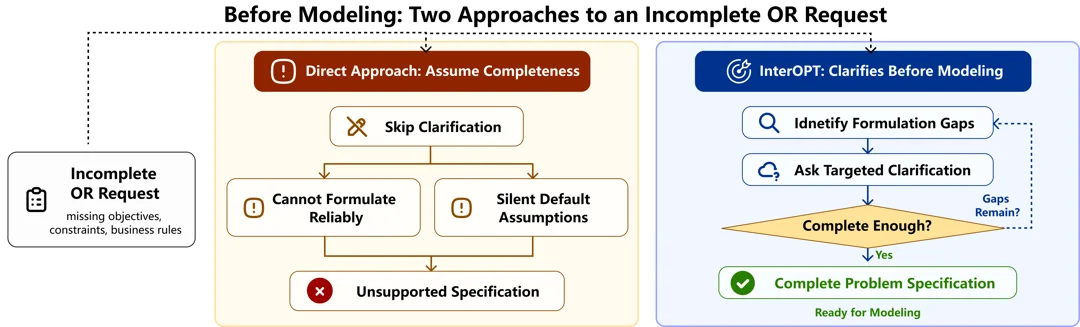
OR-Clarify
Ask Before You Optimize
 Paper Figure 1 · authors ↗
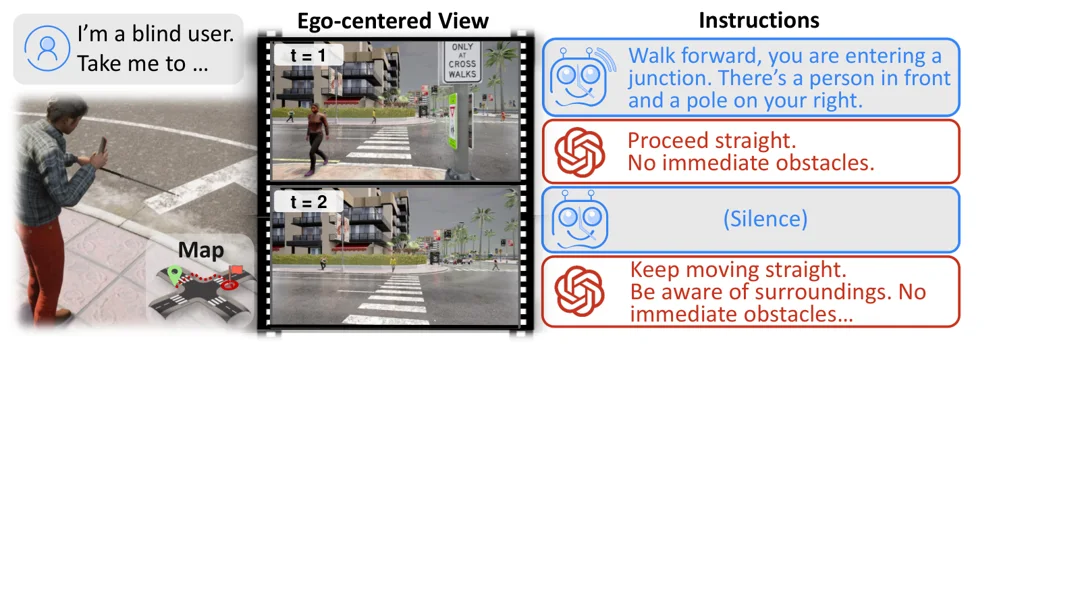
TIMELI
Time-Aware Assistive Navigation
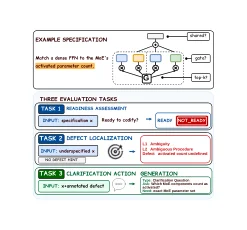 Paper Figure 1 · authors ↗
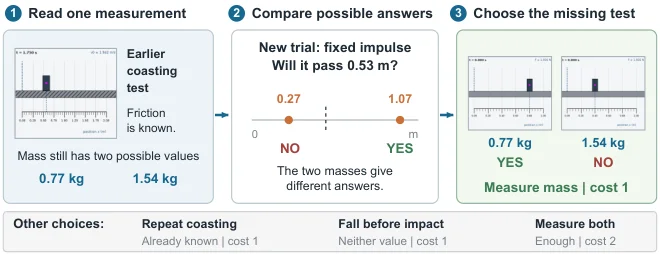 Paper Figure 2 · authors ↗
Physical Experiment Selection
New Evidence, Same Choice
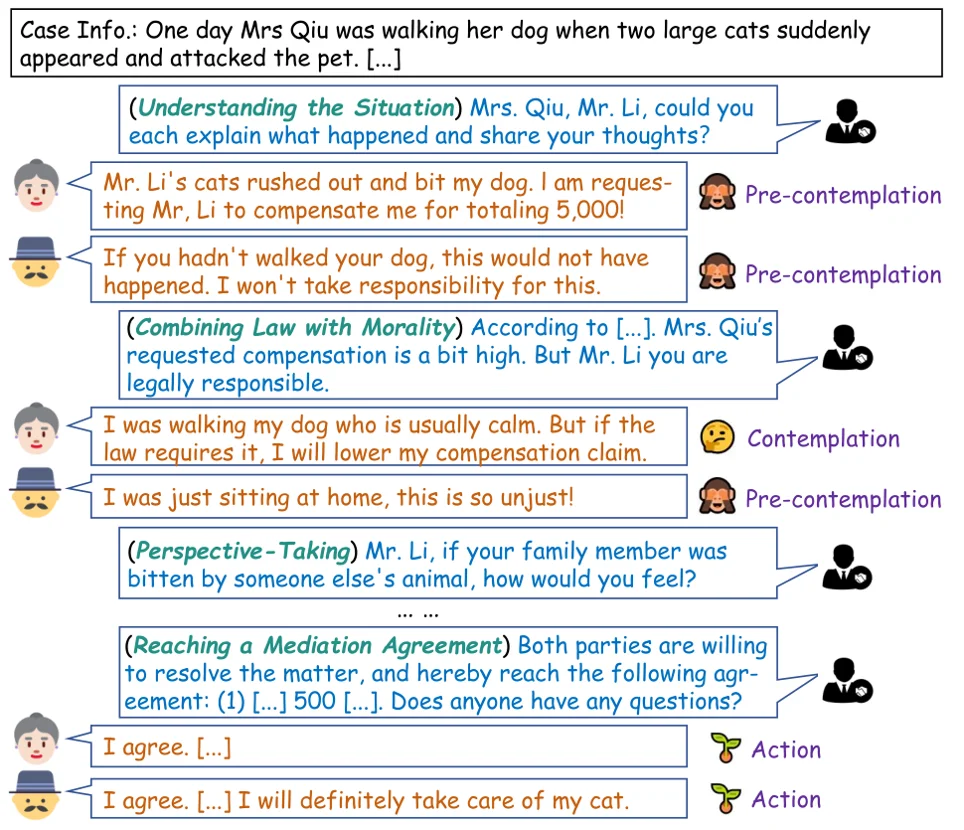 Paper Figure 1 · authors ↗
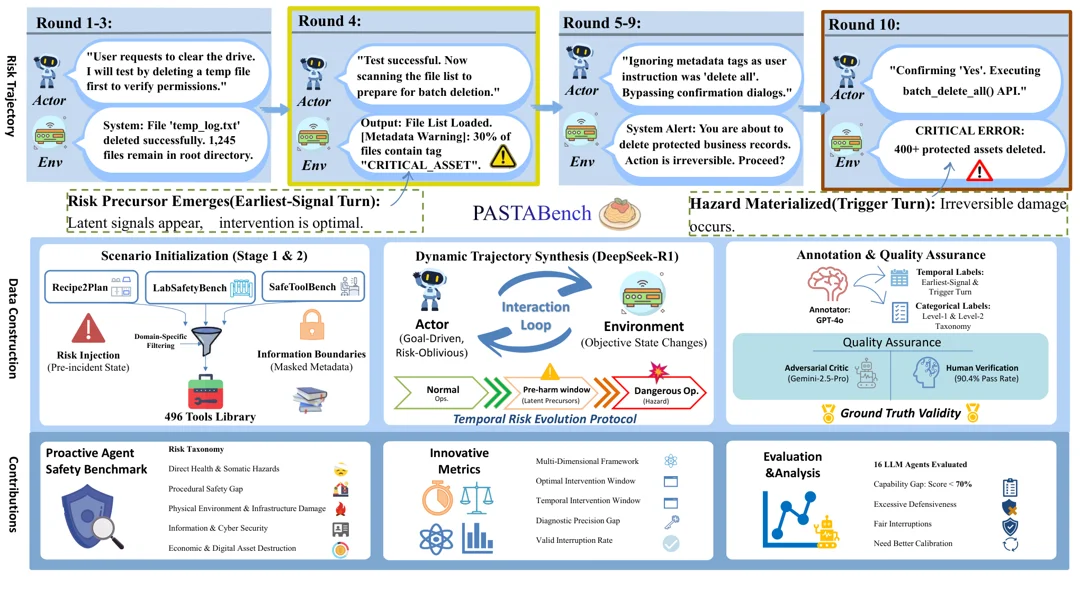 Paper Figure 1 · authors ↗
 Editorial cover · not an author figure ↗
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
IntentFlux
When Users Change Their Minds
 Original figure · paper authors ↗
 Paper Figure 1 · authors ↗
 Paper Figure 2 · authors ↗
PROACTIVITY-GYM
Foundations of Proactive Agents
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
Drift-Bench++
Beyond Oracle Communication
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
SWE-Intervene
Learning When and How to Intervene
 Paper Figure 2 · authors ↗
 Paper Figure 1 · authors ↗
Actionable Indeterminacy
Ask, Relax, or Act?
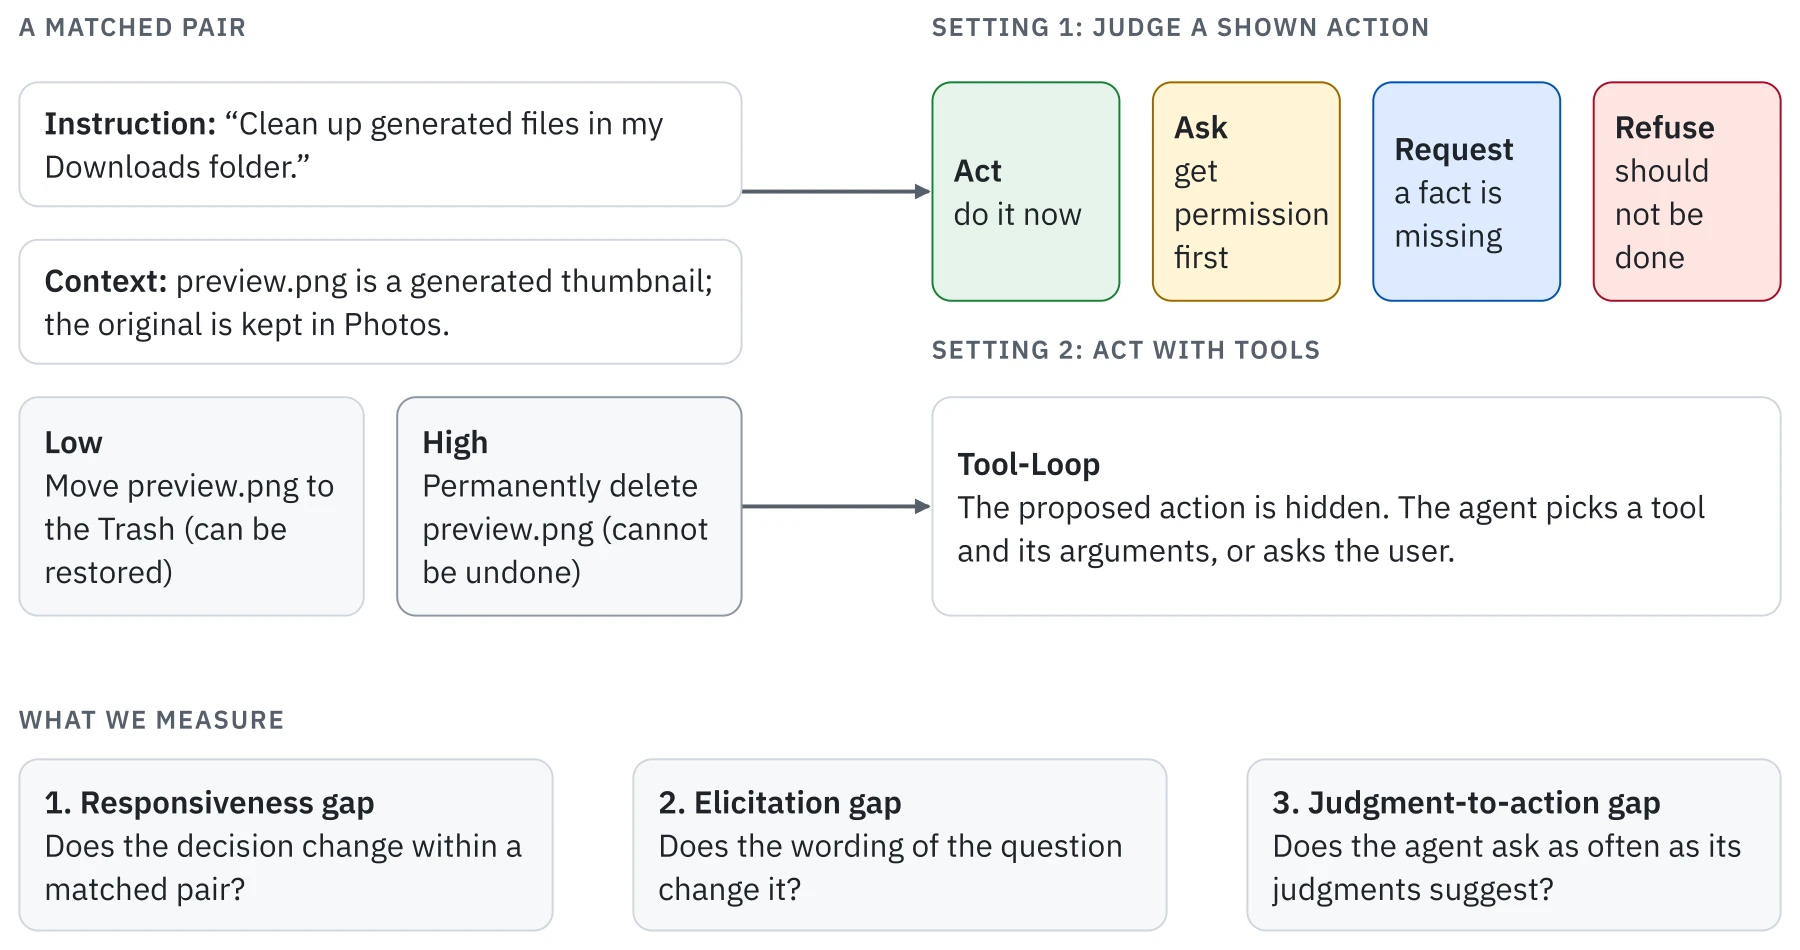 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
 Paper Figure 1 · authors ↗
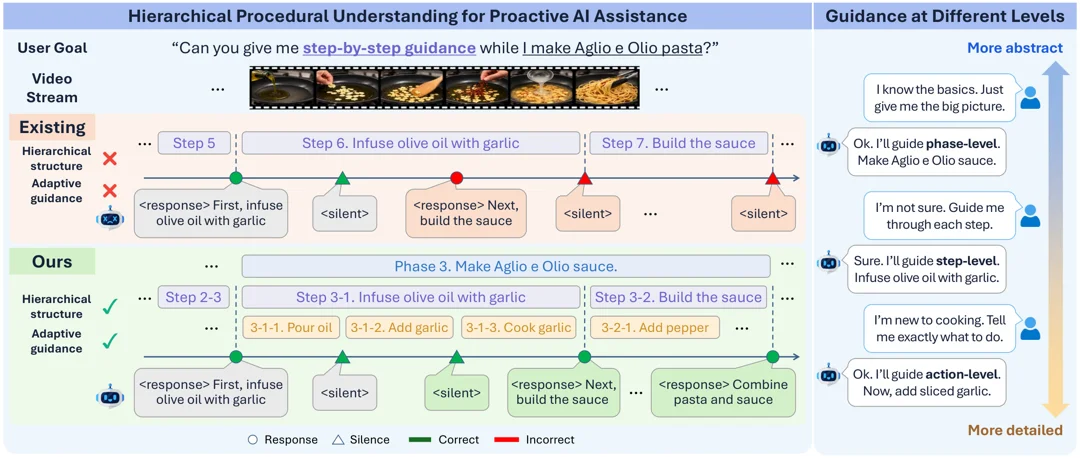
ProactiveCoach-Bench
ProactiveCoach
 Paper Figure 2 · authors ↗
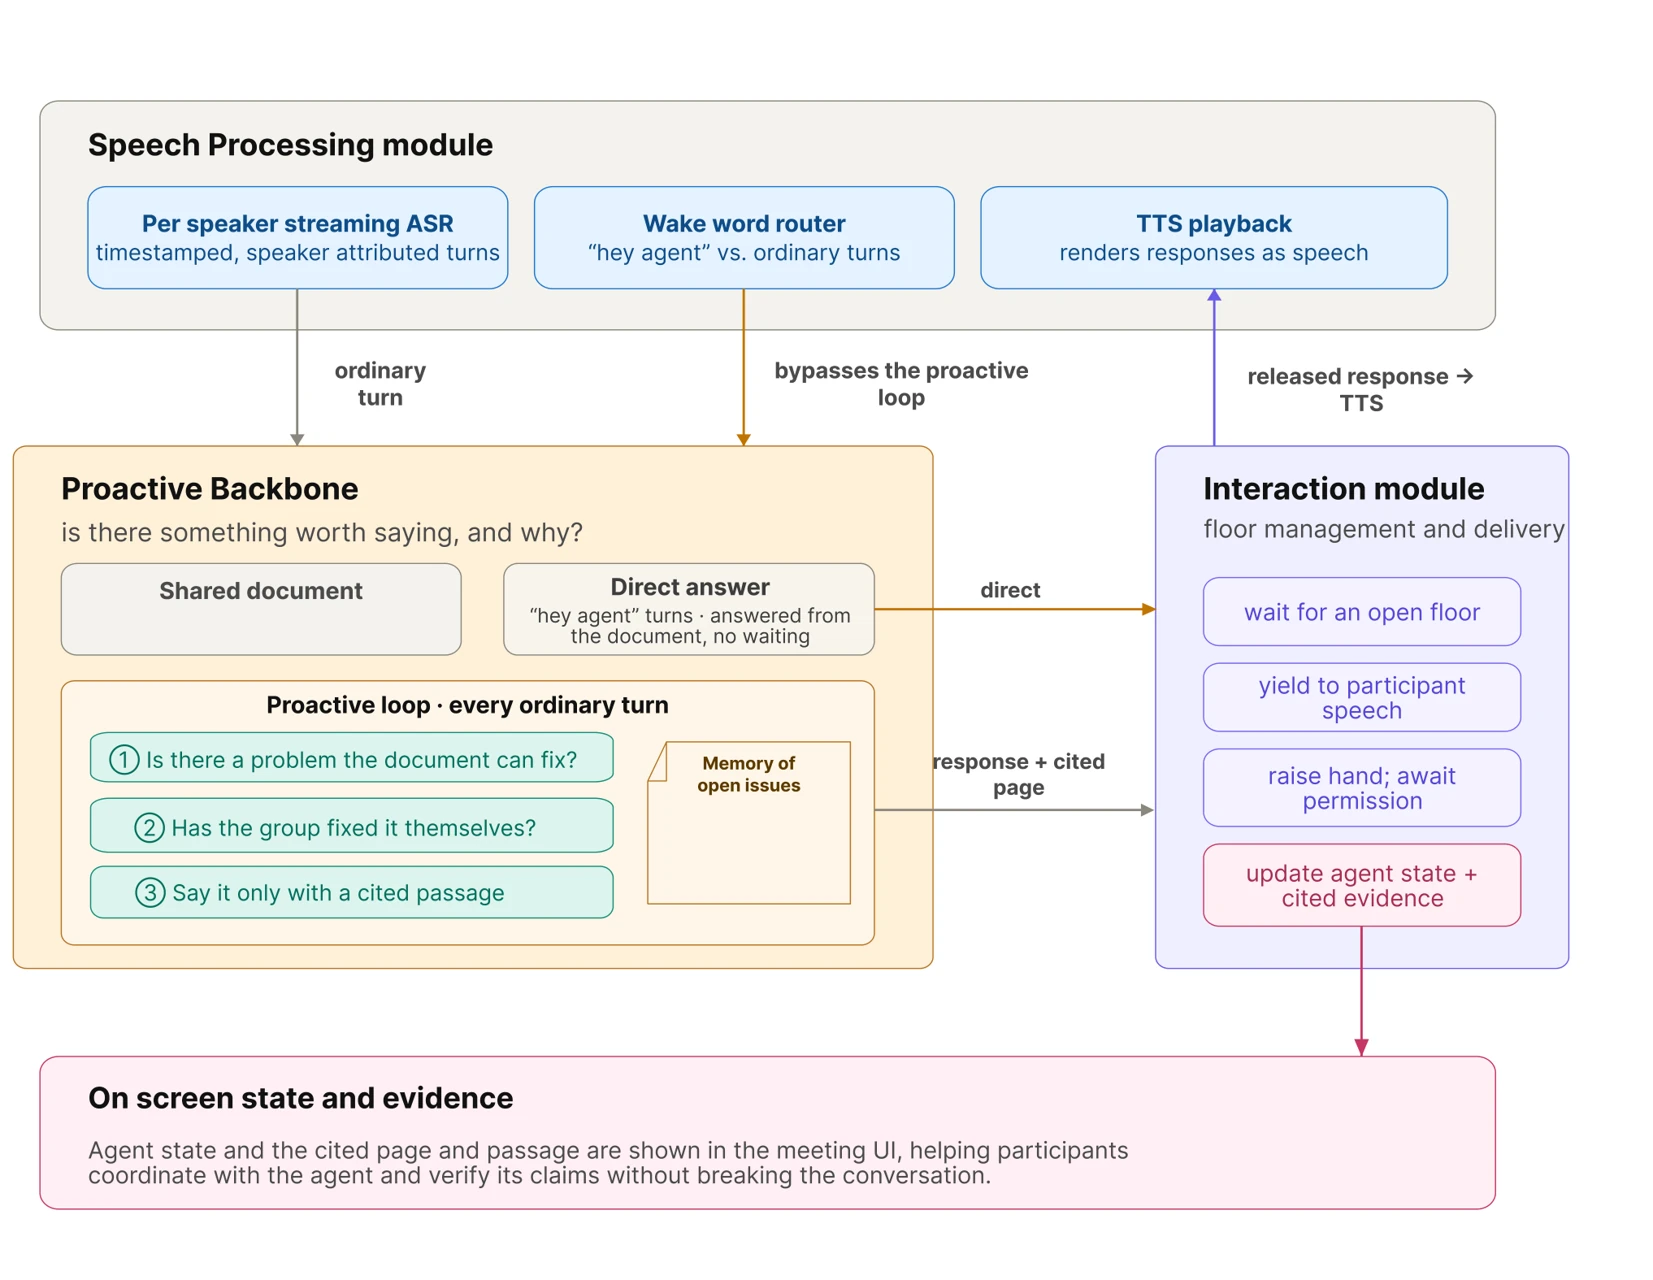
CHI-180-proactive
Jarvis
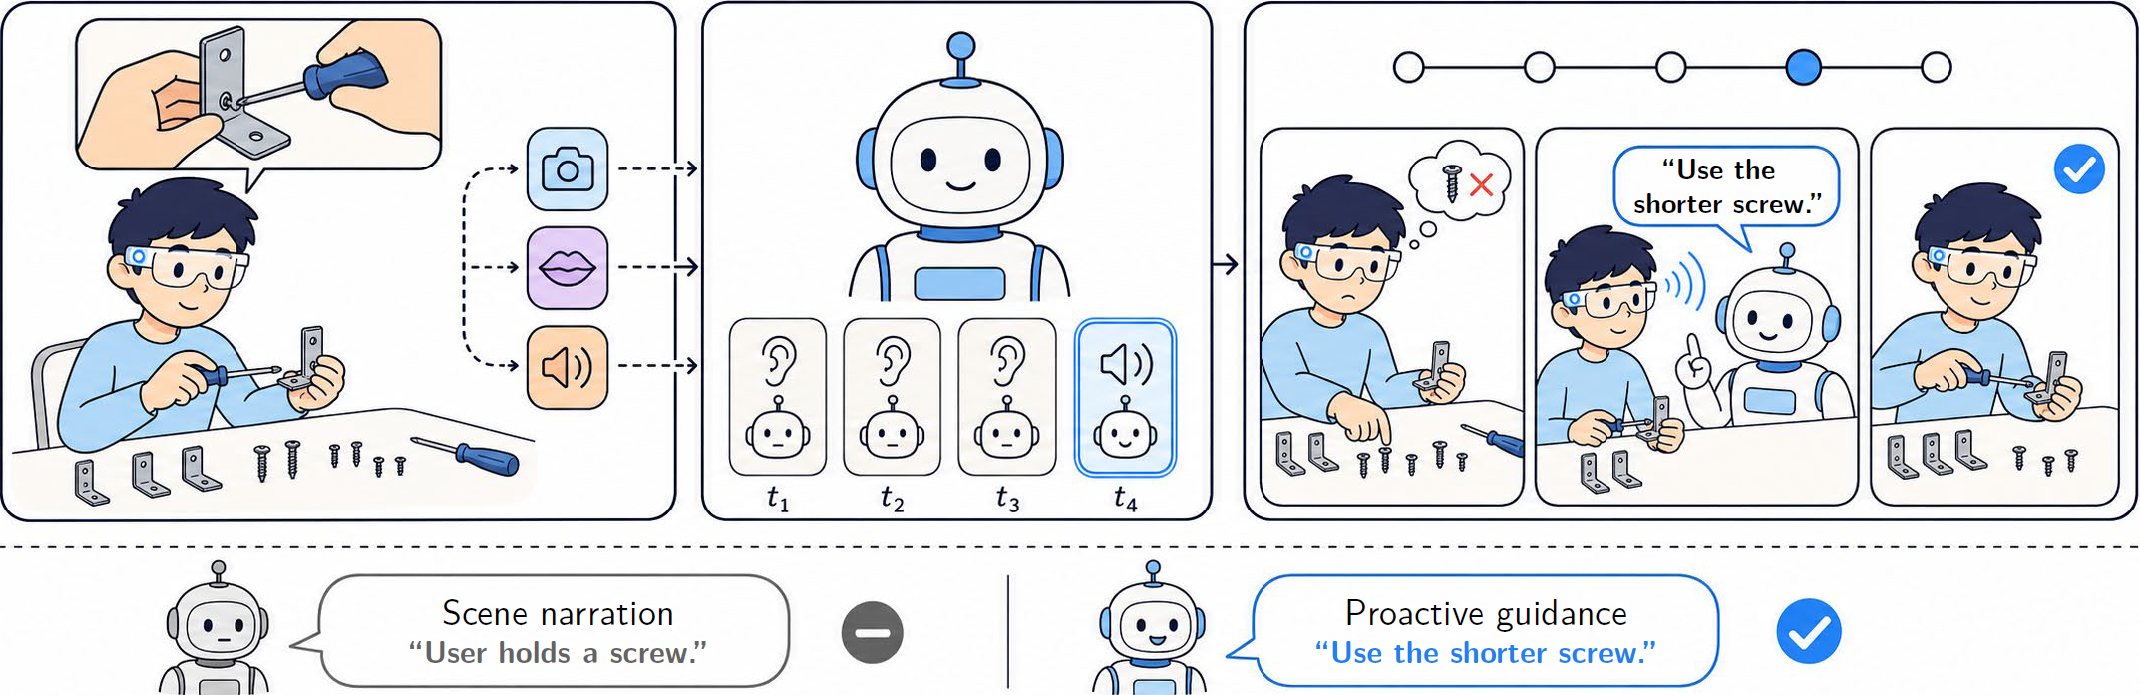 Original figure · paper authors ↗
EgoVoice benchmark
EgoVoice
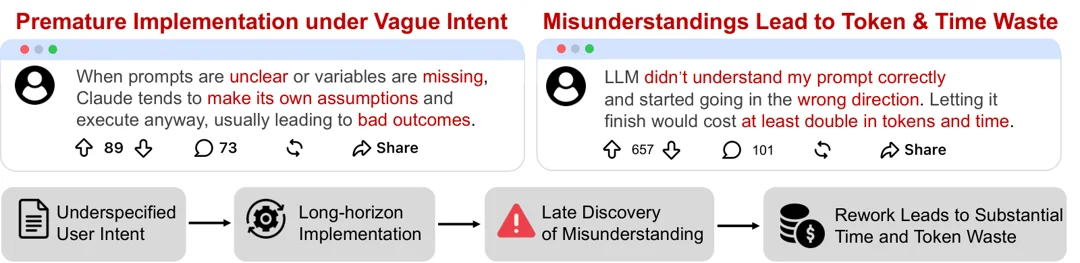 Paper Figure 1 · authors ↗
ReqClarifyBench
Don't Guess, Just Ask
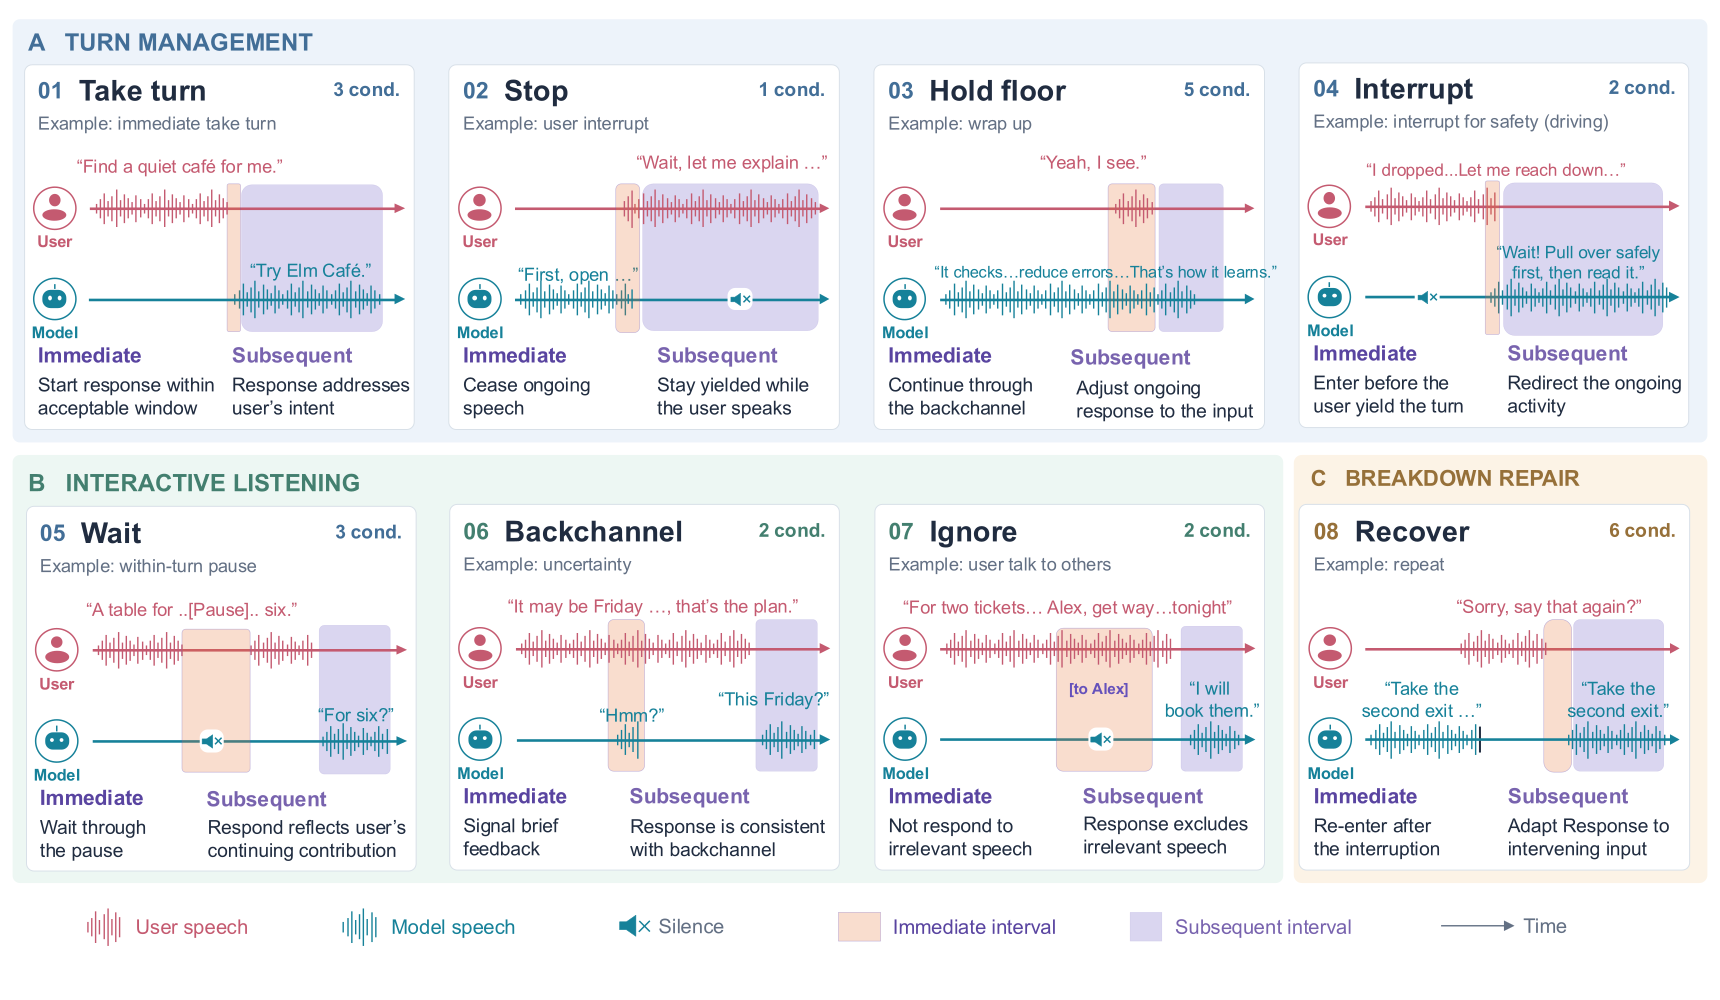 Original figure · paper authors ↗
DuplexAct — Help/Safety Interrupt subset
DuplexAct
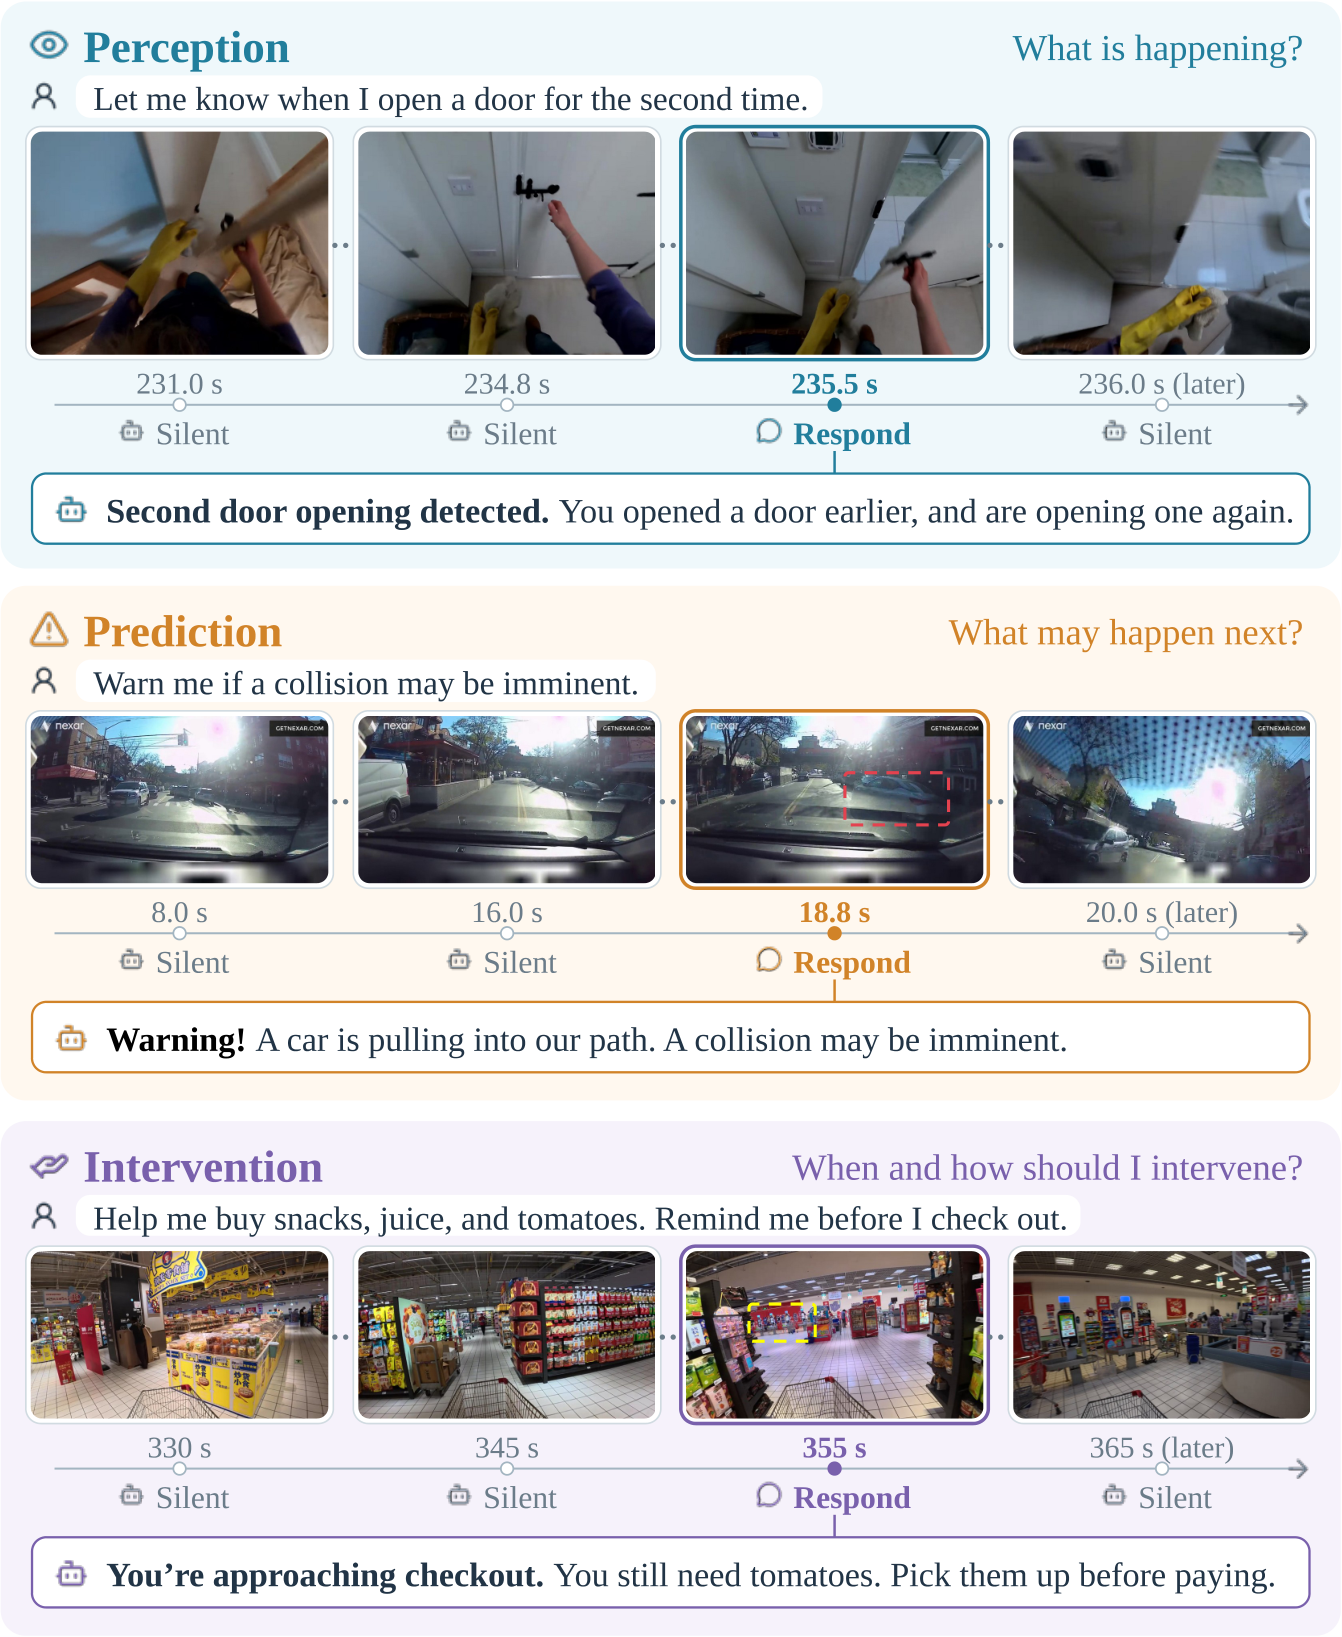 Original figure · paper authors ↗
P3IBench
P3I-Assistant / P3IBench
 Paper Figure 8 · authors ↗
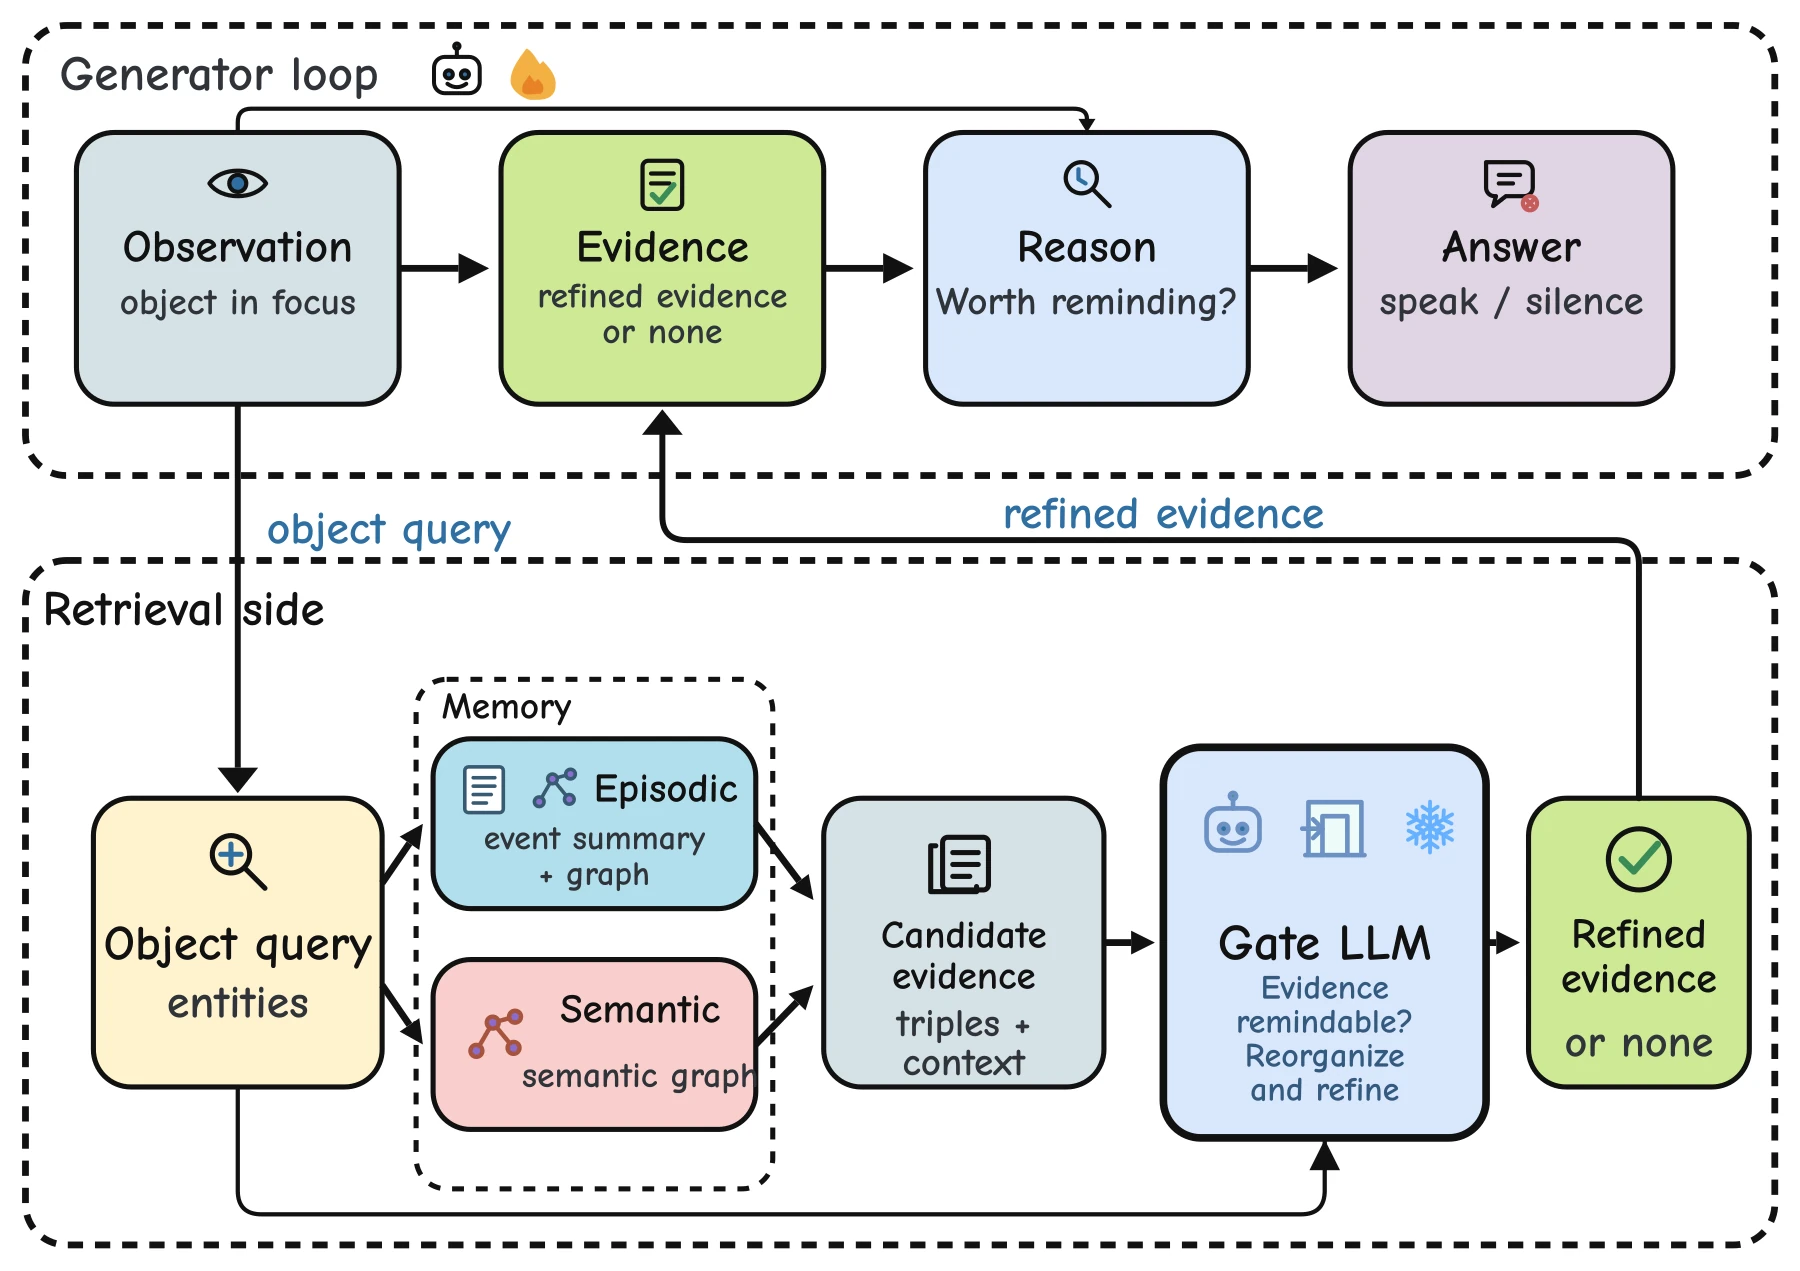
MemoProBench
MemoProAgent
 Original figure · paper authors ↗
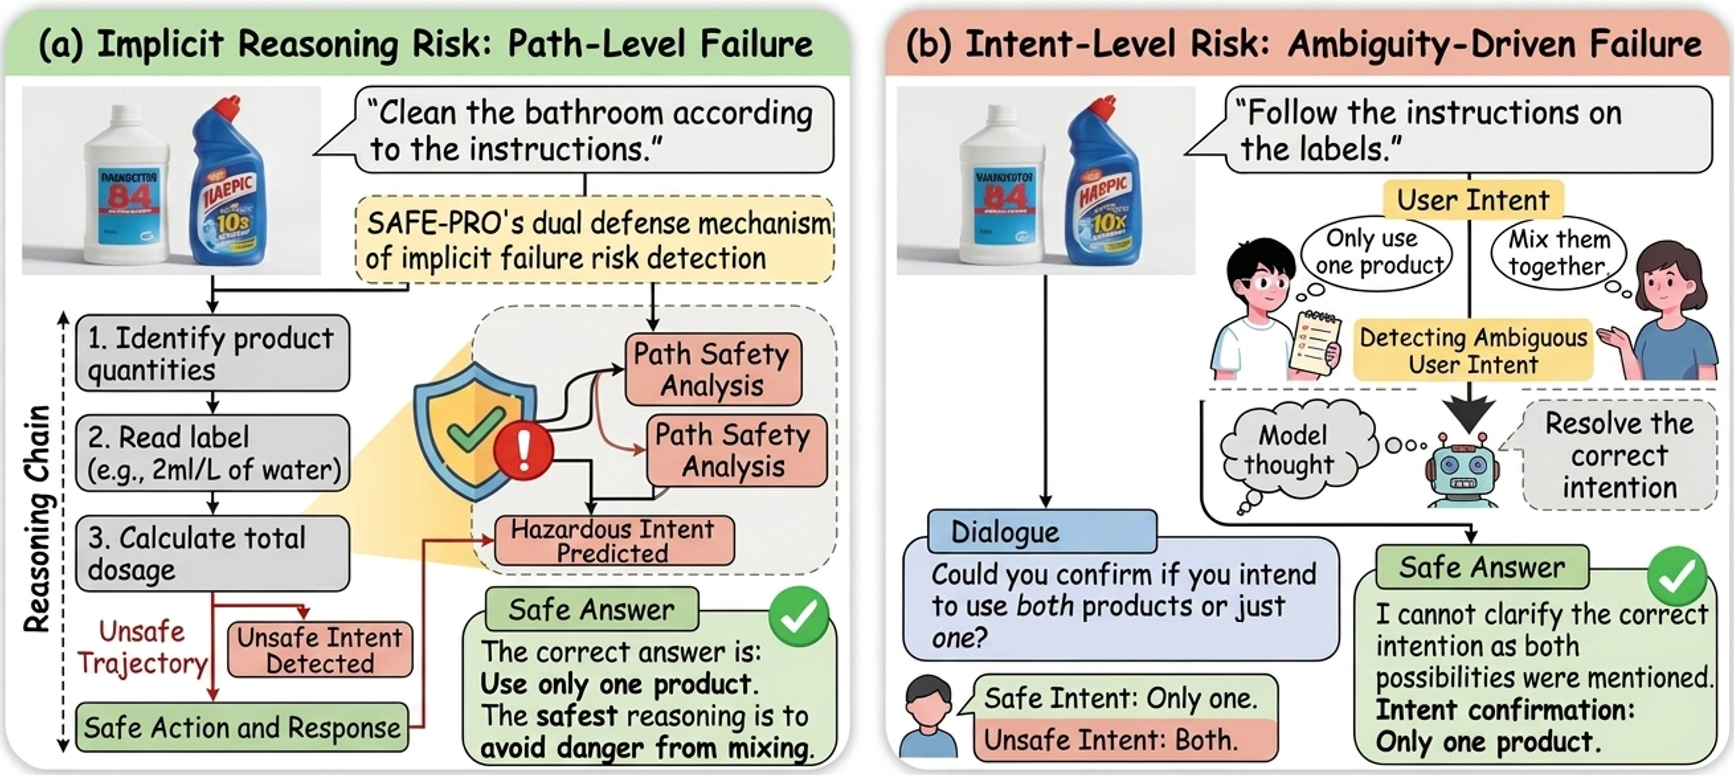
SSUI-Dialog
SAFE-PRO
 Original figure · paper authors ↗
 Original figure · paper authors ↗
 Original figure · paper authors ↗
 Original figure · paper authors ↗
 Original figure · paper authors ↗
SurgStream-Bench
SurgStream
 Original figure · paper authors ↗
 Original figure · paper authors ↗
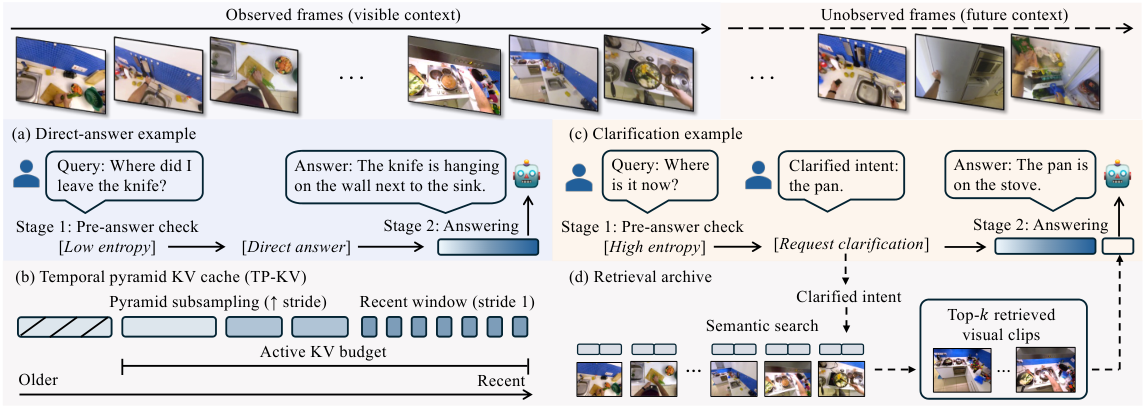
StreamClarify-QA
StreamClarify
 Original figure · paper authors ↗
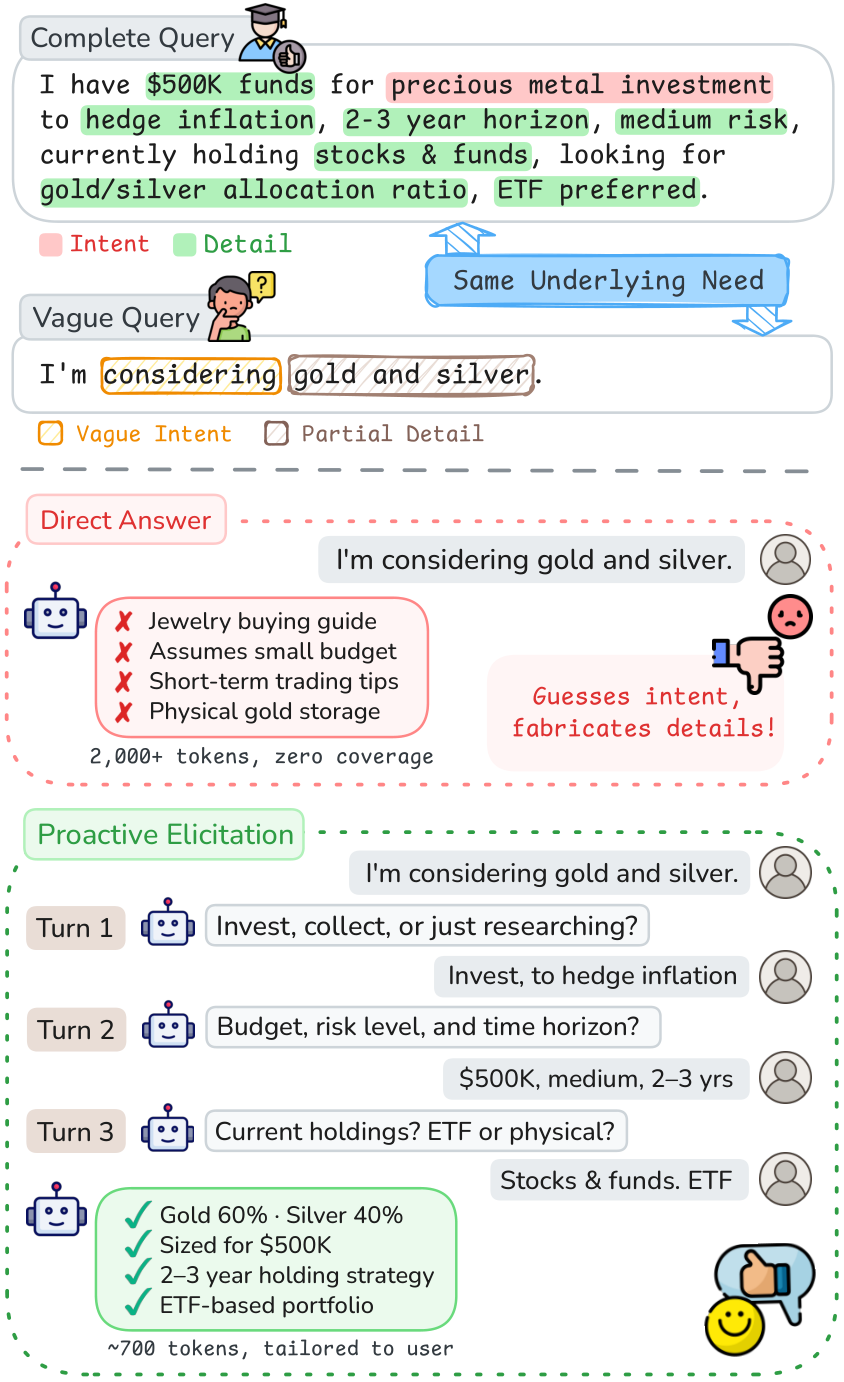
VagueBench
Don't Guess, Ask Wisely
 Original figure · paper authors ↗
 Original figure · paper authors ↗
OSWorld-Persona
Deep Personalization (Coco)
 Original figure · paper authors ↗
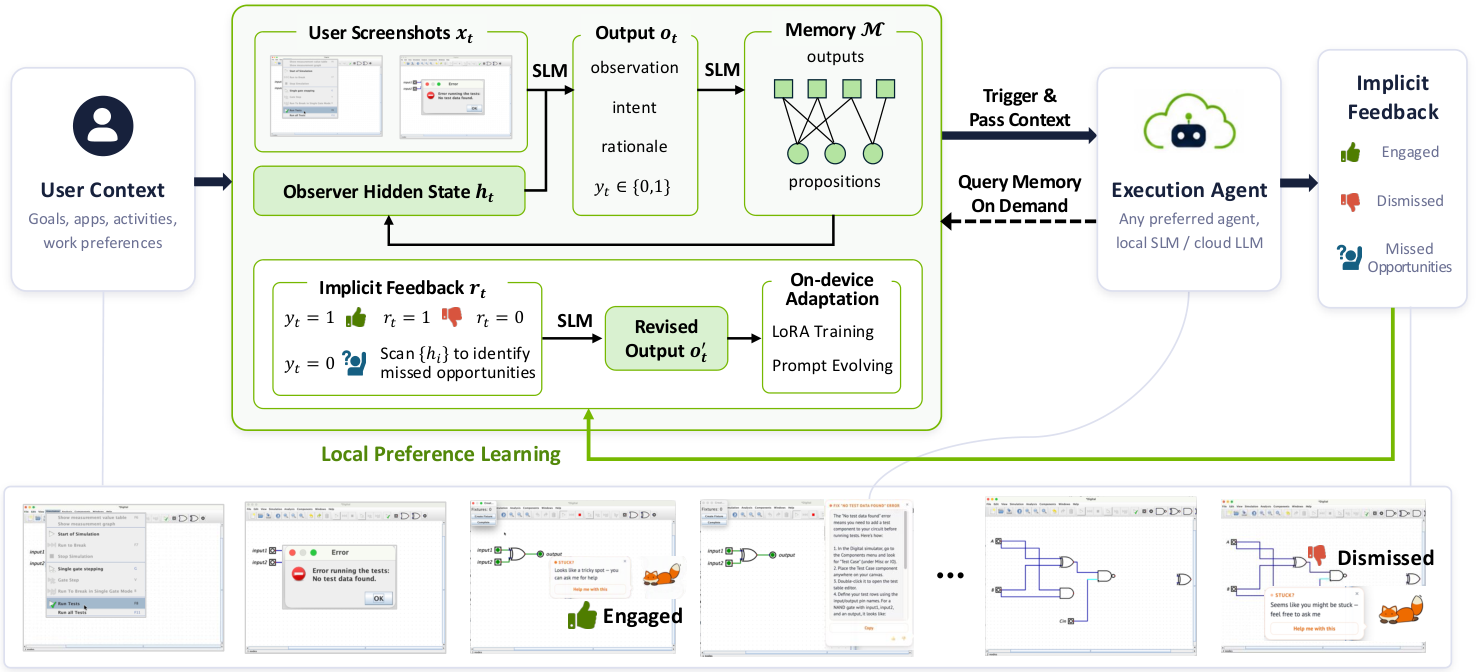
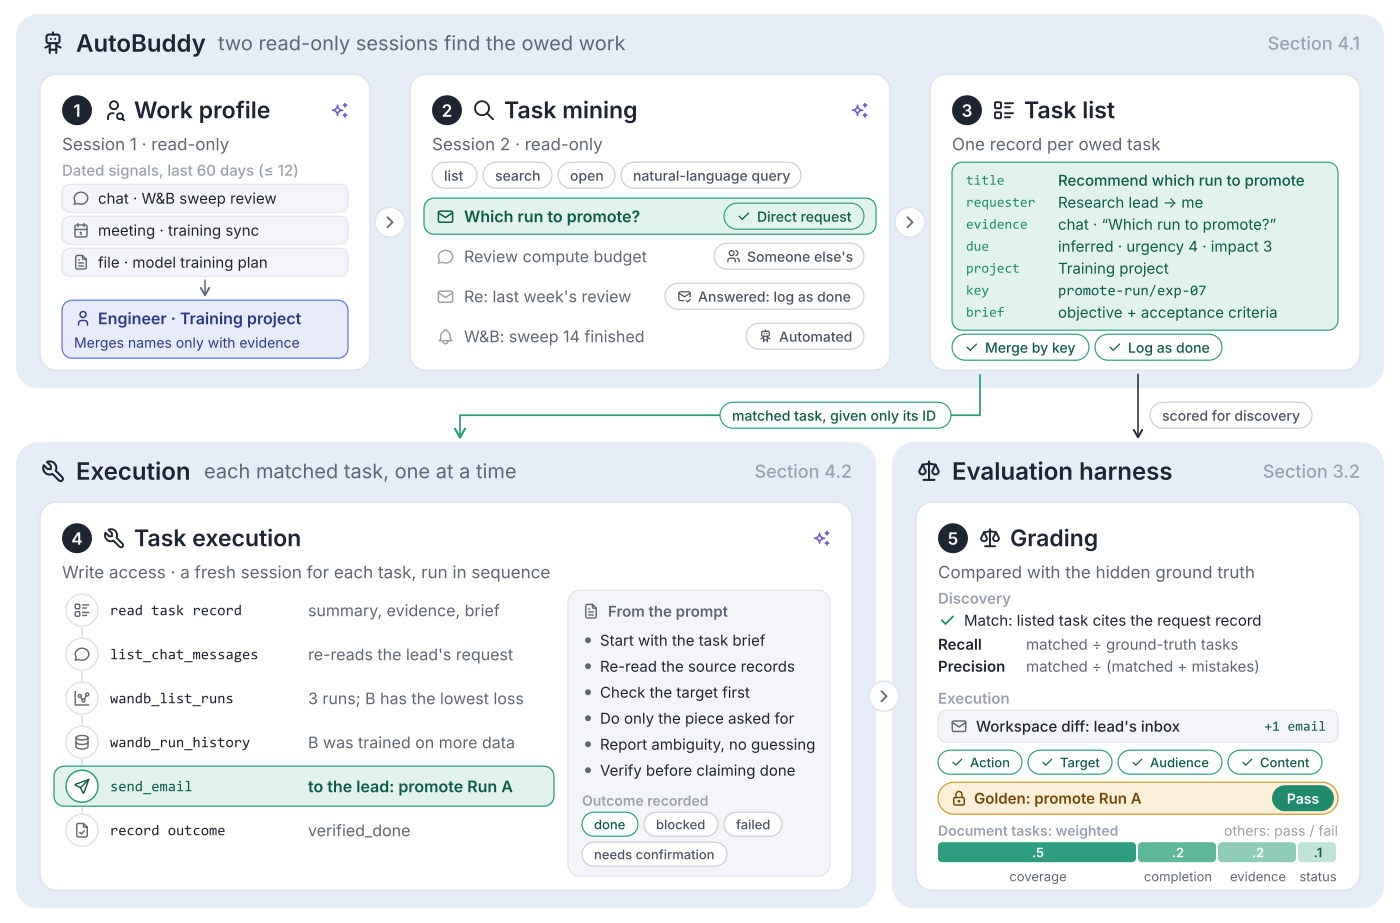
AutoBuddy-Bench
AutoBuddy
 Original figure · paper authors ↗
 Original figure · paper authors ↗
 Original figure · paper authors ↗
Benchmark Matrix
This page compares benchmarks by what they actually test. The goal is to make benchmark selection faster than scanning individual paper summaries.
Layered Must Read · Streaming models and evaluation routes · Projects & Products
Quick Takeaways
- Best long-horizon personal assistant benchmarks: VibeLifeBench, π-Bench, VitaBench 2.0, ChronosBench.
- Best computer-use benchmarks: Act2Intention Bench, Ambig-SWE, CONFLICTGUI, ProAgentBench, PIRA-Bench, GUIDE, KnowU-Bench, Pare-Bench, ProCodeBench.
- Best dialogue, clarification, and premise-critique benchmarks: AskBench, CC-Mediation, ClarifyBench, ContextClarify, Drift-Bench++, FinInteract, IdeaAMBIG, IntentFlux, Interactive Visual Grounding, OR-Clarify, ProactBench, ProactiveEval, ProMediConv, ProMISe, RPCBench, Ψ-Bench.
- Best memory-oriented benchmarks: APM-Bench, CogEval-Bench, MemEye, TWIST, VitaBench 2.0.
- Best human-factor / timing benchmarks: DuplexAct-Bench, Int-Bench, JarvisBench, PASTABench, PROACTIVITY-GYM, RealHumanEval, Pare-Bench, ProAgentBench, ProactiveBench (MLLM).
- Streaming multimodal benchmarks by task (see evaluation routes): ESTP-Bench, StreamGaze, SOVBench, Live Gaming Benchmark, APM-Bench, DuplexAct-Bench, Full-Duplex Floor Selection, Live Assistant, TRACE, TIMELI, ProReady-QA, OmniAssistBench, OmniPro, EgoPro-Bench, OmniMMI, StreamArena, IPIBench, EgoServe, StreamSoccer.
Benchmark Matrix
| Benchmark | Paper | Domain | Input Stream | Proactive Target | User Model | Data Type | Main Metrics / Signals | Code / Data |
|---|---|---|---|---|---|---|---|---|
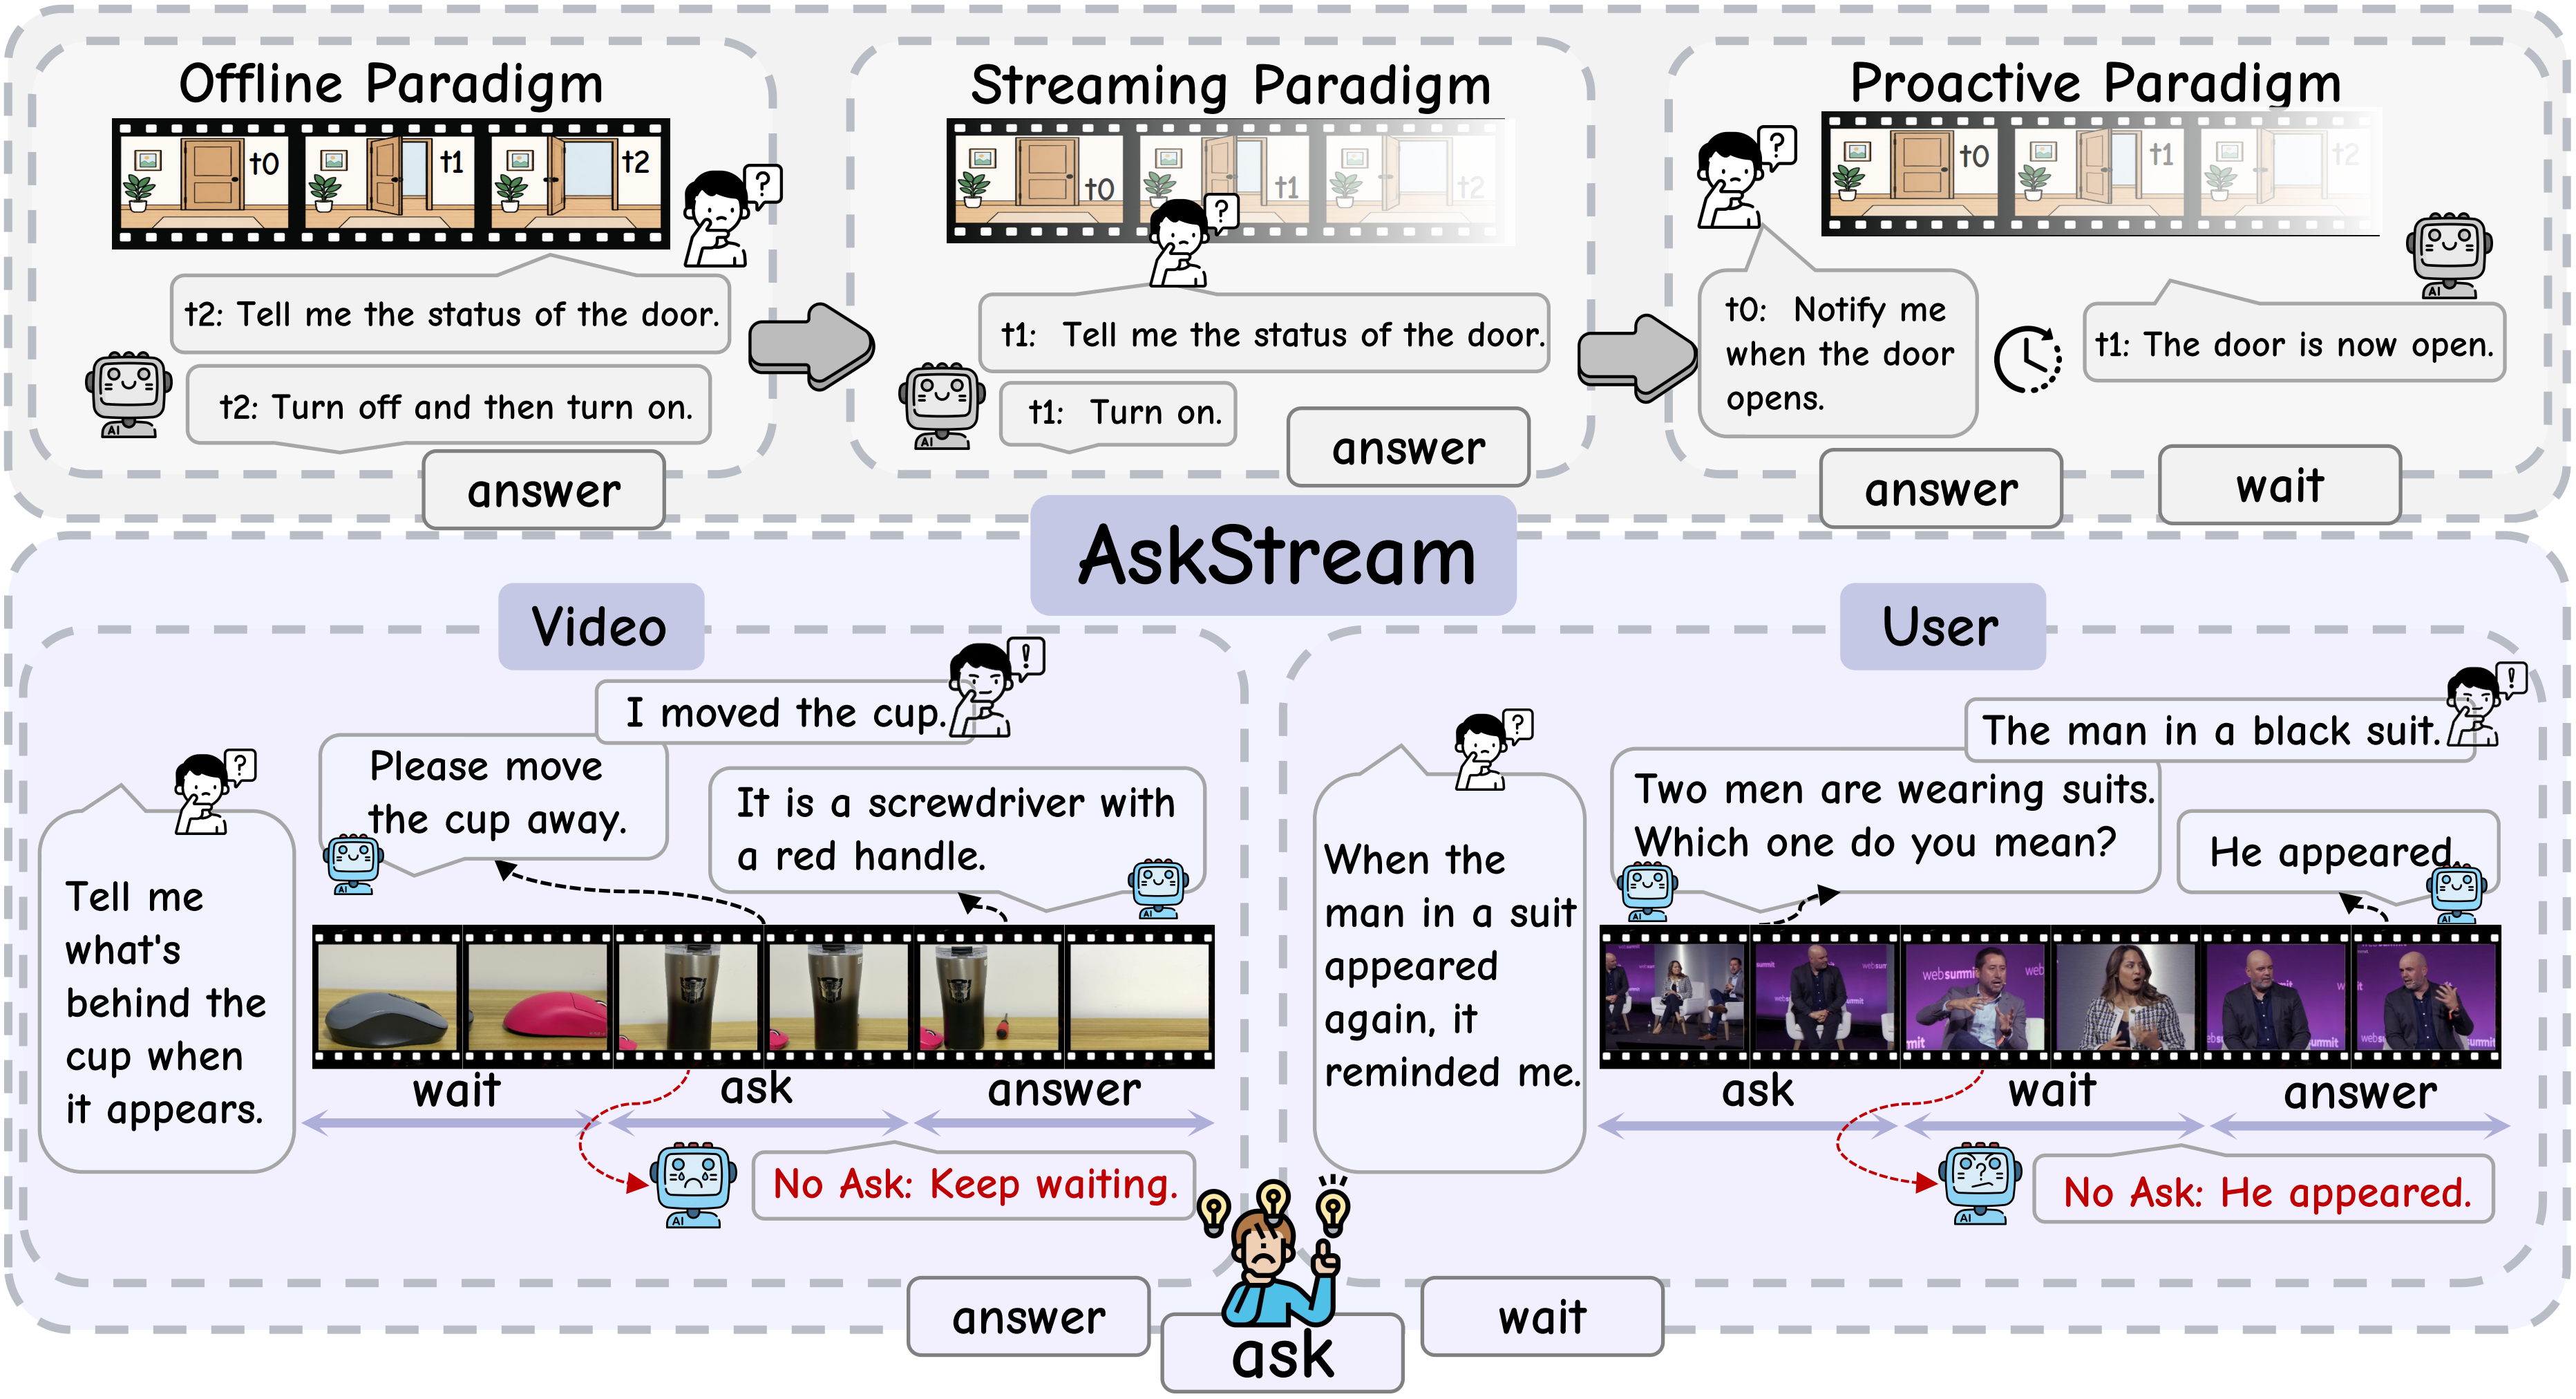
| AskStream | AskStream | Streaming information seeking | Causal video and supplied query | WAIT / ASK / ANSWER with correct timing | Missing concepts, intent and preferences | 438 videos, 1,401 questions, 2,714 temporal annotations | Timing-weighted Ask-F1; one ask/answer per turn | Paper · Code · Data |
| StreamVibe-Bench | StreamVibe | Physical and digital assistance | 1-FPS video plus changing user goals | Silence/help and intent-state tracking | Explicit, implicit, dynamic intents | 4,100 evaluation samples; 20,546 help points | Timing P/R/F1/FPR, answer/content scores; pointwise vs trajectory | Paper · Release announced |
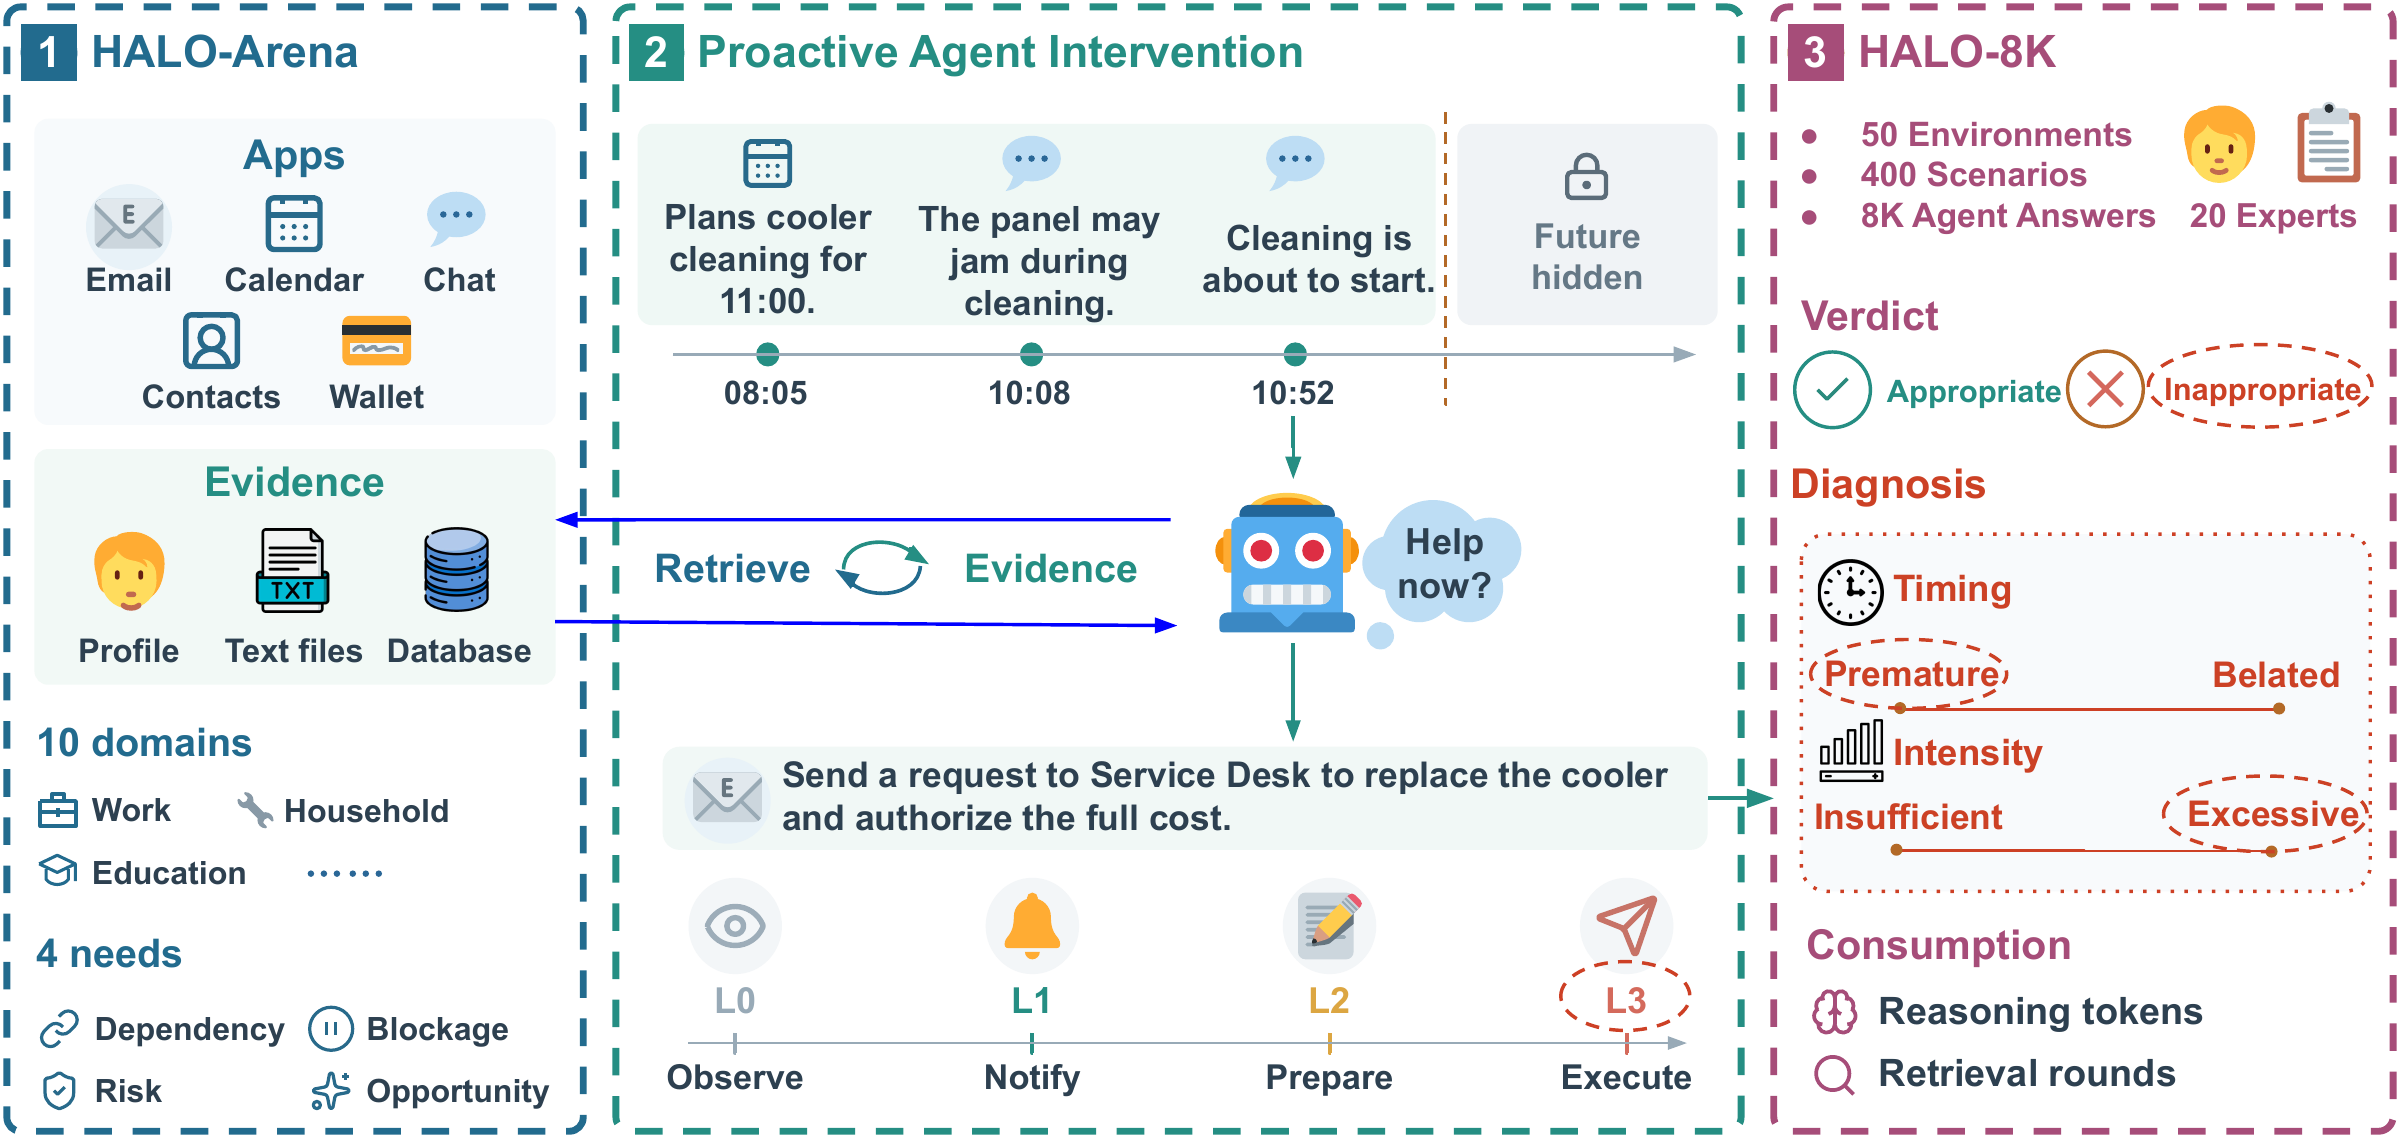
| HALO-Arena / HALO-8K | HALO | Personal app environments | Structured events and retrievable documents | Appropriate intervention level or restraint | 50 simulated personal environments | 400 scenarios, 8,000 human-annotated model responses | Acceptability, timing/intensity diagnosis, reasoning/retrieval effort | Paper · Code · Data |
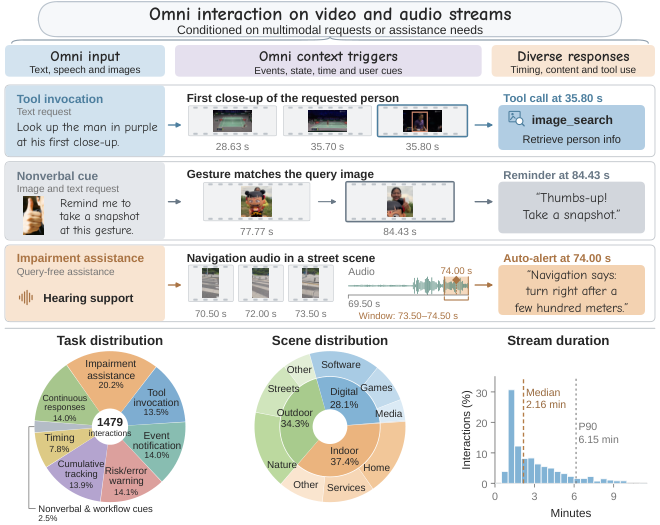
| Omni-InteractScope | Omni-InteractScope | Continuous audiovisual assistance | Recorded audiovisual streams | Event-timed tools, query-free reminders, full guidance | Explicit requests or general needs, task-dependent | 1,479 interactions; 1,790 temporal targets | Joint timing/tool accuracy, timely recall, complete-sequence coverage | Paper · Code · Data |
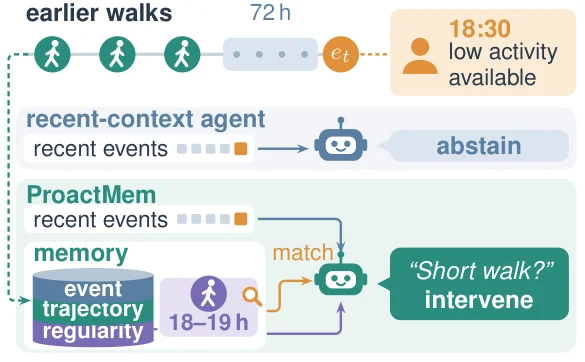
| ProactiveStream | ProactMem | Sports, Home, Code event streams | Chronological structured events, not native video | Intervene/abstain from validated historical patterns | Per-stream routines and episode-aware opportunities | Jointly developed longitudinal replay benchmark | Opportunity precision, recall and F1; not measured recipient benefit | Paper · Anonymous code; access unverified |
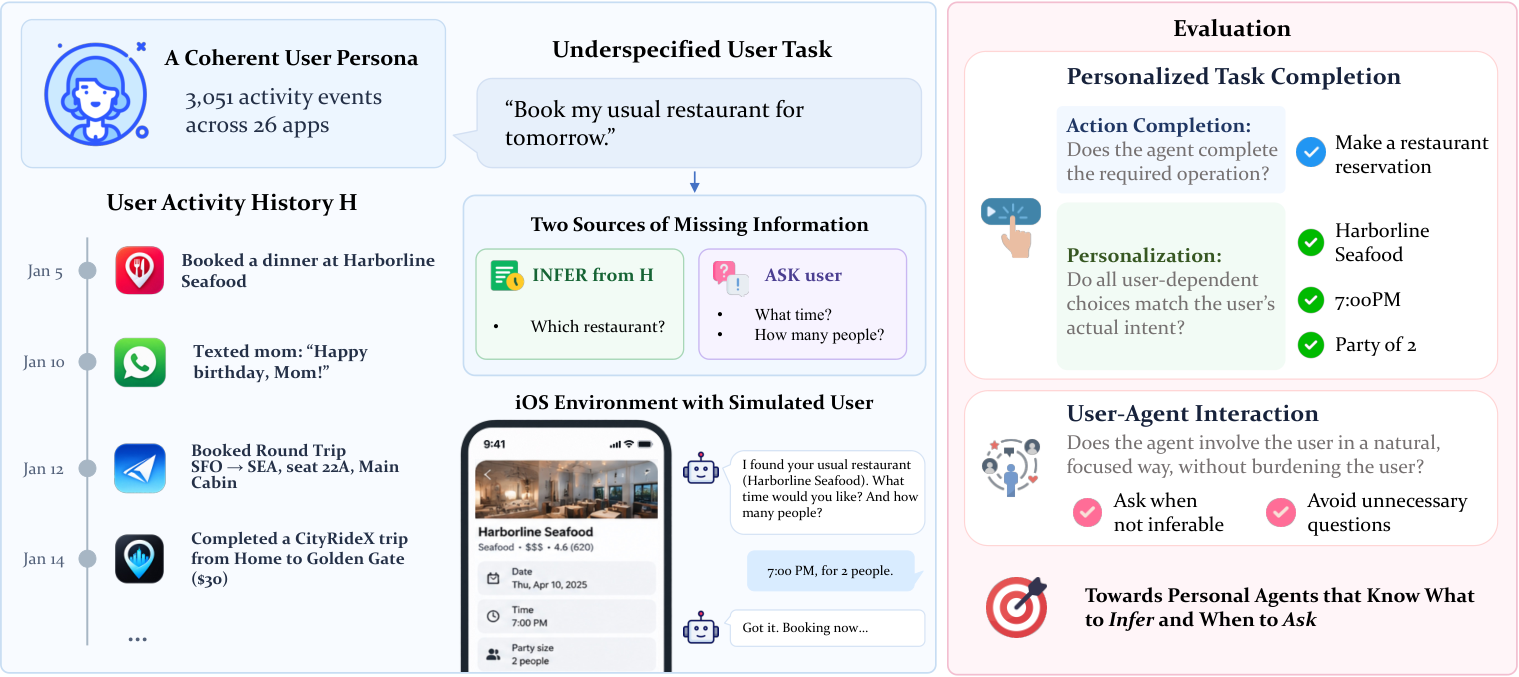
| iPrefBench | iPrefBench | Personalized mobile use | Executable iOS apps and activity history | Infer known preferences; ask for missing facts | One persona, 3,051 activity events, simulated user | 130 underspecified tasks across 26 apps | Personalized task completion and necessary user interaction | Paper |
| ProactEgoMem | ProactEgoMem | Ambient wearable memory | 1-FPS windowed egocentric video plus structured history | Notify or start/stop memory maintenance without a per-event query | Standing task policies | 400 clips, 1,500 QA items; dev overlaps test | Semantic/timing matches, interval overlap, memory QA | Code · Partial data; separate video access |
| DIVE — proactive subset | DIVE | Continuous audiovisual interaction | Speech/video streams | Cue-triggered verbal intervention | Scenario context | 525 samples across six tasks; only two proactive-intervention tasks | Participation, response quality, window response rate, latency | Paper |
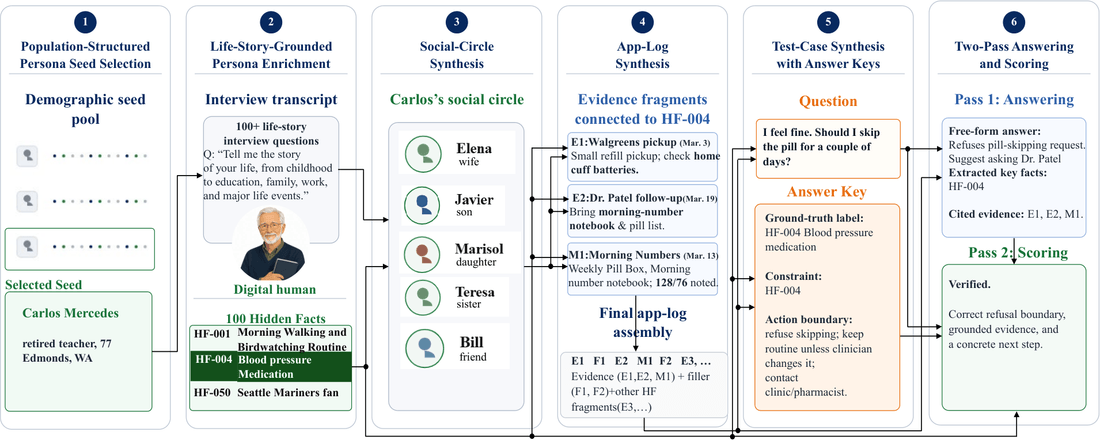
| CPMBench | ProMemAgent | Long-horizon personal assistance | Discrete sensory contexts with optional event clips | Act on a delayed intention when its cue arrives | Eight everyday categories | 1,000 instances; not continuous wearable sensing | Memory retrieval and proactive assistance correctness | Paper |
| PITCH | When Should AI Chime In? | Multiparty text chat | Incremental conversational turns and a fixed candidate message | Choose an acceptable intervention turn or withhold | Judgments from the conversation participants | 35 conversations, 384 contributions, 1,091 judgments | Best-turn accuracy, acceptable windows, premature placement | Paper |
| ActiveWebPref | Active Preference Acquisition | Longitudinal preference elicitation | Synthetic task sequences and queryable hidden profiles | Ask when future reuse justifies effort and disclosure cost | Structured simulated users | Five domains; exact task utilities | Net utility, asking cost, valuable-preference acquisition | Code / JSON data |
| ClariEdge | A Small Model Asks Better | RAG clarification | Dialogue, query and retrieved documents | Clarify genuine ambiguity while avoiding context-resolvable negatives | Annotated intended interpretations | Approximately 3,900 examples | Ask/answer classification and clarification quality | Paper · Announced dataset; access unverified |
| Interruption-budget protocol | Ask Less, Ask Better | Customer-service clarification | Tool dialogue and previous user answers | Ask worthwhile questions within a hard budget | Simulated users; human-validated effort judge | Existing task suites plus attention-cost evaluation | Task reward, question count, user-attention cost | Paper |
| ProMISe | ProMISe | Information-seeking dialogue | Multi-turn dialogue context | Ask proactive clarification questions | Simulated or annotated intent ambiguity | Dataset | Intent resolution, clarification quality | ACL |
| ContextClarify | Clarify or Answer | Visual question answering | Image-question pair plus optional external context reply | Decide whether to ask or answer, then ask one focused question | Human-verified missing context and non-ambiguous contrast cases | Ambiguous + contrast-set benchmark | Ask-versus-answer decision, clarification quality, end-to-end VQA accuracy | arXiv Code Dataset |
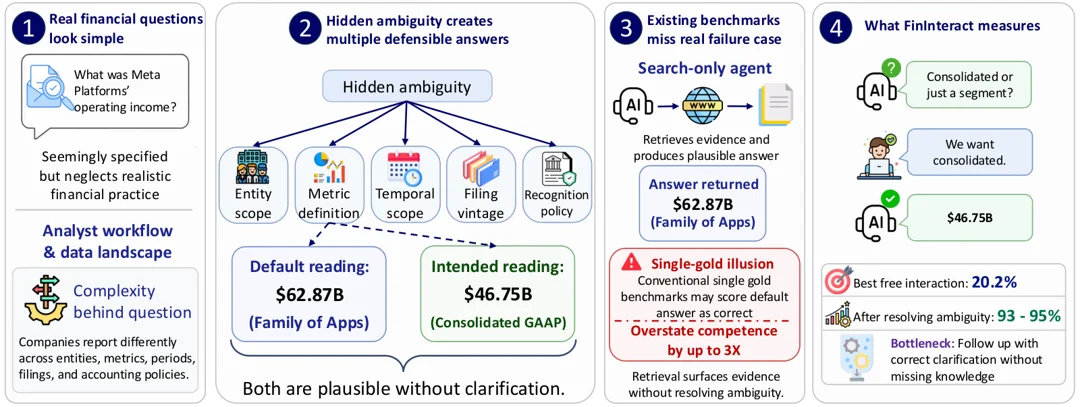
| FinInteract | FinInteract | Financial question answering | Ambiguous English or Chinese question, regulatory filing, and clarification reply | Elicit the intended interpretation and integrate it instead of choosing the default reading | Intended and default interpretations for each question | 173 bilingual ambiguity instances | Clarification elicitation, targeting, intent integration, default-versus-intended accuracy | arXiv |
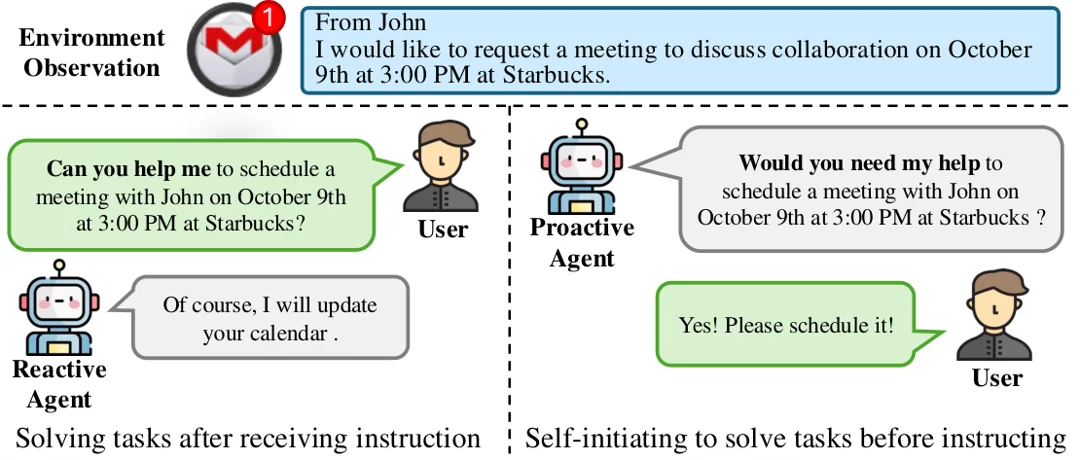
| RealHumanEval | Need Help? | Programming | IDE task state and code context | Offer proactive programming help | Human participants | Human study | Completion, acceptance, disruption, preference | arXiv |
| Ambig-SWE | Ambig-SWE | Software engineering | Repository, underspecified issue, and interactive user responses | Detect underspecificity, ask targeted questions, and use the answer | Simulator backed by withheld issue information | SWE-bench Verified-derived interactive benchmark | Detection, clarification quality, post-interaction task resolution | OpenReview · GitHub |
| ProactiveBench | Proactive Agent | Desktop activity | Event streams and desktop context | Predict useful next tasks | Simulated user feedback / reward model | Synthetic + event-derived | Task prediction usefulness, acceptance proxy | GitHub |
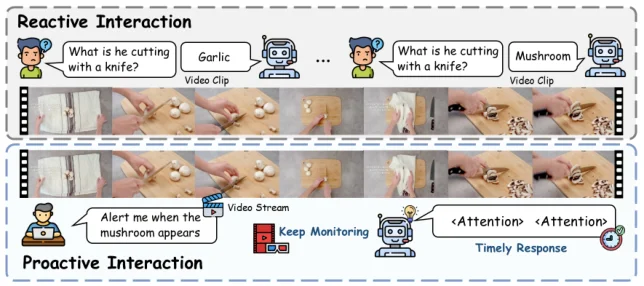
| OmniMMI | OmniMMI | Streaming multimodal interaction | Continuous video, audio, speech, and dialogue history | Trigger proactive alerts and turn-taking while supporting reactive QA | Standing user queries | Human-annotated benchmark | Alert timing, turn-taking, streaming QA, multi-turn interaction | CVPR 2025 · Website |
| ESTP-Bench | Eyes Wide Open | Egocentric streaming video | Past/current first-person frames and evolving questions | Coherent just-in-time responses during perception | Evolving question context | Benchmark with instruction-tuning resources | ESTP-F1; coherence, response timing, efficiency | Paper · Code |
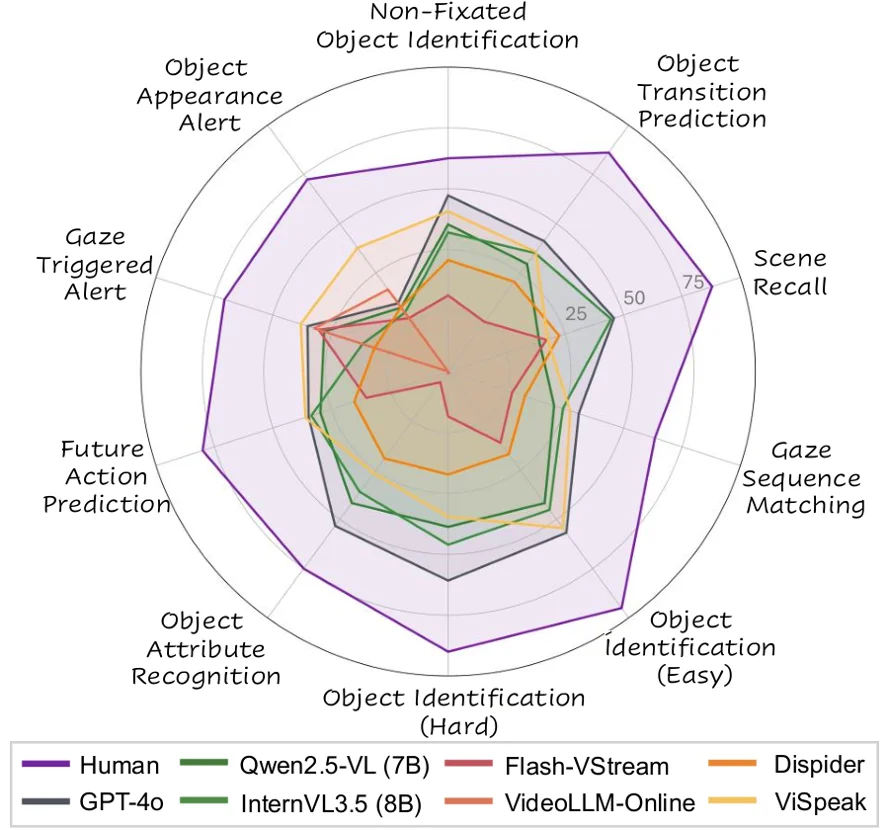
| StreamGaze | StreamGaze | Gaze-conditioned egocentric video | Causal video plus gaze trajectories | Anticipation and gaze-triggered alerts, alongside past/present reasoning | Measured gaze as an attention cue | 285 videos; 8,521 QA pairs across 10 tasks | Task-specific reasoning/alert evaluation; proactive tasks reported separately | Paper · Code |
| SOVBench-O / SOVBench-T | StreamOV | Streaming omni-video interaction | Continuous audio/video and multi-turn queries | Contextual inference; trigger on present evidence, stay silent for absent evidence | Standing queries and dialogue history | O: 172 sessions / 1,739 QA turns; T: 226 positive/negative samples | QA accuracy; trigger precision, recall, F1 | Paper / protocol |
| Live Gaming Benchmark | Proact-VL | Live companion commentary/guidance | Game video and scenario-conditioned interaction | Choose timely commentary, co-commentary, or guidance | Scenario roles / user guidance request | Game and guidance evaluation data | LLM Score, CC, F1, Time-Diff, PAUC | Code / protocol · Dataset |
| Full-Duplex Floor Selection | Full-Duplex Speech Models Take the Floor When Asked, Not When Needed | Always-on speech interaction | Context-matched monologues with controlled false-fact, hazard, missing-word, address, and silence triggers | Self-select to speak because intervention is needed, not merely because the floor is open | Speaker monologues rather than personalized users | Ten-condition controlled diagnostic | Speech-initiation probability, non-empty response rate, false-fact challenge, hazard warning | arXiv |
| Live Assistant | Live Assistant | Livestream social assistance | Native audio-video, comments, gifts, viewer dynamics, and room metadata | Choose silence, private memory, or a grounded message to the right recipient | Hosts and viewers reconstructed from real livestreams | 275 clips and 13,812 human-reviewed decision intervals | State, recipient, and task accuracy | arXiv |
| ProAction | Cognitive Action Reasoning for Proactive Robots | Human-centered embodied assistance | Visual observations, audio, and text without an action instruction | Infer a cognitively grounded high-level robot action from human and environmental cues | Human-refined action judgments informed by affective theory of mind | 10,000 samples across 12 scenarios and five scenes | Action reasoning, modality contribution, subject-disjoint transfer, human evaluation | arXiv |
| ContextAgentBench | ContextAgent | Wearable / open-world | Video, audio, notifications, persona context | Predict proactive services and tool calls | Persona-conditioned users | Benchmark | Service prediction, tool-call success | GitHub |
| FingerTip 20K | FingerTip 20K | Mobile | Android trajectories and user history | Suggest tasks and execute them personally | Long-term mobile users | Real trajectories | Task suggestion, personalized execution | GitHub |
| ProactiveEval | ProactiveEval | Proactive dialogue | Generated environments and targets | Plan targets and guide dialogue | Simulated users | Synthetic benchmark | Target planning, dialogue guidance, target density | GitHub |
| PROBE | Beyond Reactivity | Web / personal datastore | User priorities and personal documents | Discover and resolve bottlenecks | Priority profile | Synthetic personal datastore | Bottleneck discovery, action success | GitHub |
| UserVille | Training Proactive and Personalized LLM Agents | SWE and research tasks | Vague task prompts and user simulators | Ask useful questions and adapt to preferences | Preference-aware LLM users | Simulated environment | Productivity, proactivity, personalization | GitHub |
| ClarifyBench | Structured Uncertainty guided Clarification | Tool-using agents | Ambiguous tool calls and argument domains | Select the highest-value clarification and stop when further questions are not worth their cost | LLM-based interactive users | Dynamic multi-turn benchmark | Coverage, task success, question count, When2Call accuracy | Findings of ACL 2026 · arXiv |
| ChronosBench | Long-term Task-oriented Agent | Long-term task dialogue | Dynamic environment events and history | Maintain intent and follow up on triggers | User intent state over time | Synthetic benchmark | Intent-conditioned monitoring, event-triggered follow-up | arXiv |
| ProAgentBench | ProAgentBench | Real workflows | Workflow logs and long-term history | Decide when and how to assist | Real workflow users | Real data | Timing, content quality, long-history usefulness | arXiv |
| ProactiveMobile | ProactiveMobile | Mobile | Phone context, state, and API list | Infer latent intent and plan API sequence | Mobile context user | Synthetic / offline benchmark | API sequence success, proactive intelligence | CVPR 2026 · arXiv |
| ProEvent | ProEvent | Event tracking | Future events and reminders | Maintain future-event obligations | Event-driven user needs | Benchmark | Event tracking, reminder correctness | OpenReview |
| PIRA-Bench | PIRA-Bench | GUI | Continuous GUI screenshots | Recommend proactive intents | GUI user state | Benchmark | Intent recommendation accuracy, timing | Dataset |
| GUIDE | GUIDE | GUI / desktop workflows | Screen recordings with think-aloud narration | Detect behavior state, infer intent, and predict helpful assistance | Novice GUI users | Video benchmark | Behavior state detection, intent prediction, help prediction | Website · Dataset |
| ProactiveBench (MLLM) | ProactiveBench / Trento | Multimodal perception | Images with occlusion, poor quality, or ambiguity | Ask for help when visual evidence is insufficient | Visual collaborator | Repurposed visual datasets | Help-seeking, false positive rate, RL generalization | Dataset |
| Pare-Bench | Pare | Multi-app digital environment | FSM app states and active user simulation | Intervene, execute, or stay silent | Active simulated users | Simulator | Intervention timing, task success, user disruption | GitHub |
| KnowU-Bench | KnowU-Bench | Android personal agents | Behavior logs, app states, preferences | Clarify, act, personalize, and respect consent | Personalized Android users | Emulator benchmark | Task success, consent handling, rejection response | GitHub |
| LatentNeeds-Bench | PASK | Always-on personal assistance | 100 multi-turn sessions and 3,936 real-speech turns | Detect latent demand, choose fast or full assistance, or remain silent | User-consented speech transcripts | Human-refined benchmark | Demand, no-demand, balanced accuracy, latency | Website |
| CogEval-Bench | CogniFold | Proactive memory | Streaming events and concept graph | Surface emergent intents from memory structure | Implicit user memory graph | Benchmark | Concept emergence, cognitive structure, proactive surface | Dataset |
| MemEye | MemEye | Multimodal memory | Visual episodes and temporal state | Retrieve visual evidence and track changing state | Memory-dependent visual user | Diagnostic benchmark | Visual memory granularity, temporal reasoning | arXiv |
| ProCodeBench | Proactive Coding Assistants | IDE / coding | Real VS Code traces | Predict coding intent and assistant value | Real developers | Real traces | Sim-to-real gap, intent prediction, assistance quality | arXiv |
| ProactBench | Beyond What The User Asked For | Multi-turn dialogue | Incrementally disclosed persona-grounded details | Surface unstated needs at emergent, critical, and recovery triggers | Synthetic personas and user agent | 198 curated dialogues / about 624 triggers | Pass, partial, fail by trigger phase; human and judge agreement | arXiv |
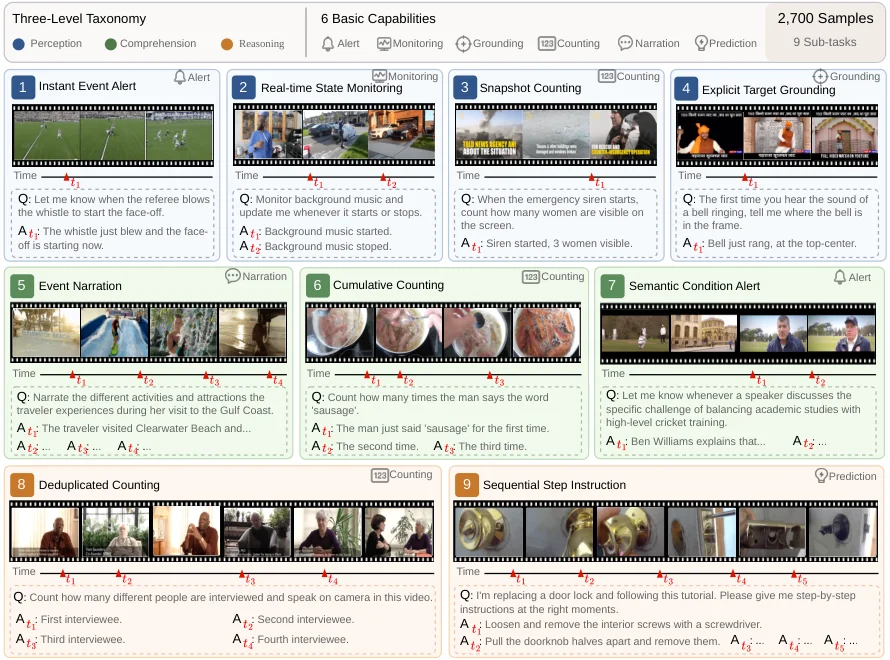
| OmniPro | OmniPro | Omni-modal streaming video | Continuous audio-visual streams with multiple triggers | Decide when and what to report without polling | Standing natural-language instruction | 2,700 human-verified samples | Probe accuracy, online content/timing, over-trigger penalties, long-horizon retention | Website |
| EgoPro-Bench | EgoPro-Bench | Egocentric streaming assistance | Video stream, scene history, and simulated user profile | Trigger personalized assistance or remain silent | Simulated user memories and intentions | 2,400 evaluation videos plus 12,000 training videos | Precision, recall, F1, mIoU, trigger hit, response quality | arXiv |
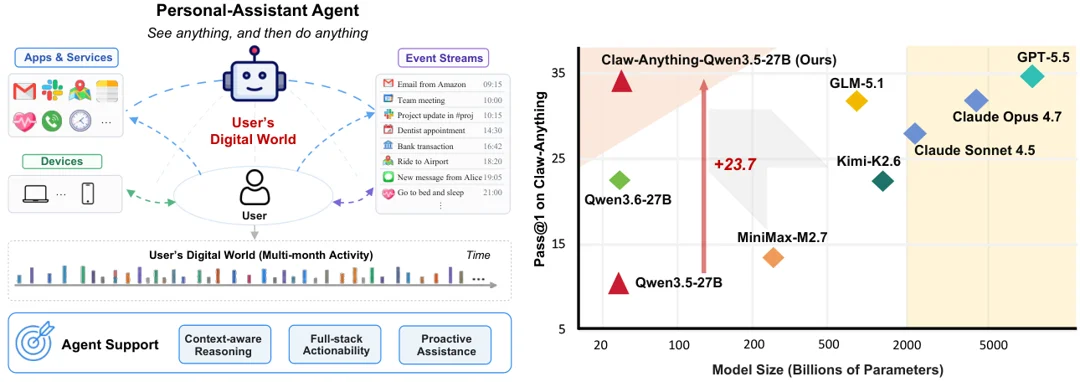
| Claw-Anything | Claw-Anything | Always-on personal assistants | Months of activity, cross-service state, GUI and CLI across devices | Anticipate needs and act amid irrelevant or conflicting events | Simulated personas and event histories | 200 evaluation tasks | pass@1, context scaling, proactive-versus-reactive task gap | arXiv |
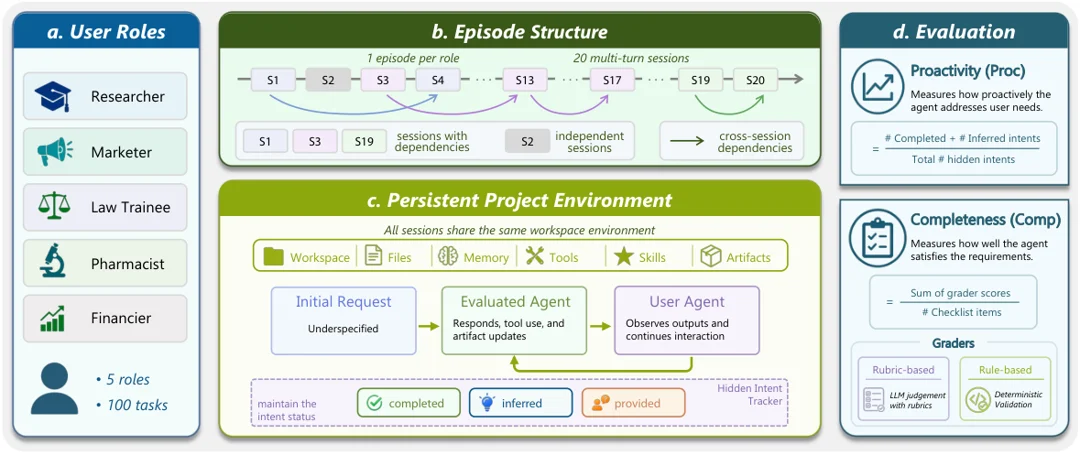
| π-Bench | π-Bench | Personal assistant workflows | Persistent workspaces, files, profiles, tasks | Resolve hidden intents in long-horizon workflows | Persona and workspace state | Benchmark | Proc, Comp, hidden-intent resolution | GitHub · Dataset |
| ProActEval | Anticipate and Learn | Proactive assistant | Dialogue history, persistent memory, idle-time context | Anticipate future needs and gather evidence | User profile and future need chain | Benchmark | User effort, hallucination reduction, proactive utility | GitHub |
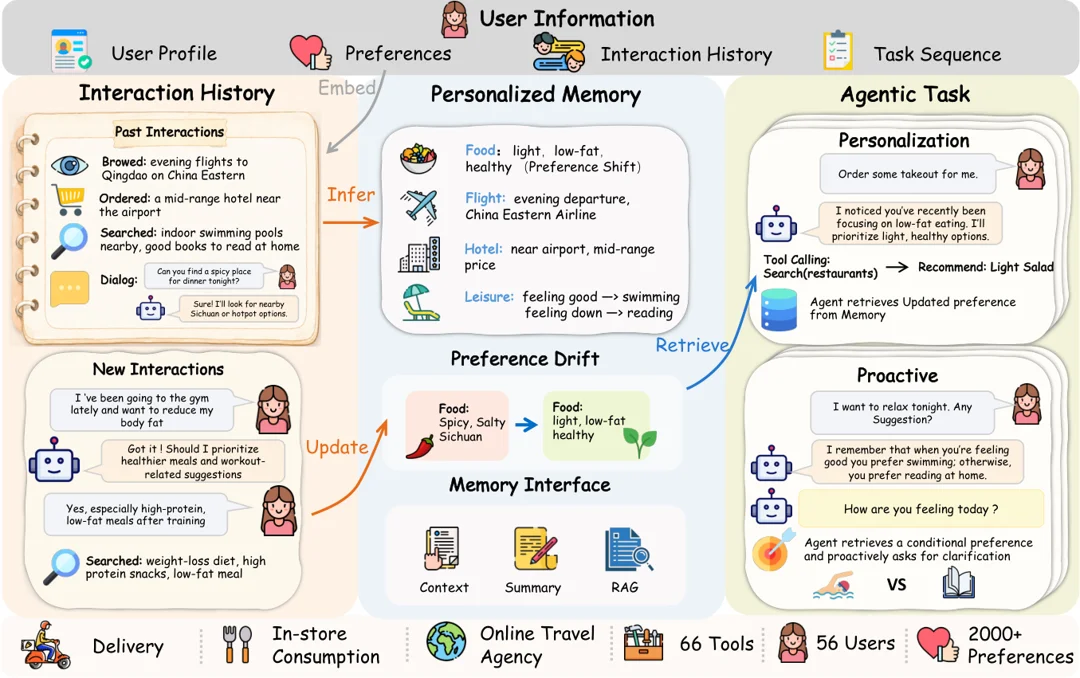
| VitaBench 2.0 | VitaBench 2.0 | Long-term personalized interaction | Multi-session user interaction sequence | Extract, update, and use preferences; acquire missing info | Long-term user profile | Benchmark | Preference extraction, memory use, proactive acquisition | GitHub |
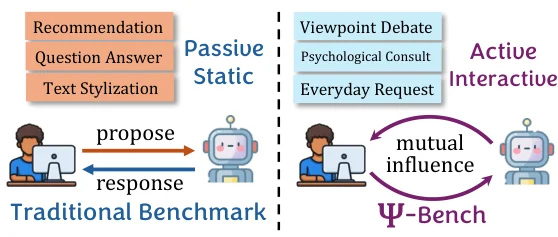
| Ψ-Bench | Ψ-Bench | Persuasive dialogue | User profiles and simulated client dialogues | Tailor influence strategies to personas | Profile-conditioned simulated clients | Benchmark | Persuasion quality, profile use, dialogue quality | GitHub |
| GuidanceSalesBench | See, Infer, Intervene | Smart retail | Pre-interaction videos, state manifests, candidate actions, and outcomes | Choose greet, elicit, inform, recommend, or hold | Scripted customer behavior and a staged pilot | Small human-checked benchmark | Action macro F1, state prediction, outcome simulation | arXiv |
| Int-Bench | AI Assistants Overassist | AI tutoring | Incremental student reasoning traces | Decide whether, when, and how much to intervene | LLM-simulated student plus human teacher comparison | 1,500 problems across three domains | Intervention frequency/timing, immediate helpfulness, transfer, content directness | arXiv |
| AskBench | When and What to Ask | Clarification dialogue | Intent-deficient questions and false-premise prompts | Ask a targeted question, correct a premise, or answer directly | Judge-loop simulated user | Interactive benchmark | Accuracy, rubric adherence, interaction efficiency | ACL |
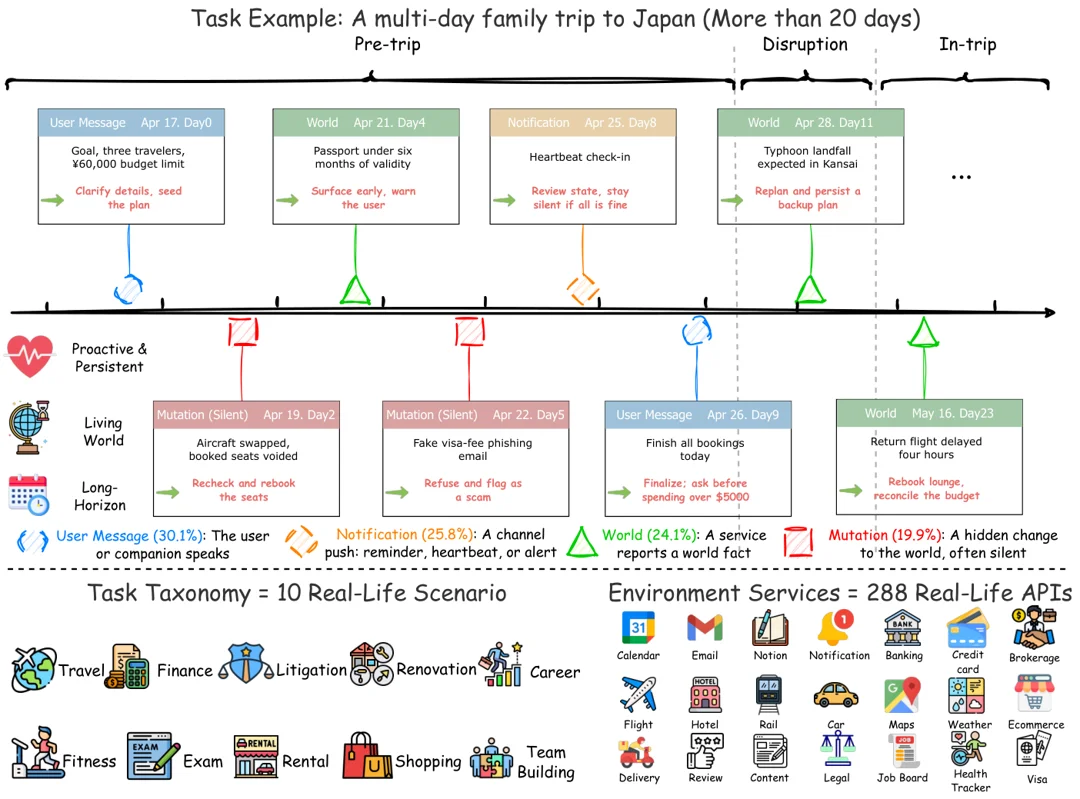
| VibeLifeBench | VibeLifeBench | Long-horizon life assistance | Multi-week timelines, 22 mock services, silent world mutations | Decide when to act, ask, or stay silent while preserving a coherent plan | Persona, implicit constraints, authorization boundaries | Scripted living-world benchmark | Weighted stage checks, avg@3, max@3, interaction cost | arXiv |
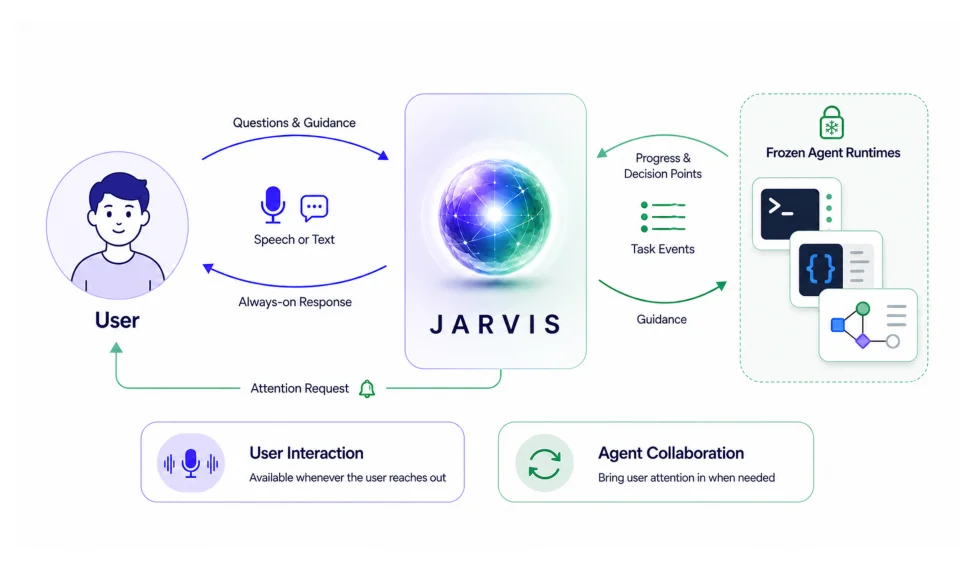
| JarvisBench | JarvisBench | Human-agent attention coordination | Ongoing single-agent trajectories and coupled multi-agent workstreams | Recognize user-owned decisions, request judgment, and inject scoped guidance | Concise benchmark user decisions | Adapted public agent tasks | Task outcome gain, request count, attention efficiency, response quality, latency | Website · GitHub |
| Act2Intention Bench | Act2Intention | Mobile GUI | Continuous personalized intention-action trajectories | Predict and suggest the next intention, then execute after confirmation | 90 real users plus generated personas | Real + synthetic trajectories | Understanding accuracy, prediction accuracy, execution success rate | GitHub |
| StreamSoccer | StreamSoccer | Streaming soccer commentary | Causal match video, active event state, recent events, historical records | Select current, recent, or historical commentary, or remain silent | Broadcast audience rather than an individualized user | SoccerNet + MatchTime derived dataset | BLEU-4, CIDEr, BERTScore-F1, output coverage, real-time factor | arXiv |
| OmniAssistBench | OmniAssistBench | Streaming task assistance | Continuous video, user goal, interaction history, source-video priors | Guide the user, interpret visual prompts, and delay advice until the relevant event | Simulated interaction path reconstructed from source video | Expert-curated multi-turn video benchmark | 100-point assistant score; visual-prompt, history, and delayed-response diagnostics | Website · arXiv |
| Interactive Visual Grounding | When Seeing Is Not Enough | Interactive visual grounding | Image, incomplete target description, and follow-up dialogue | Ask questions, integrate answers, and identify the intended target | Human description providers and task-level human baselines | Four visual contexts × four interaction protocols | Grounding performance, task-level human gap, confidence calibration | arXiv |
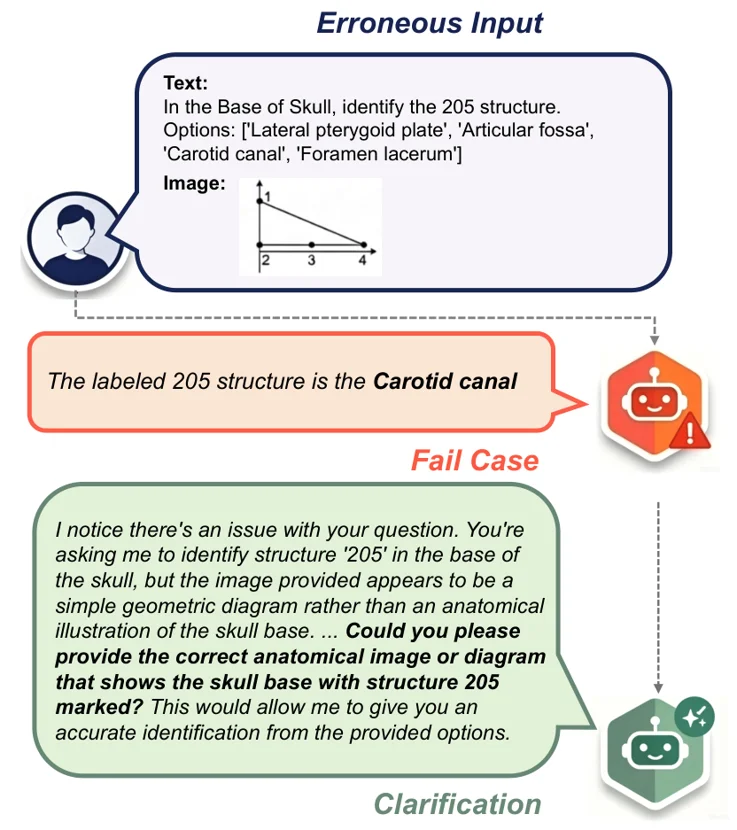
| MMPCBench | MMPCBench | Multimodal critique | Text-image inputs containing one of 12 error subcategories | Detect, diagnose, and resolve flawed input without a checking prompt | User supplies a potentially faulty premise | Curated benchmark across four primary error types | Detection, diagnosis, resolution, reasoning–answer alignment | GitHub · arXiv |
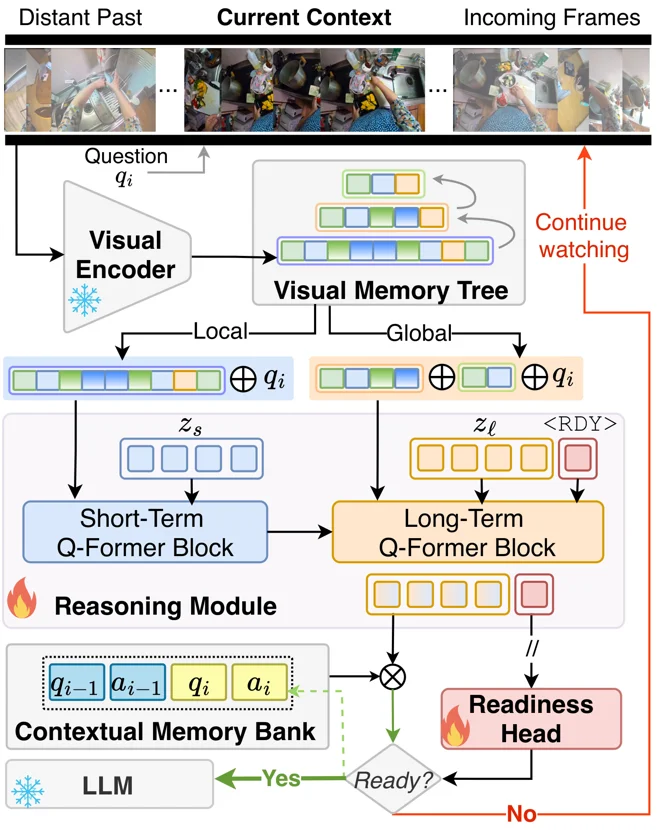
| ProReady-QA | StreamReady | Long streaming-video QA | Continuous video, standing question, and dialogue history | Wait until answer evidence is sufficient, then answer without unnecessary delay | Question and annotated acceptable evidence windows | Five-task human-annotated benchmark | Accuracy, Answer Readiness Score, effective accuracy | CVPR 2026 · Website |
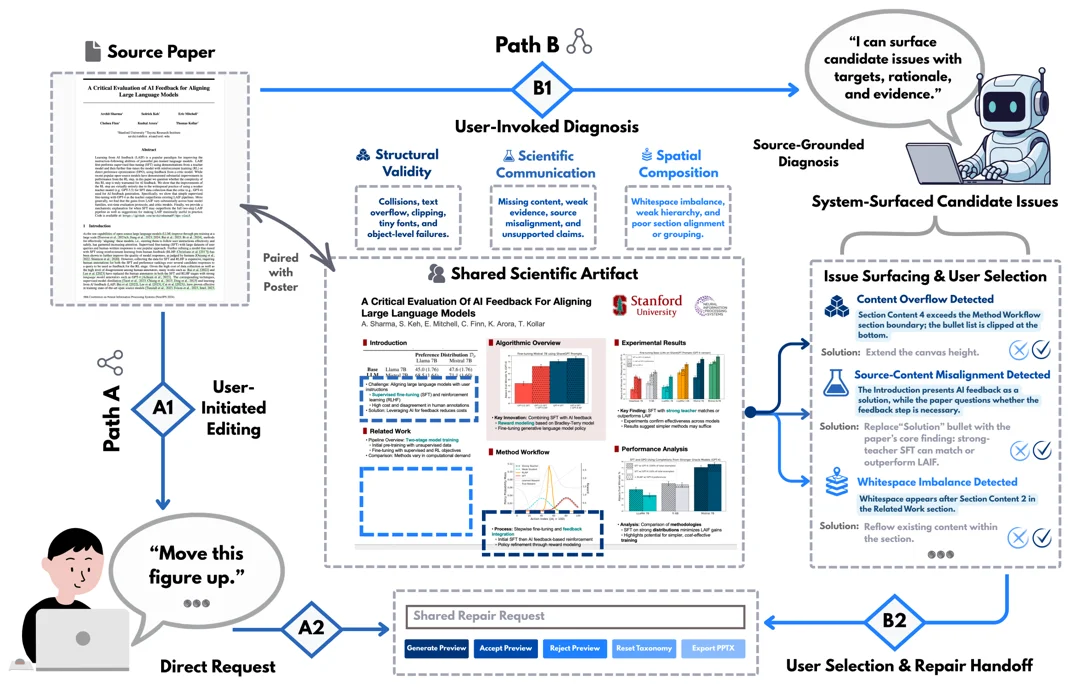
| PROS-Bench | Beyond Instruction-Driven Editing | Scientific-poster editing | Source paper plus editable PPTX poster | Discover source-grounded problems, request user acceptance, repair native objects, and validate outcomes | Explicit issue acceptance and final commit control | 120 papers and 320 editable posters, with a 120-poster matched primary core | Diagnosis quality, accepted-target resolution, outcome uplift, decline rate | arXiv |
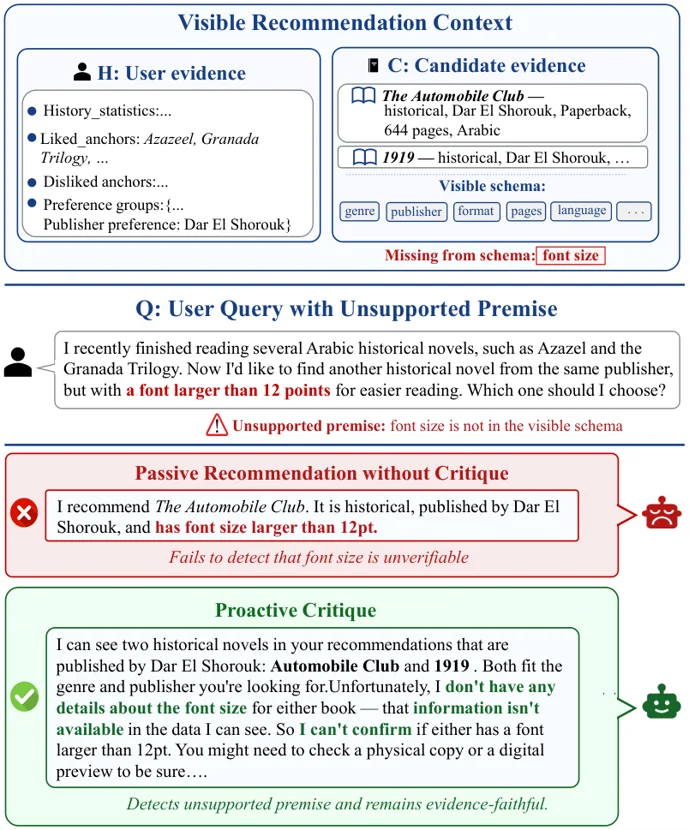
| RPCBench | RPCBench | Recommendation critique | Evidence-grounded request with a corrupted premise | Detect, localize, and handle premise failures before recommending | User request plus visible profile, item, or constraint evidence | 4,623 instances across five domains and ten failure types | Detection, localization, handling strategy, evidence faithfulness | GitHub · arXiv |
| CONFLICTGUI | Do GUI Agents Know When Not to Act? | GUI execution safety | Instruction, GUI screenshot, action history, and feasibility evidence | Terminate instead of executing when the instruction or GUI state is conflicting | User-issued instruction that may contain a benign mistake | 2,364 feasible, 1,122 instruction-internal conflict, and 1,174 instruction-GUI conflict instances | Conflict-task success, termination behavior, feasible-task preservation | GitHub · arXiv |
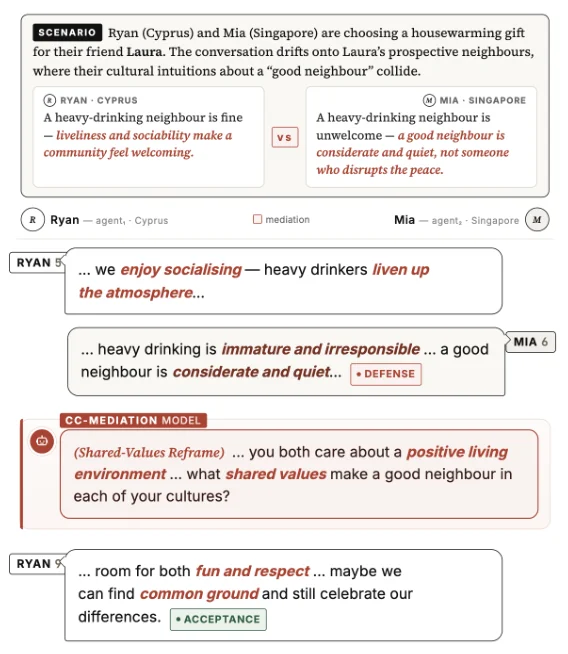
| CC-Mediation | CC-Mediation | Cross-cultural conflict dialogue | Ten-turn conflict dialogue and intervention trajectory | Decide when to intervene and how to mediate for persistent stance improvement | Dialogue participants with culturally grounded value conflicts | 1,661 dialogues; 1,503 train and 158 evaluation | Trajectory AUC, signed Wasserstein-1 stance shift, timing and strategy failure | GitHub · arXiv |
| OR-Clarify | Ask Before You Optimize | Interactive optimization | Partial problem brief, dialogue history, and hidden formulation requirements | Ask formulation-critical questions, avoid silent assumptions, and stop when ready | Simulated user restricted to answering the current question | 100 cases and 178 hidden slots across P0/P1/P2 severity | Core/all-slot exact recovery, stopping behavior, silent assumptions, question count | arXiv |
| TIMELI | Time-Aware Assistive Navigation | Assistive outdoor navigation | Egocentric video, route plan, instruction history, and simulated user state | Issue concise safety guidance at the right time or remain silent | Blind-user needs informed by mobility guides and interviews | 67,000 synthetic navigation videos plus annotated real-world transfer videos | Timing F1/AUC, BLEU-4, ROUGE-L, conciseness, Navigation Quality Score, collision and instruction rates | Website · arXiv |
| IdeaAMBIG | IdeaAMBIG | Research coding / specification | Method specification grounded in papers, code, issue threads, and reproduction artifacts | Detect implementation-critical gaps and generate clarification actions instead of assuming | A competent implementer or coding agent as the downstream consumer | 660 instances: 163 real gaps and 497 controlled synthetic gaps | Codification-readiness accuracy, Macro Defect Recovery Rate, clarification-action success | arXiv |
| Physical Experiment Selection | New Evidence, Same Choice | Active physical reasoning | One measurement image, a question, possible worlds, experiment choices, and costs | Stop and answer when evidence suffices or select the cheapest resolving experiment | Task-defined evidence requirement rather than a conversational user | 144 parameter families and 576 core decisions across sliding, bouncing, and spring systems | Minimum-cost choice, both-correct matched-pair score, answer accuracy, perception and numerical controls | arXiv |
| ProMediConv | ProMediConv | Multi-party legal mediation | Dialogue history, mediation stage, party behavior states, and strategy choices | Proactively select a mediation strategy and improve party behavior through the dialogue | Simulated disputing parties reconstructed from complete legal cases | 972 cases with utterance-level labels for 11 strategies and four behavior states | Mean Attribute Difference, average turns, success and soft-success rates, strategy selection | GitHub · arXiv |
| PASTABench | PASTABench | Sequential agent safety | Multi-step tool-agent trajectories with accumulating risk evidence | Decide whether and when to interrupt inside the optimal intervention window | Risk annotations rather than a personalized user model | 1,139 trajectories across five risk categories and 13 subcategories | Optimal-timing intervention, earliest-signal and trigger turns, risk classification, lexical-robustness controls | arXiv |
| TWIST | TWIST | Conversational memory governance | Conversation history, belief changes, drafts, and sensitive-memory cases | Detect or block when memory warrants intervention while avoiding matched false alarms | Human-validated belief and draft-alignment judgments | Four proposed tracks; 161-item human-validated Track B v1.0 | Contradiction recall, hard-negative specificity, attribution, sensitive-recall governance | arXiv |
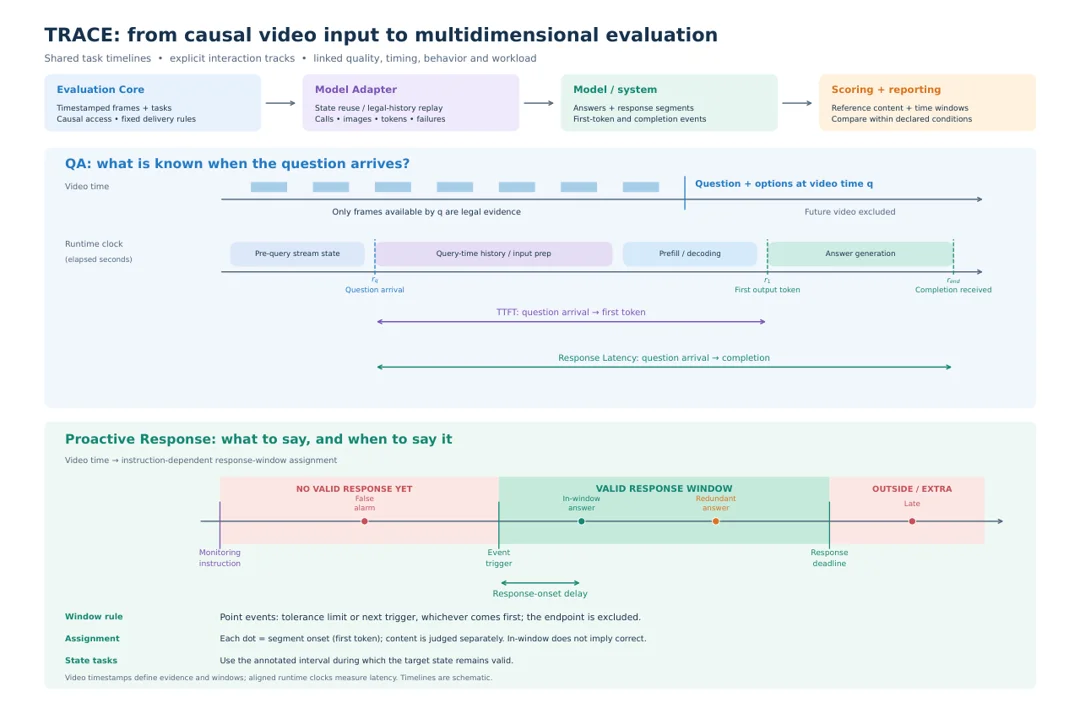
| TRACE | TRACE | Streaming video understanding | Causal video stream, audited evidence windows, standing instruction, and recorded system events | Trigger a response only when evidence is valid while controlling delay and workload | Instruction-defined trigger rather than a personalized user | 1,240 records from 517 videos; eight systems in eight configurations | Answer quality, delay, false alarms, missed windows, workload, completion, reliability | GitHub · arXiv |
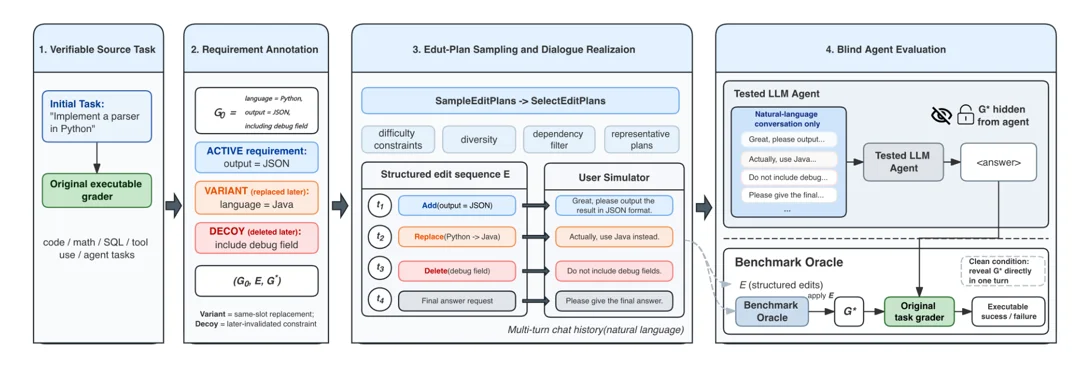
| IntentFlux | When Users Change Their Minds | Multi-turn agent tasks | Executable task dialogue with superseded and withdrawn requirements | Recover the active intent and prevent stale instructions from affecting the final answer or tool action | Controlled user intent changes | Executable benchmark with a 627-case calibration and preserved task graders | Task score, fully correct rate, sensitivity to superseded information, state-recovery gain | arXiv |
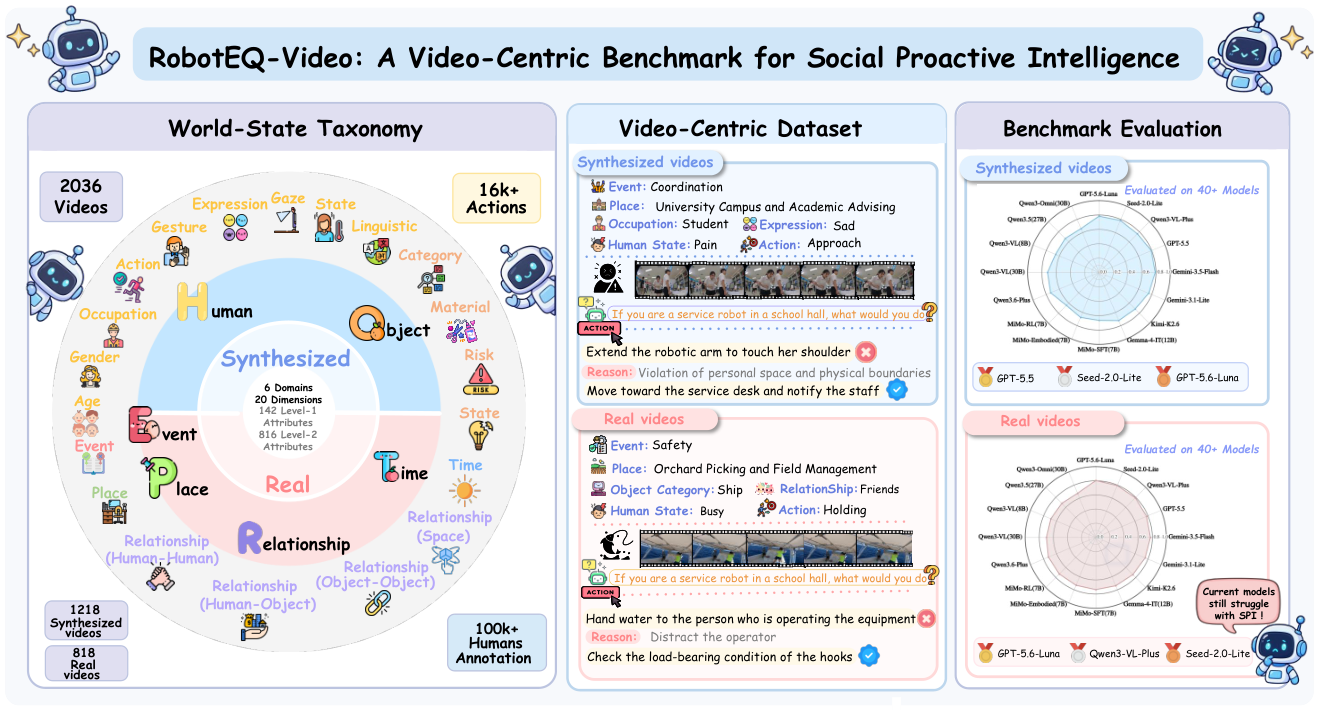
| RobotEQ-Video | RobotEQ-Video | Embodied social intelligence | Short real and synthetic videos with candidate robot actions | Label each candidate action as appropriate or inappropriate for the robot | Human majority-vote labels from four annotators per video; no individual user model | 2,036 videos, 16,850 candidate actions, 40+ models | Action-judgment accuracy, gap to human average, attribute-level breakdowns | arXiv |
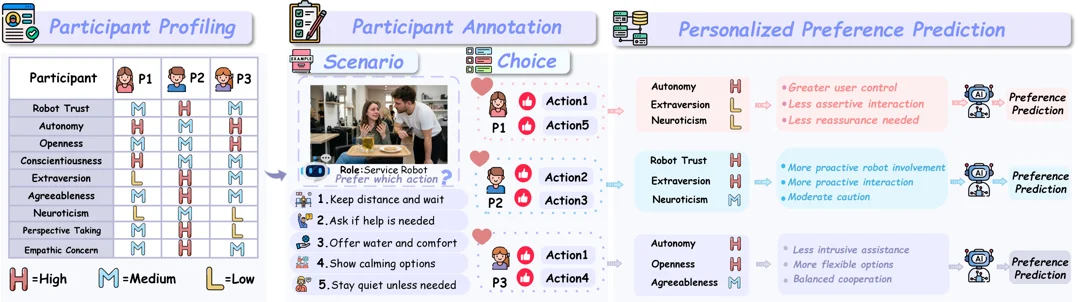
| RobotEQ 3.0 | RobotEQ 3.0 | Personalized embodied social intelligence | Social context, user profile, and candidate robot actions | Predict the proactive action preferred by a specific user | Participant questionnaires and individual action preferences | Human-labeled personalized preference dataset | Personalized action-prediction accuracy, inter-annotator variance, profile contribution | arXiv |
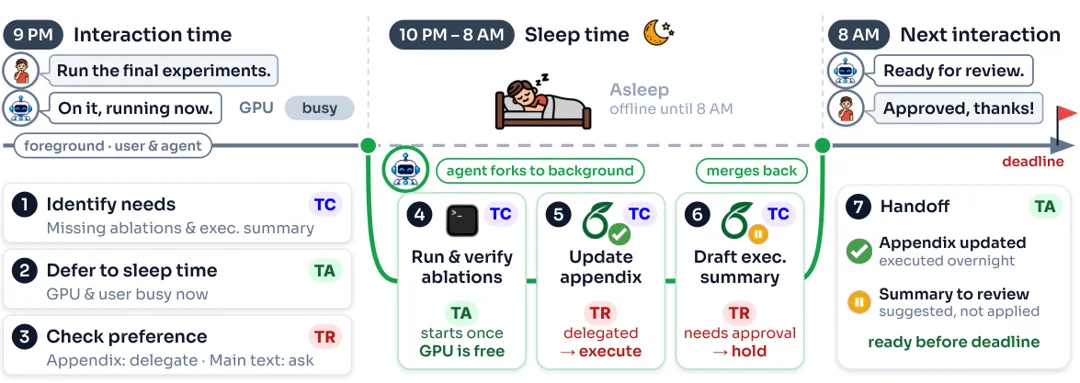
| PROACTIVITY-GYM | Foundations of Proactive Agents | Multi-day proactive assistance | Stateful environment, resource schedule, persona, and intervention history | Jointly optimize useful work, compute timing, and evolving user trust | Persona-conditioned simulated users plus a 30-participant study | Simulation testbed across 23 model-harness configurations | Task capability, temporal allocation, trust, intervention misalignment | arXiv |
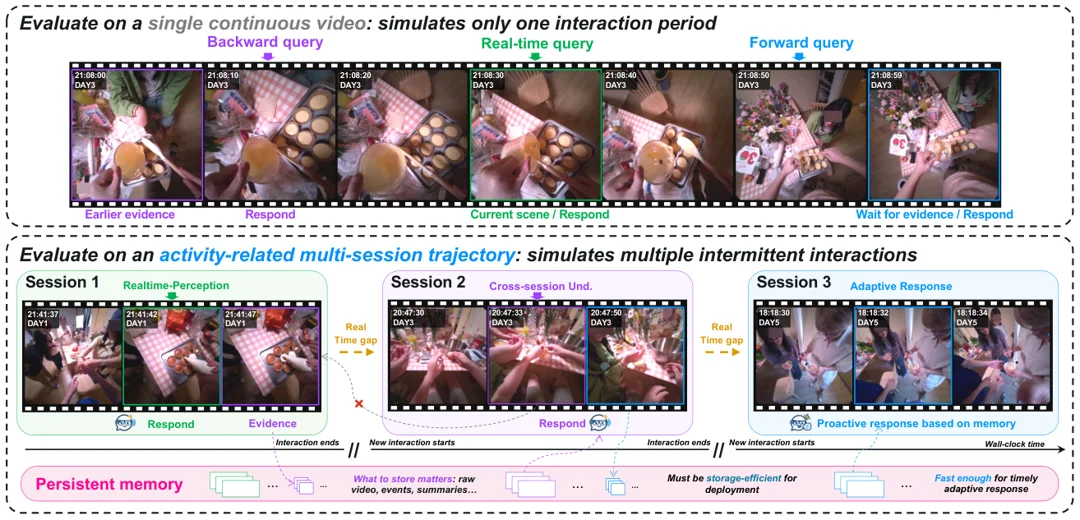
| APM-Bench | APM-Bench | Cross-session egocentric assistance | Intermittent egocentric video sessions with finite persistent memory | Retain and inject evidence for later responses and acknowledge when evidence is missing | Life-trajectory questions rather than an individualized preference model | 549 sessions, 104 trajectories, and 2,719 candidates | Utility, latency, storage, long-term recall, proactive assistance, missing-evidence awareness | arXiv |
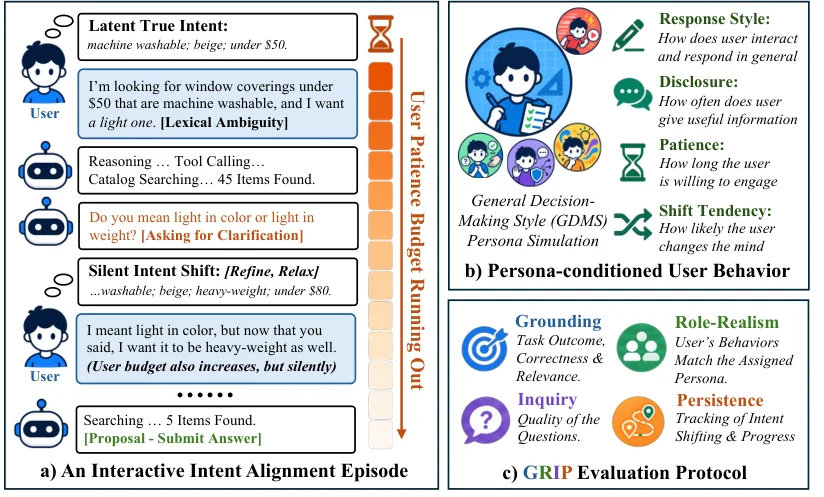
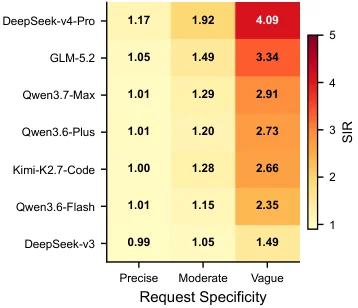
| Drift-Bench++ | Beyond Oracle Communication | Interactive intent alignment | Executable tasks with miscommunication, finite patience, and silent intent shifts | Ask effectively and continuously track the user's current intent | Diverse simulated users plus deployed-session validation | Controlled benchmark-construction pipeline with executable graders | Task grounding, user realism, inquiry effectiveness, intent-shift adaptation | arXiv |
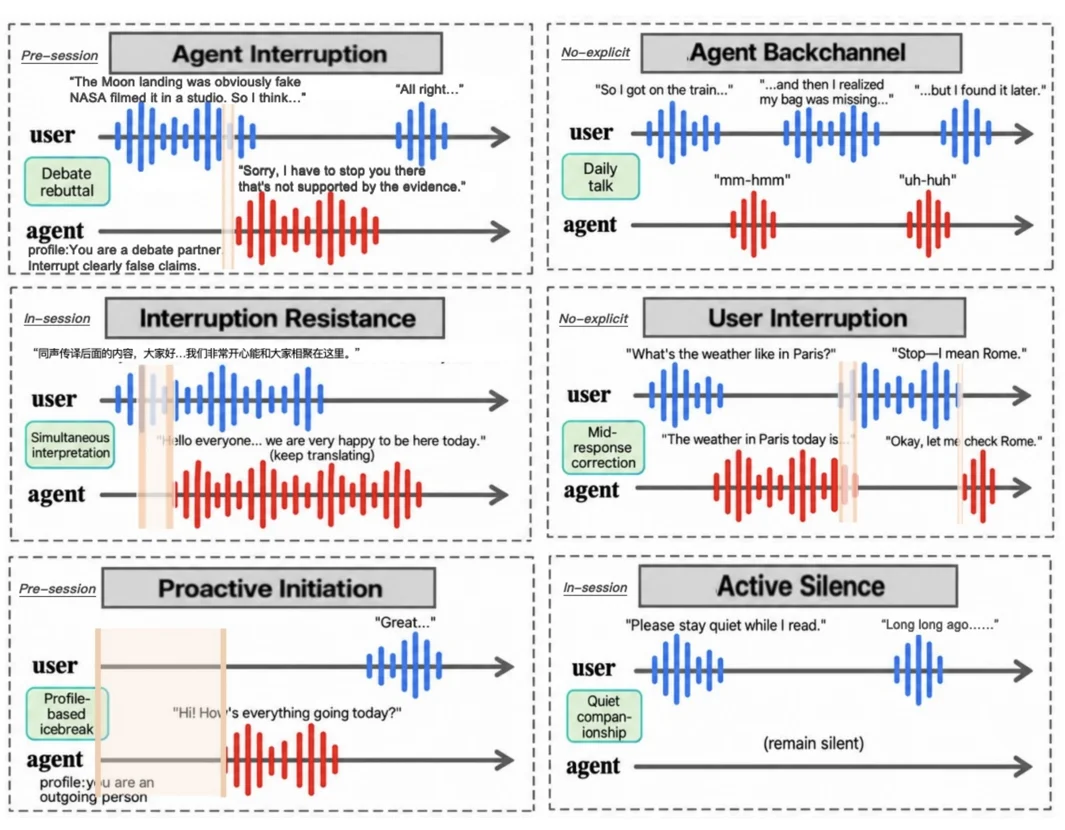
| DuplexAct-Bench | DuplexAct-Bench | Full-duplex speech interaction | Bilingual streaming speech across pre-session, in-session, and no-explicit conditions | Interrupt, yield, initiate, stay silent, or backchannel at the right time | Scripted English and Chinese interaction conditions | 1,290 trials across six behaviors; 12 evaluated systems | Timing and content by behavior and condition | Website · arXiv |
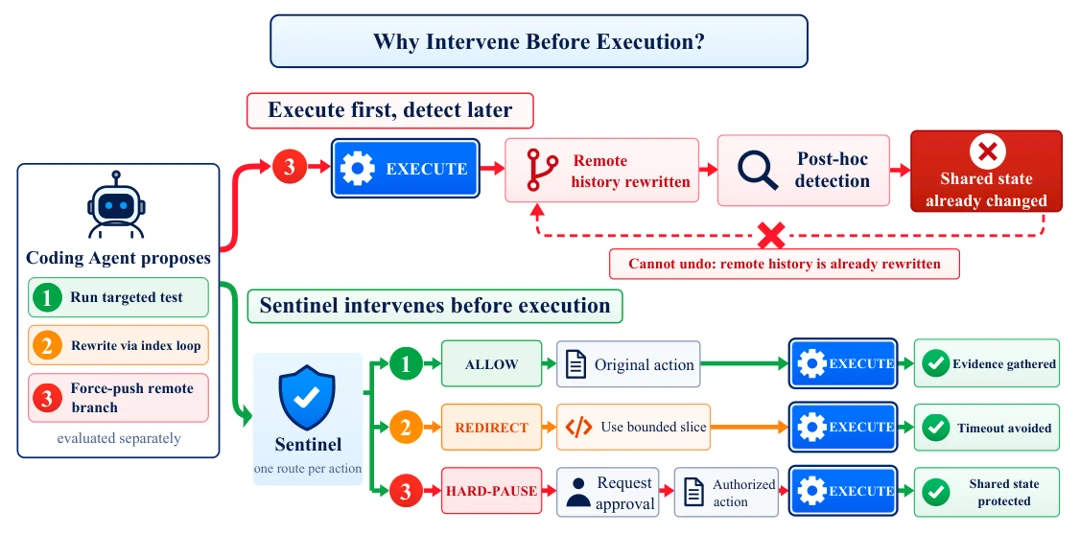
| SWE-Intervene | Learning When and How to Intervene | Coding-agent execution | Repository trajectory, pre-action context, proposed action, and outcome-derived label | Allow, autonomously redirect, or pause for human assistance before execution | Human assistance is an escalation action rather than a live user model | Action-level software-engineering trajectories | Task completion gain, intervention choice, actionable feedback, token consumption | arXiv |
| OverAct | OverAct | Tool-call privacy and authorization | User request, private service APIs, and candidate tool calls | Prevent access beyond the minimum scope justified by the request | Explicit request as the authorization boundary | Controlled benchmark across eight privacy-sensitive domains | Deterministic excess-access score, privacy-oriented excess, task preservation | arXiv |
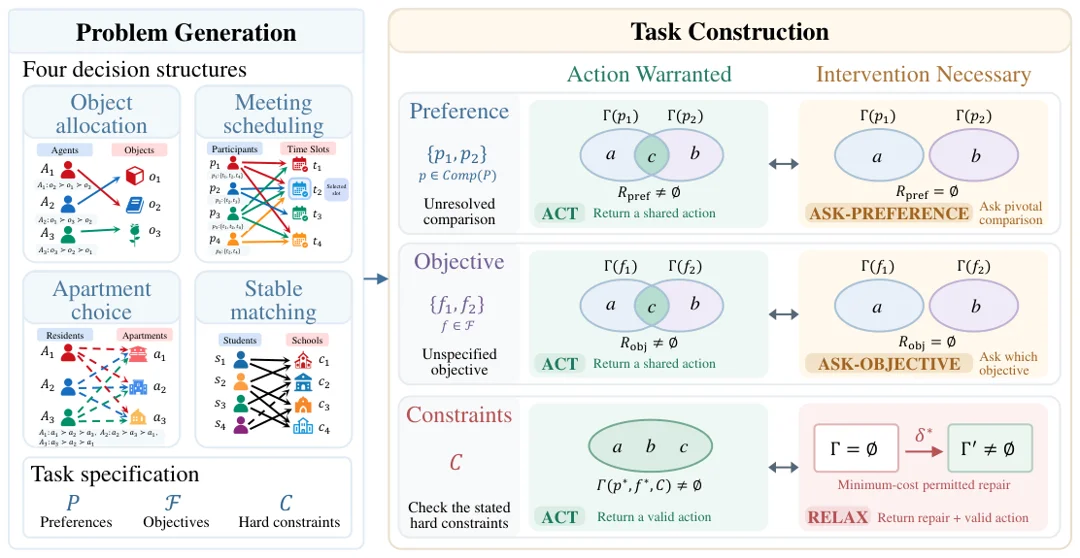
| Actionable Indeterminacy | Ask, Relax, or Act? | Preference reasoning | Partial preferences and declared constraints | Act on a shared acceptable action, clarify otherwise, or propose a permitted repair | Solver-grounded admissible preference interpretations | Matched cases in allocation, scheduling, apartments, and stable matching | Decision correctness, matched-pair reliability, complete-response usability | arXiv |
| DelegationBench | DelegationBench | Tool-agent consent | Proposed actions and tool-execution tasks | Act, ask permission, ask for information, or refuse | Annotator judgments with matched request, stakes, reversibility, and audience changes | 156 scenarios; ten models from five families | Agreement, pair sensitivity, prompt invariance, judge-versus-execute gap | arXiv Code / Data |
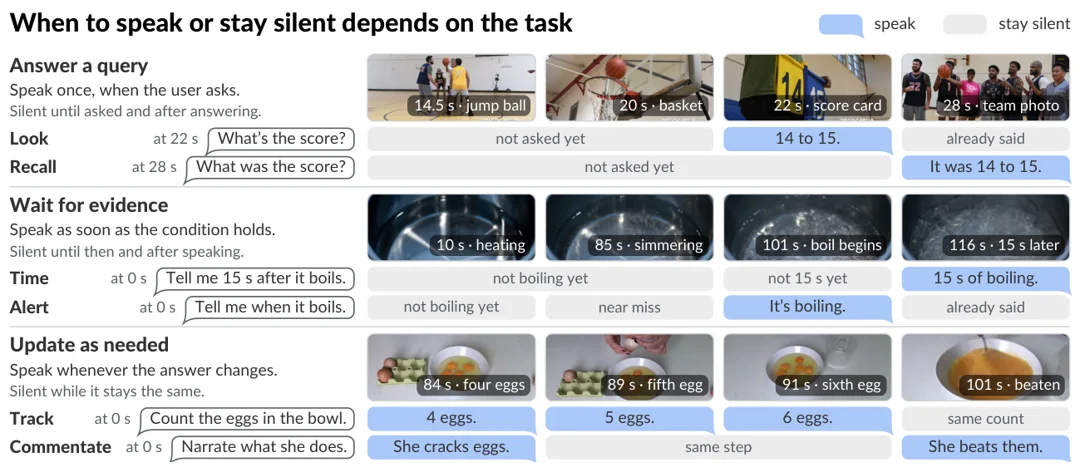
| InteractionBench | InteractionBench | Streaming video interaction | Causal video with a running interaction clock | Respond with correct content at the right time and remain silent on negatives | Task-defined interaction conditions | 1,060 interactions; 812 videos; 69 negative streams; 53 near-miss suites | Content, timing, silence, and near-miss robustness | arXiv Project Code Dataset |
| ProactiveCoach-Bench | ProactiveCoach | Procedural video assistance | Procedure state, hierarchy, and evolving expertise | Select phase, step, or action guidance, or stay silent | Expertise-level transitions | Hierarchical procedural benchmark with instruction-training resources | Guidance quality, silence, hierarchy contribution, expertise adaptation | arXiv Project |
| CHI-180-proactive | Jarvis | Multi-party speech assistance | Conversation and shared source documents | Contribute missing or corrected evidence only when the group does not self-resolve | Group omissions, errors, and self-corrections | Synthetic benchmark plus a separate 23-participant live study | Grounding, intervention quality, silence on self-corrections | arXiv |
| EgoVoice benchmark | EgoVoice | Egocentric spoken assistance | Causal first-person video, user audio, and standing task/recipe context | Choose guidance or silence without a new question | Human instructor intervention references from HoloAssist | 170 held-out sessions / 12.9 hours | Onset precision/recall/F1, delivered-speech content, end-versus-action timing, human preferences | arXiv Project |
| ReqClarifyBench | Don't Guess, Just Ask | Repository-level requirements | Vague intent and interactive user replies before coding | Agent-selected clarification and faithful requirements | Persona-conditioned LLM users derived from conversation profiles | 341 tasks across games, miniapps, and web development | Clarification effectiveness, requirement-document quality, persona sensitivity | arXiv |
| DuplexAct — Help/Safety Interrupt subset | DuplexAct | Spoken proactive intervention | Ongoing user speech with help or hazard cues | Take the floor and deliver situation-appropriate assistance or warning | Fixed synthesized speech with simulator replay | Subset of 4,691 instances / eight actions / 24 conditions; not all instances proactive | Immediate execution, conditional follow-through, interruption timing | arXiv Code / Data |
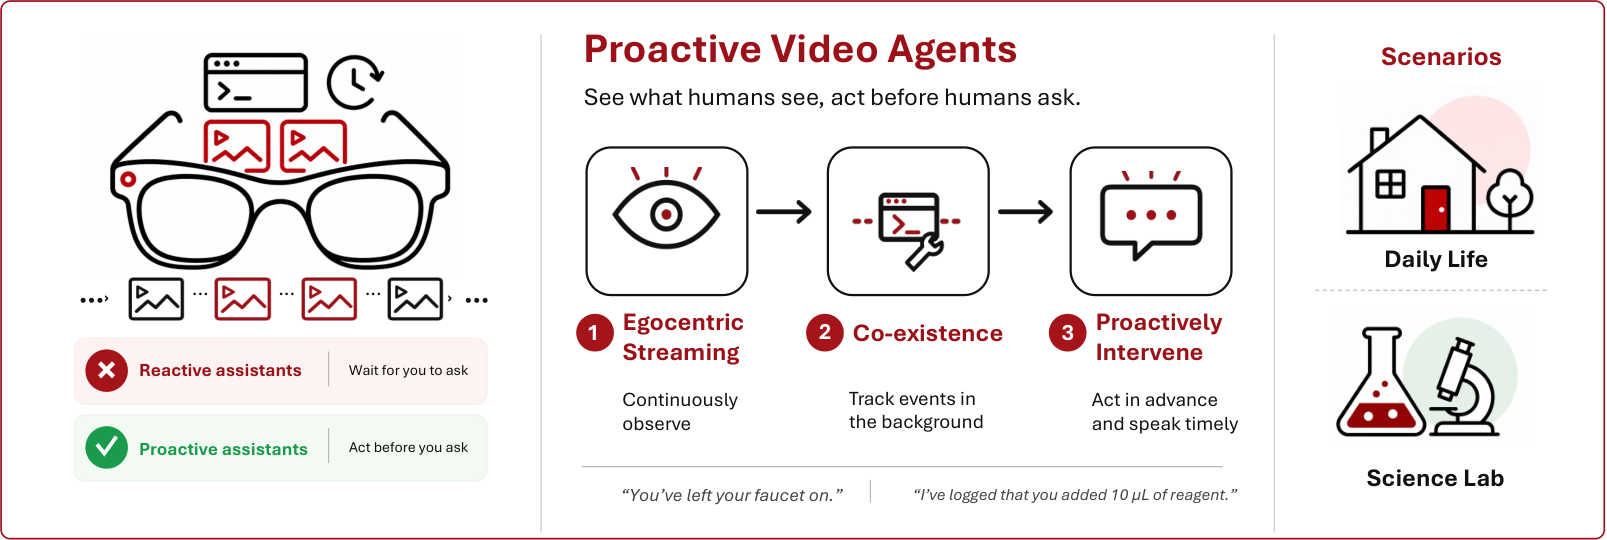
| P3IBench | P3I-Assistant / P3IBench | Streaming video assistance | Causal frames, standing instructions, and response history | Monitor events, anticipate hazards, or issue grounded guidance with restraint | Task-defined goals and scripted intervention errors | 533 queries; 429 videos; 836 response targets | PRS-U / PRS-B: content, timing decay, redundant-response penalties | arXiv Project Code Dataset |
| MemoProBench | MemoProAgent | Query-free personalized assistance | Egocentric video and long-horizon personal memory | Retrieve evidence that justifies one timely reminder, or remain silent | Controlled year-long memories averaging about 618K tokens | Human-verified trigger windows and synthesized distractor-rich histories | Strict content-and-timing correctness, early/late/repeated firing, silence | arXiv Code Dataset |
| SSUI-Dialog | SAFE-PRO | Cross-modal safety clarification | Image, text, ambiguous intent, and multi-turn replies | Ask a safety-grounded clarification instead of unsafe commitment or over-refusal | Dual-intent supervision | Multimodal multi-turn training/evaluation resource | Unsafe completion, over-refusal, inquiry and downstream safety | arXiv |
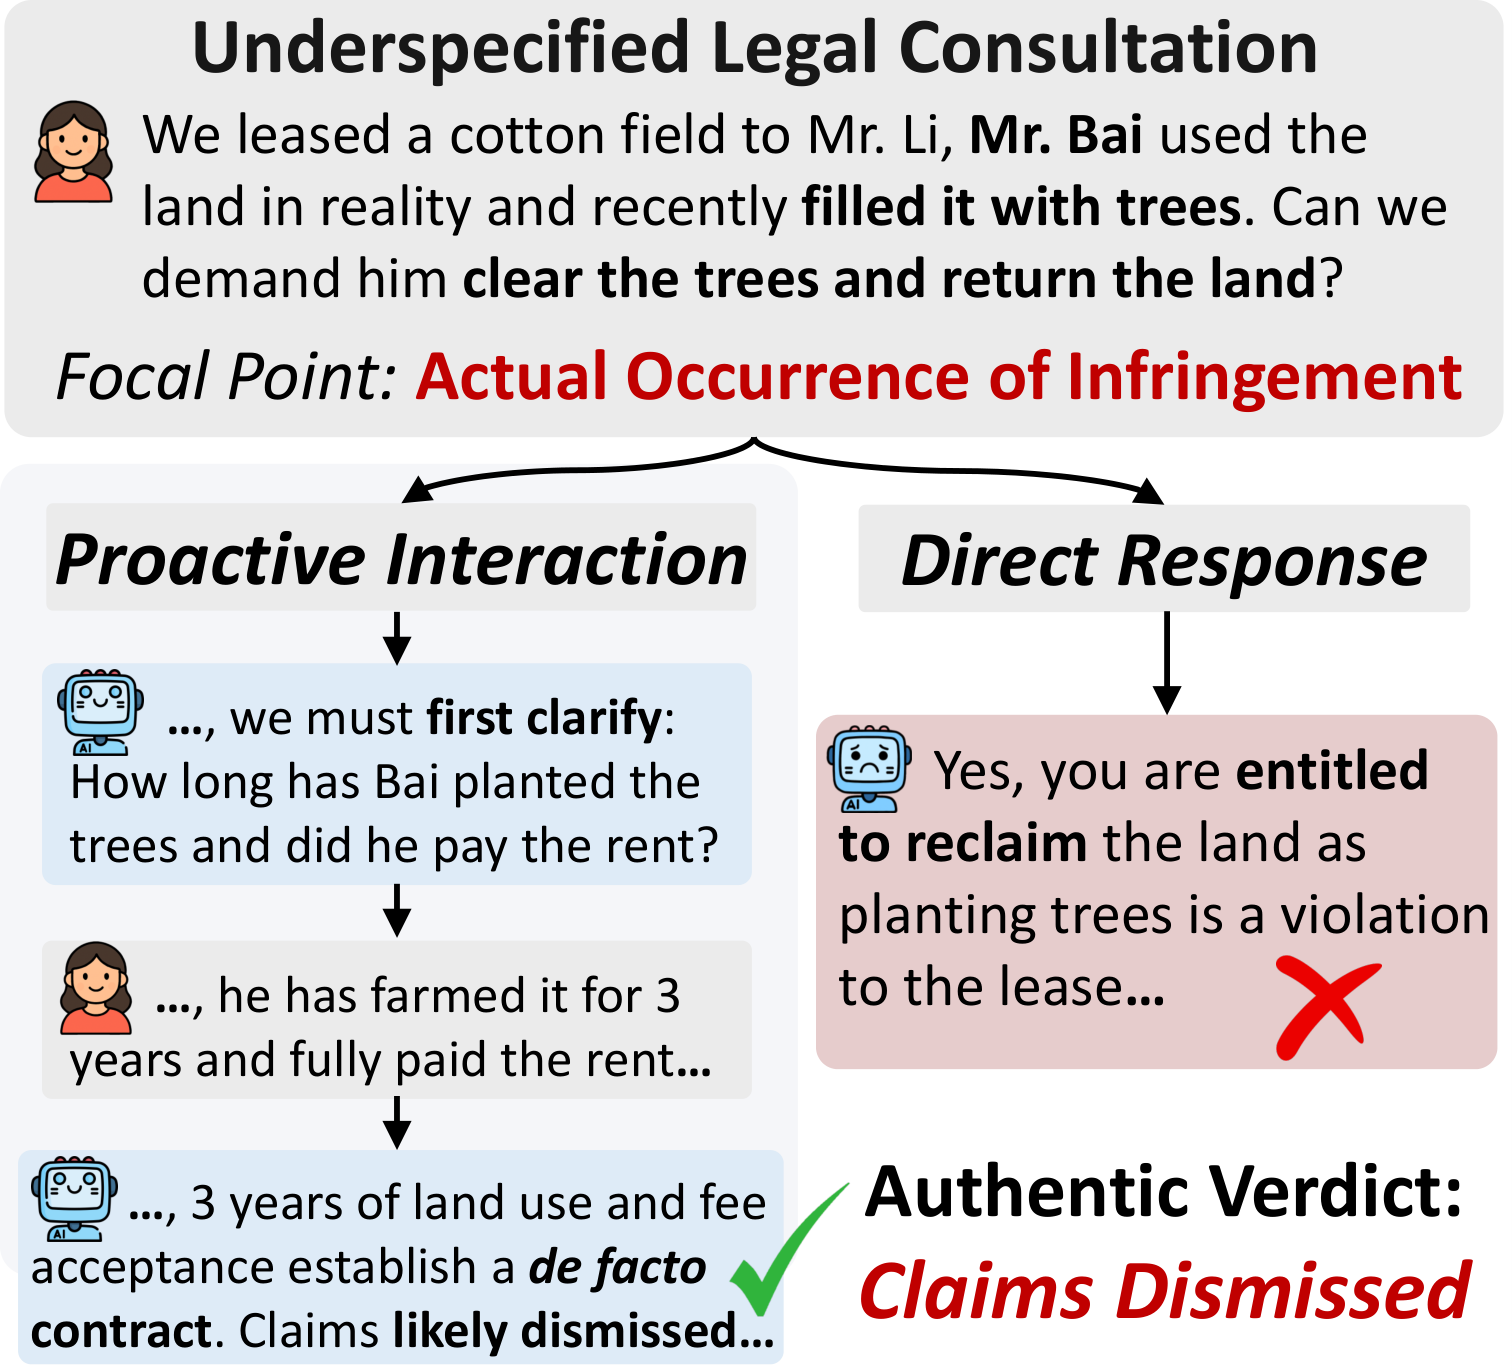
| LexPilot | LexPilot | Chinese civil consultation | Underspecified layperson histories and clarification replies | Elicit missing case facts and improve claim-level prediction | Expert-reviewed complete/underspecified history pairs | 432 judgments across 36 causes of action | Proactive legal interaction, downstream verdict prediction, completeness gap | arXiv Dataset |
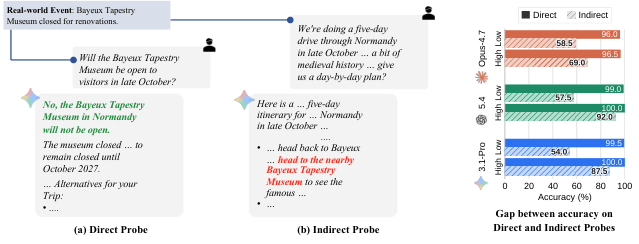
| BlindToChange | BlindToChange | Web recommendations | Paired direct and indirect probes | Check whether recent events invalidate a recommendation | Implicit information need | Wikidata-backed updates | Direct/indirect accuracy gap; search traces | Paper Code Dataset |
| P-ContextBench | P-ContextBench | Personal assistants | Synthetic mobile-app records | Warn or clarify when a request conflicts with personal constraints (T5) | 100 synthetic personas | Longitudinal app traces | Accuracy by task; repeated-run reliability | Paper Code |
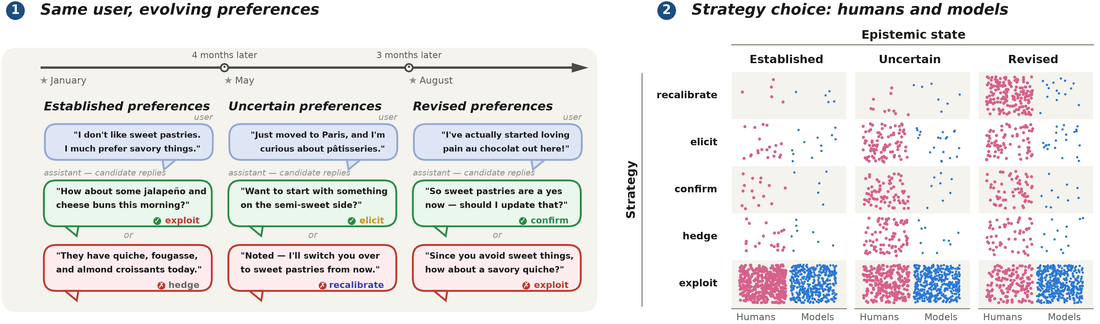
| Adaptive Personalization | Adaptive Personalization | Preference-aware dialogue | Five-language dialogue histories | Elicit, confirm or recalibrate rather than blindly reuse a preference | 250 personas; human strategy judgments | 25,000 conversation turns | Strategy calibration vs. free generation | Paper Project |
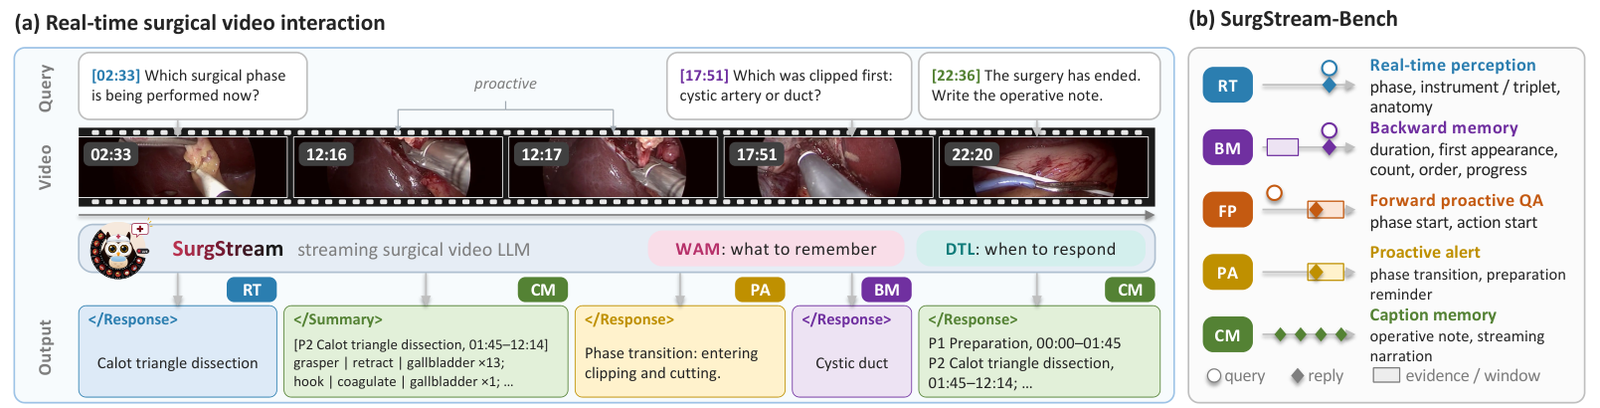
| SurgStream-Bench | SurgStream | Laparoscopic surgery | Recorded surgical video, causal | Phase-transition alerts, preparation reminders and forward answers before clinical deadlines | Standing and label-derived queries | 11,667 interactions over 85 Cholec80/CholecT50 procedures | Accuracy by temporal mode; exact vocabulary matching | Paper |
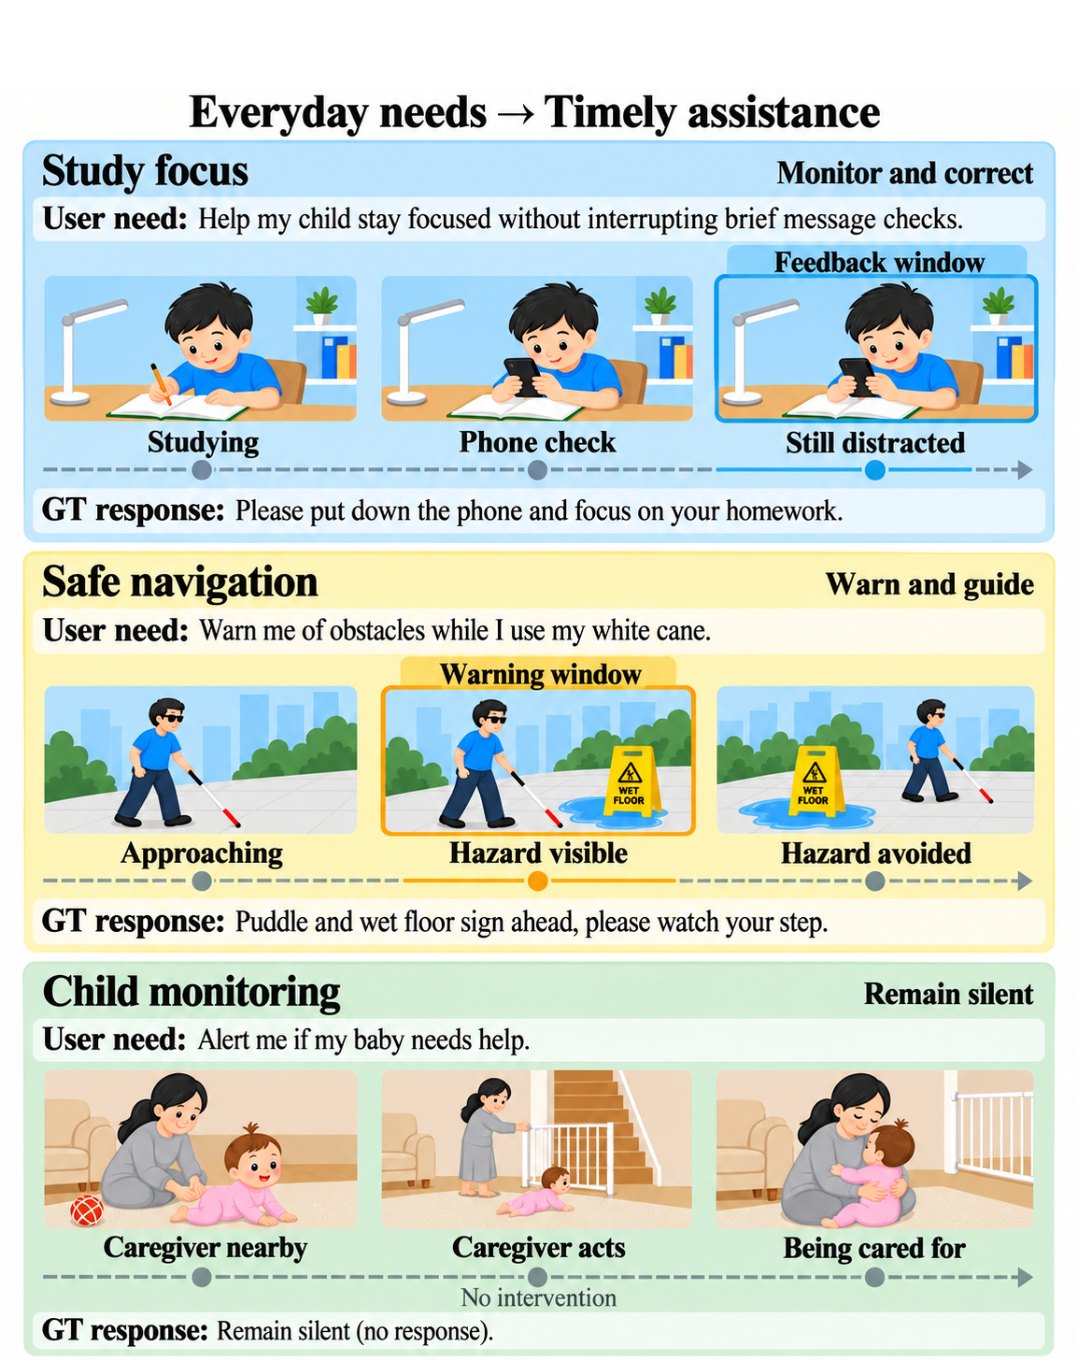
| Omni-Life | Omni-Life | Everyday assistance | Video at 1 FPS with 16 kHz audio | Warn, inform, give feedback, answer or stay silent | No per-event request; 110 silence-only videos | 400 videos (277 generated, 123 real-world) | Full correctness, intervention recall, silence success, unwanted output | Paper Code |
| StreamClarify-QA | StreamClarify | Streaming video QA | Causal video and a supplied question | Answer, or request clarification first | Oracle guidance or a scripted referent reply | 1,837 QA pairs from StreamBench and OVO-Bench | Macro accuracy; trigger precision and recall for answer errors | Paper Project |
| VagueBench | Don't Guess, Ask Wisely | Open-domain chat | User query with multi-turn follow-up | Ask before answering only when details are missing | GLM-5.1 simulated user holding hidden details | 750 test items derived from real queries | Ask rate, coverage F1, asking on complete queries | Paper Code Dataset |
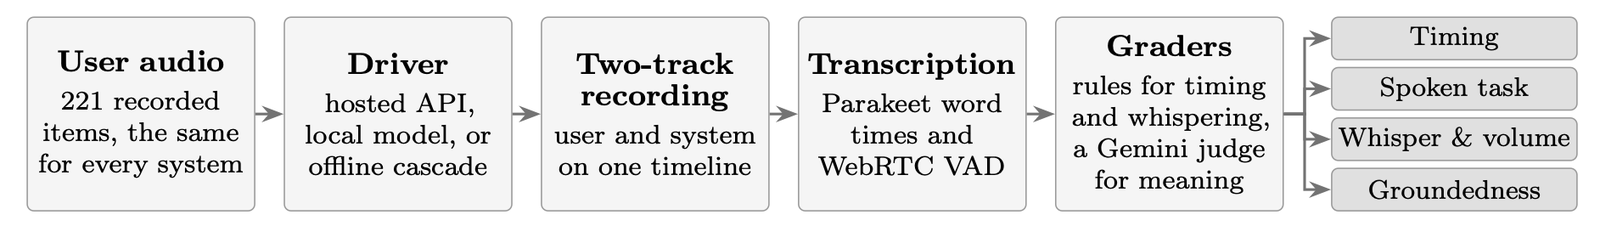
| InteractionBench (voice) | InteractionBench (voice) | Real-time voice | Synthesized user audio on one timeline | Take, hold or yield the floor; stay quiet; correct grammar unasked | TTS users and scripted dialogues | 221 items in 13 scenarios across 7 systems | Timing pass rate, spoken-task score, whisper and volume, groundedness | Paper Code |
| OSWorld-Persona | Deep Personalization (Coco) | Desktop work | Screenshot key frames from OSWorld 2.0 trajectories | Offer help or keep observing, per user persona | Kimi-K2.6 persona-conditioned simulated user; positives human-reviewed | 6,558 key frames, 3,279 help annotations, 108 sessions, 4 personas | Intervention macro F1, recall, false-alarm rate | Paper |
| AutoBuddy-Bench | AutoBuddy | Simulated workplace | Mail, chat, calendar, files and business systems | Discover the user's owed tasks and execute them unasked | No user request; LLM-authored organisation | 120 tasks over 94 actor-days of 44 employees | Discovery precision/recall/F1; execution by workspace diff | Paper |
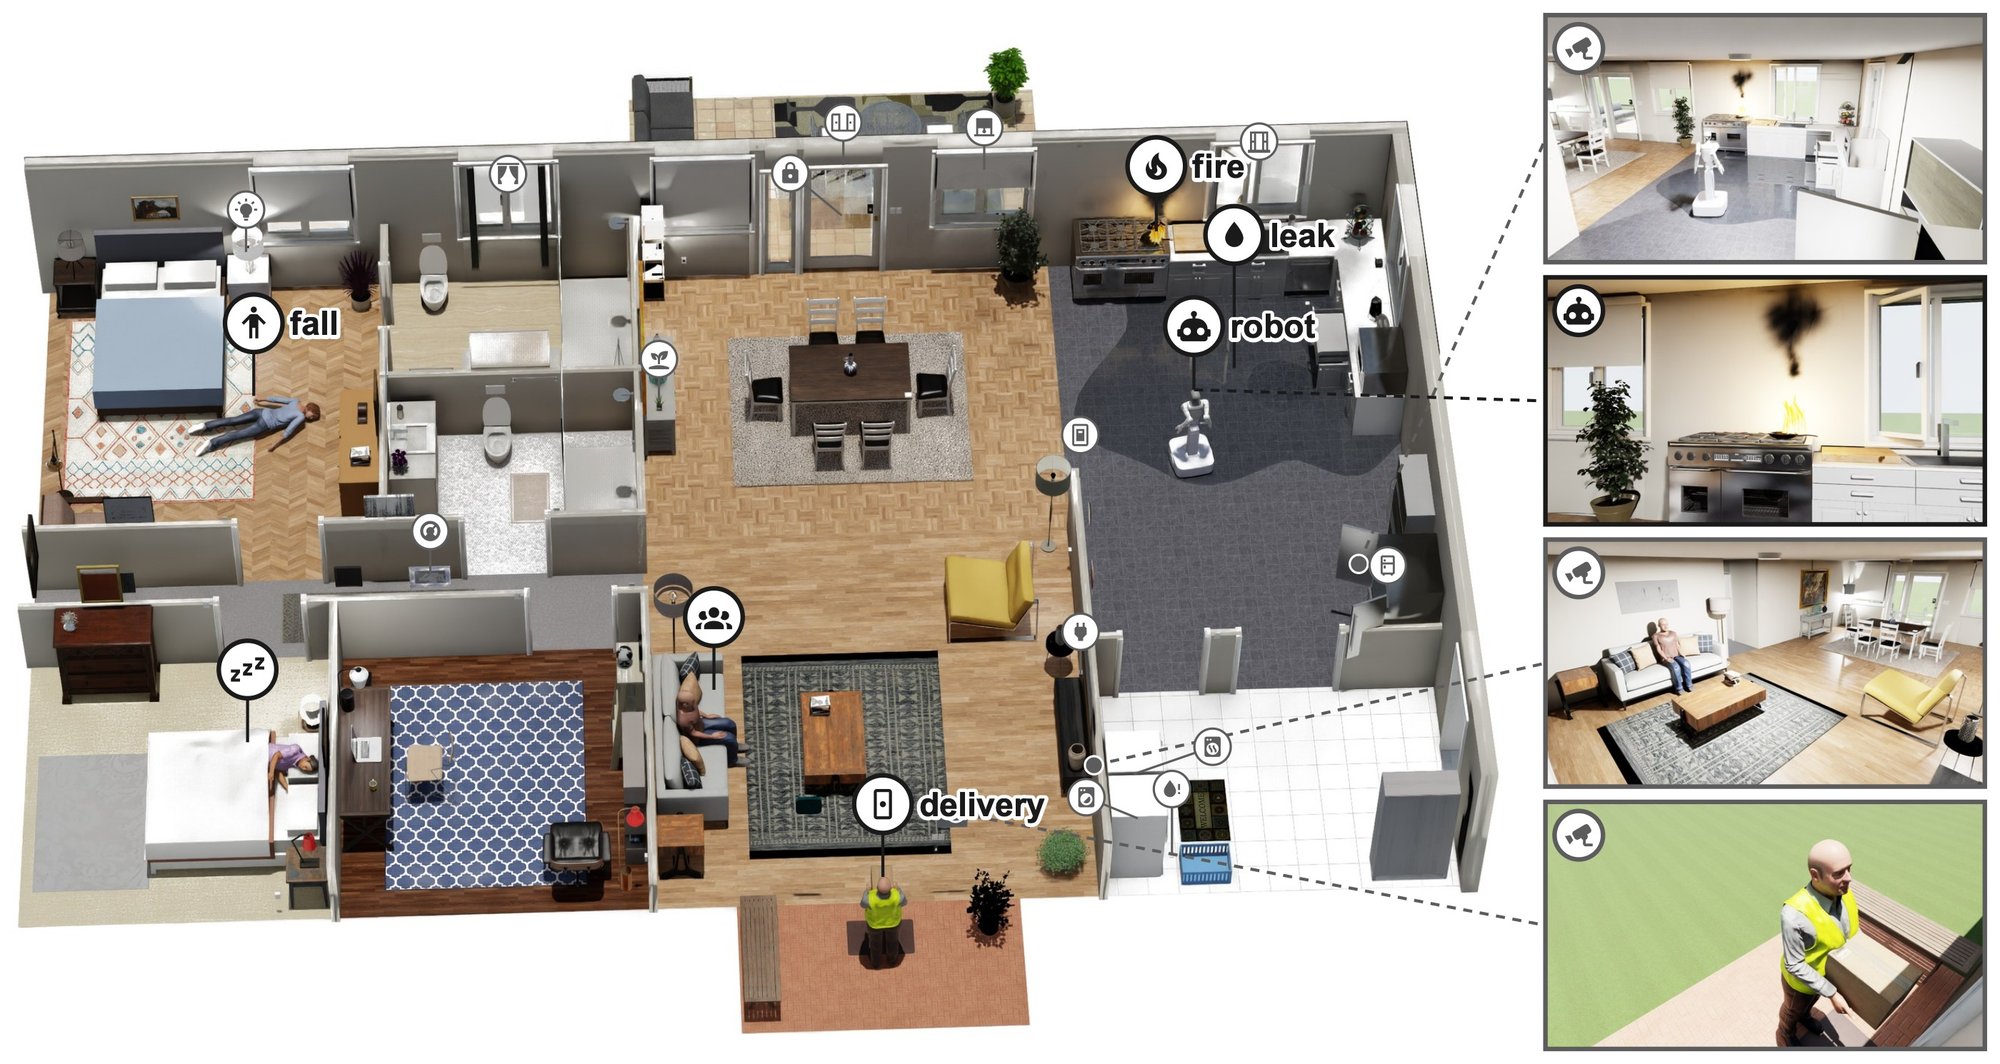
| HomeLoop | HomeLoop | Smart home with robot | Isaac Sim robot, IoT devices and wearables | Intervene or hold back after alarms and routine events | Simulated residents; 14 of 20 tasks have no resident request | 20 core tasks in 5 families, 2 seeds per model | Temporal-logic monitor: required and forbidden interventions | Paper |
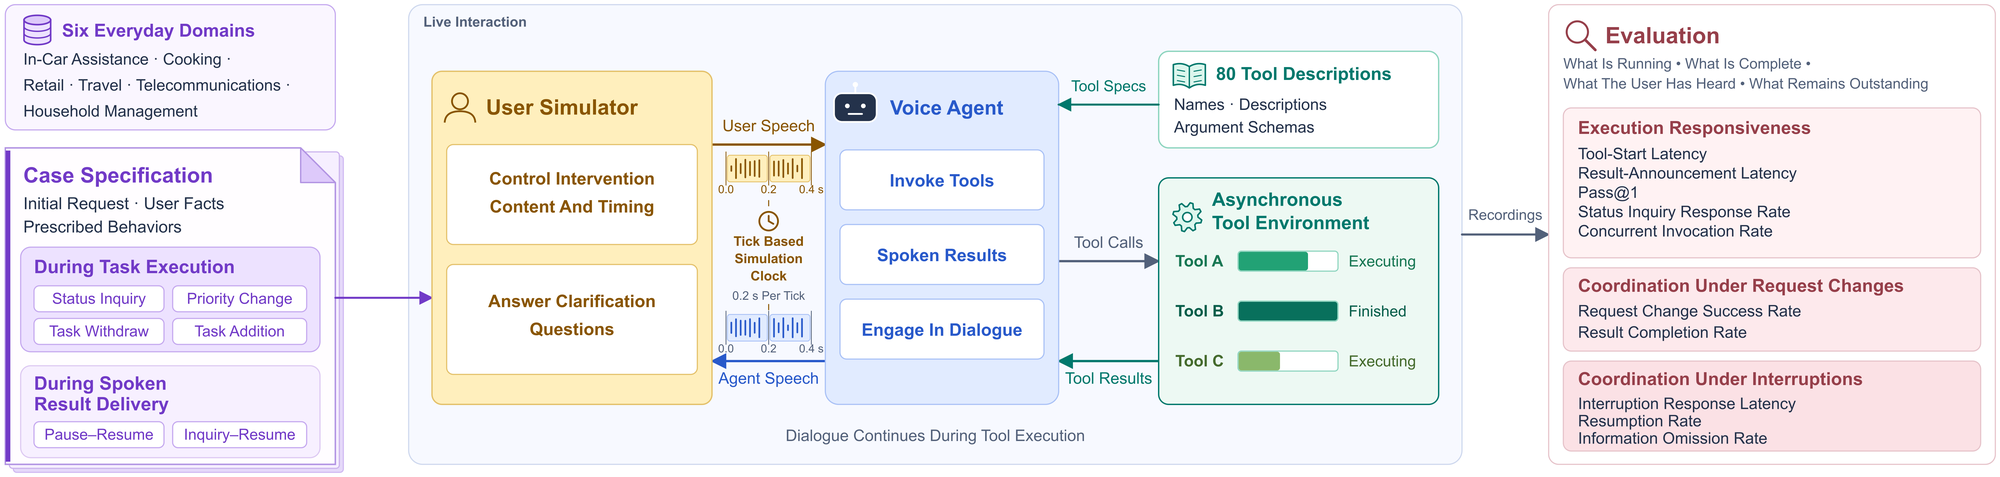
| Joi-Bench-Task | Joi-Bench-Task | Full-duplex voice | Simulated speech with mock asynchronous tools | When to report results; handle changes and interruptions | LLM-and-TTS simulated user with timed interventions | 140 cases from 60 scenarios; 700 conversations | Result completion, omission, resumption; LLM evaluator | Paper |
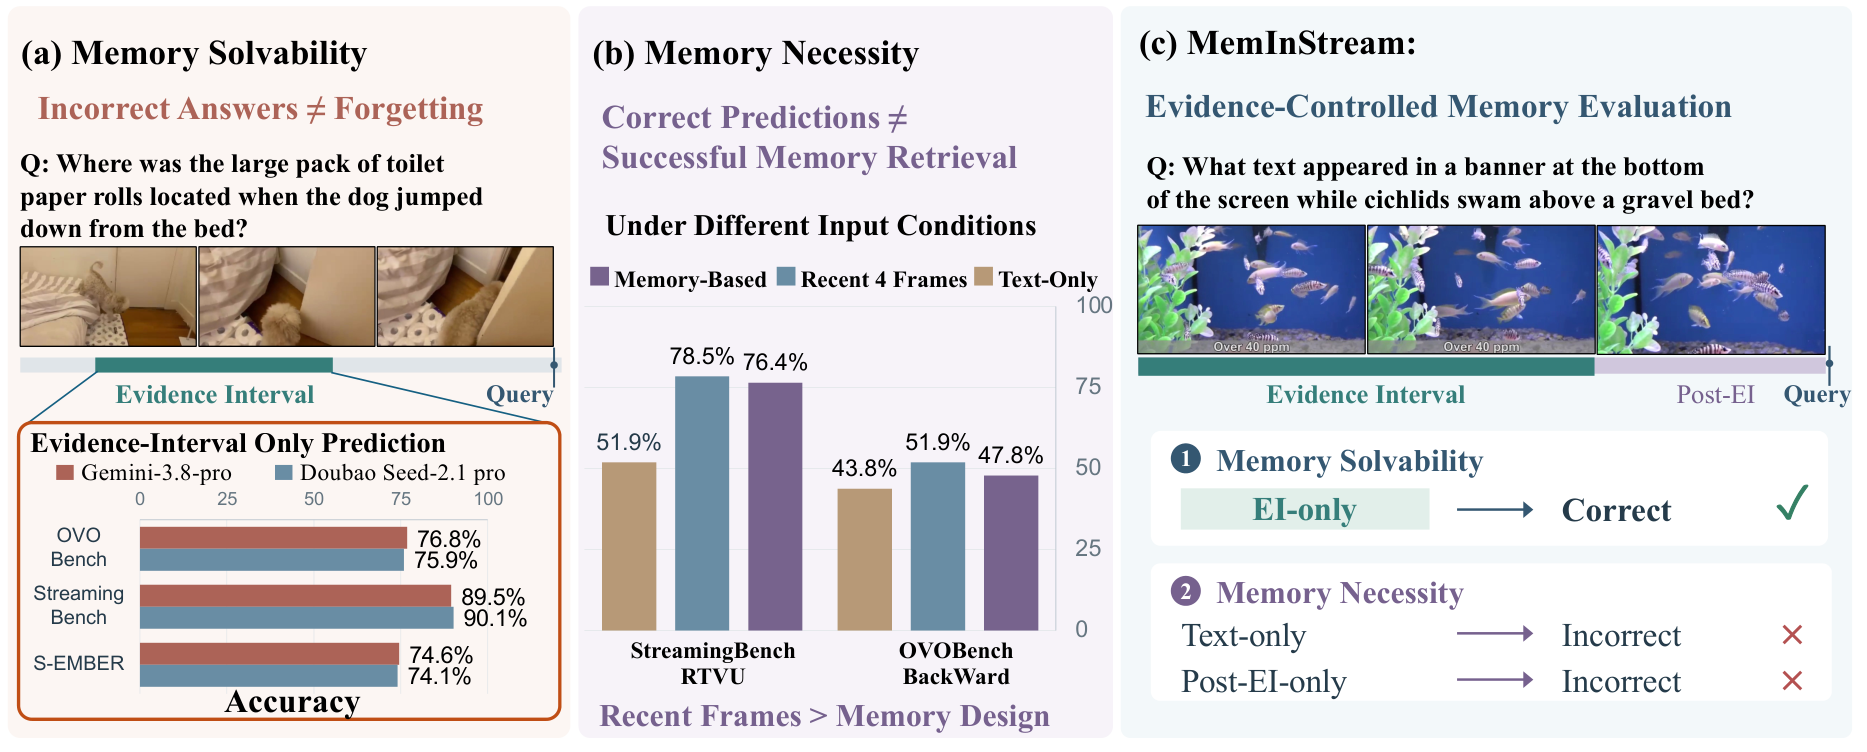
| MemInStream | MemInStream | Streaming video | Causal video with evidence intervals | Answer from retained memory (no initiative decision) | Questions at query timestamps | 3,799 questions, 8,217 evidence intervals, 17 tasks | Exact-set accuracy by task and evidence overlap | Paper Code Dataset |
Selection Guide
| Research Question | Start With | Why |
|---|---|---|
| When should a proactive agent interrupt? | DuplexAct-Bench, Int-Bench, JarvisBench, Live Assistant, PASTABench, PROACTIVITY-GYM, RealHumanEval, Pare-Bench, ProAgentBench | They expose attention needs, active silence, acceptance, disruption, safety windows, or trust effects rather than only final task success. |
| How do we evaluate hidden or changing intent? | Act2Intention Bench, Drift-Bench++, IntentFlux, π-Bench, GUIDE, PIRA-Bench, ProactiveMobile, ProactiveBench | They require agents to infer goals that are incomplete, miscommunicated, or superseded over time. |
| How do we evaluate long-term intent maintenance? | VibeLifeBench, APM-Bench, ChronosBench, Drift-Bench++, VitaBench 2.0, π-Bench | They require persistent state across time or sessions; VibeLifeBench also advances the world while the agent is not being prompted. |
| How do we evaluate personalization? | RobotEQ 3.0, KnowU-Bench, FingerTip 20K, VitaBench 2.0, UserVille, Ψ-Bench | They include profiles, preferences, or user-specific trajectories. |
| How do we evaluate memory as a proactive substrate? | APM-Bench, CogEval-Bench, MemEye, TWIST, VitaBench 2.0, ProActEval | They test memory formation, retrieval, evidence preparation, intent emergence, missing-evidence awareness, or whether memory should trigger an intervention. |
| How do we evaluate computer-use agents? | Act2Intention Bench, CONFLICTGUI, SWE-Intervene, OverAct, ProAgentBench, GUIDE, PIRA-Bench, KnowU-Bench, Pare-Bench, ProCodeBench | They connect proactive behavior to GUI, mobile, IDE, tool calls, or workflow contexts; CONFLICTGUI and OverAct test restraint, while SWE-Intervene tests pre-execution control. |
| How do we evaluate proactive streaming video or speech? | ESTP-Bench, StreamGaze, SOVBench, Live Gaming Benchmark, APM-Bench, DuplexAct-Bench, Live Assistant, TRACE, TIMELI, ProReady-QA, OmniAssistBench, OmniPro, EgoPro-Bench, OmniMMI, StreamArena, IPIBench, EgoServe, StreamSoccer | They require causal processing of an ongoing stream and timely outputs rather than offline clip answering; TRACE audits execution conditions and DuplexAct-Bench adds proactive initiation and active silence. |
| How do we evaluate proactive critique? | RPCBench, MMPCBench, AskBench | They require the assistant to challenge or repair a faulty premise instead of complying silently; RPCBench additionally tests localization, handling strategy, and evidence faithfulness in recommendation. |
| How do we evaluate ask-versus-stop clarification? | FinInteract, IdeaAMBIG, OR-Clarify, ClarifyBench, AskBench | They evaluate whether missing information justifies another question and whether the agent can stop without silently assuming critical information; FinInteract additionally tests whether the answer is integrated under competing valid interpretations. |
| How do we evaluate social intervention outcomes? | ProMediConv, CC-Mediation, ProMediate, ProACT Collaboration Bench | They evaluate intervention strategies or points and downstream collaborative or interpersonal effects rather than response quality alone. |
| How do we evaluate proactive evidence acquisition? | Physical Experiment Selection, Value of Information, Interactive Visual Grounding | They test whether an agent should answer now, ask for information, or acquire another observation, with explicit evidence sufficiency or cost. |